The Big O Cheat Sheet: Decoding Algorithm Efficiency Like a Pro

Big O notation isn’t just academic jargon—it’s the silent architect behind every high-performance application. Whether you’re debugging a sluggish API or architecting a scalable system, understanding Big O helps you predict behavior before writing a single line of code. The difference between O(n) and O(n²) isn’t just theoretical; it’s the margin between a service that handles 10,000 requests and one that collapses under 1,000. Yet, despite its critical role, Big O remains misunderstood by many developers, often reduced to vague assumptions rather than precise tools.
The problem lies in how it’s taught. Most explanations treat Big O as a math exercise, drowning readers in asymptotic analysis while neglecting practical implications. But Big O isn’t about memorizing symbols—it’s about making trade-offs. Should you use a binary search (O(log n)) or a linear scan (O(n))? Why does O(n log n) dominate sorting algorithms? These aren’t abstract questions; they’re decisions that shape user experience, server costs, and even business viability. This guide cuts through the noise, offering a big O cheat sheet that bridges theory and execution, so you can apply complexity analysis like a seasoned engineer.
Think of Big O as a lens: it doesn’t tell you how to solve a problem, but it reveals which solutions will scale—and which will fail spectacularly as data grows. From nested loops that secretly introduce O(n³) to greedy algorithms that hide O(2ⁿ) exponential costs, the cheat sheet below decodes these patterns. No fluff, no oversimplification—just the mechanics, pitfalls, and real-world examples you need to write code that performs under pressure.
The Complete Overview of Big O Notation
Big O notation is the language of algorithmic efficiency, quantifying how runtime or space requirements grow relative to input size. At its core, it’s a worst-case analysis: if an algorithm’s operations scale quadratically with input, O(n²) doesn’t just describe a slow function—it signals a fundamental flaw in design for large datasets. The notation’s power lies in its abstraction; whether you’re processing 100 items or 10 million, O(n log n) consistently predicts behavior, making it indispensable for everything from database queries to machine learning pipelines.Yet, Big O isn’t a silver bullet. It ignores constants (e.g., O(2n) simplifies to O(n)) and lower-order terms (e.g., O(n² + n) becomes O(n²)), which can lead to misplaced confidence. A O(n) algorithm with a hidden 100n constant might outperform a O(log n) solution for small inputs, but the opposite becomes true as n grows. The key is context: Big O helps compare asymptotic growth, not absolute performance. This big O cheat sheet clarifies those nuances, ensuring you wield the notation correctly—whether you’re optimizing a sorting algorithm or evaluating a third-party library’s efficiency claims.
Historical Background and Evolution
The origins of Big O trace back to 19th-century number theory, where mathematicians like Paul Bachmann and Edmund Landau used similar concepts to describe the growth rates of functions. However, it was computer scientist Donald Knuth who formalized Big O in the 1960s as part of his foundational work on algorithm analysis, The Art of Computer Programming. Knuth’s notation wasn’t just a tool—it was a response to the growing complexity of computational problems, providing a way to compare algorithms without getting bogged down in hardware specifics. Before Big O, developers relied on vague terms like "fast" or "slow," leading to inconsistent performance across systems.The adoption of Big O in computer science was revolutionary because it demystified scalability. Early programming languages like Fortran and COBOL lacked built-in optimizations, forcing engineers to manually analyze loops and recursion. As languages evolved, so did the need for a standardized way to discuss efficiency. Today, Big O is taught alongside data structures in introductory CS courses, but its real-world impact extends beyond academia. Companies like Google and Meta use Big O to justify architectural decisions—such as choosing a hash table (O(1) average case) over a binary search tree (O(log n))—because the notation translates directly to cost and user experience. Without it, modern software engineering would lack a common framework to discuss performance.
Core Mechanisms: How It Works
Big O describes the upper bound of an algorithm’s growth rate, focusing on the dominant term as input size approaches infinity. For example, an algorithm with T(n) = 3n² + 2n + 1 is classified as O(n²) because the n² term dominates all others for large n. This simplification is crucial: it allows developers to ignore constants and focus on the fundamental scaling behavior. However, the notation has variants—Big Ω (Omega) for best-case, and Big Θ (Theta) for tight bounds—that refine the analysis. Understanding these distinctions is vital when evaluating algorithms like quicksort, which has O(n²) worst-case but O(n log n) average-case performance.Table of Contents
- The Complete Overview of Big O Notation
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can Big O be used to compare algorithms with different constants?
- Q: Why does recursion often lead to exponential complexity?
- Q: How does Big O relate to real-world performance?
- Q: Are there cases where higher complexity is preferable?
- Q: How can I estimate an algorithm’s Big O without analyzing code?
- Q: What’s the difference between Big O and little o notation?
The practical application of Big O hinges on recognizing patterns in code. A single loop typically indicates O(n), while nested loops suggest O(n²) or worse. Recursive functions often hide exponential costs (O(2ⁿ)) unless optimized with memoization or divide-and-conquer strategies. The big O cheat sheet below distills these patterns into actionable insights, but the deeper lesson is about reading code critically. For instance, a developer might assume a double loop is O(n²) without noticing that the inner loop’s range depends on a constant factor, reducing it to O(n). Such oversights can turn a theoretically efficient algorithm into a performance bottleneck.
Key Benefits and Crucial Impact
Big O notation isn’t just a theoretical construct—it’s a decision-making framework that directly impacts product success. In 2018, Facebook’s engineering team attributed a 10% improvement in ad auction latency to replacing an O(n²) algorithm with an O(n log n) alternative. The change wasn’t about adding more servers; it was about eliminating quadratic growth in a critical path. Similarly, Netflix’s recommendation engine relies heavily on Big O analysis to balance accuracy and speed, ensuring users see suggestions in milliseconds rather than seconds. These examples highlight a fundamental truth: Big O isn’t an optional skill—it’s a competitive advantage.The notation also serves as a bridge between developers and stakeholders. When explaining why a feature might be too slow to scale, referencing O(n³) complexity carries more weight than vague terms like "it’s not efficient." This clarity extends to hiring: companies like Amazon and Jane Street explicitly test candidates on Big O during technical interviews because it reveals how they think about trade-offs. Even in non-technical roles, understanding Big O helps product managers prioritize features based on scalability risks. The impact is clear: those who master Big O can build systems that last, while those who ignore it risk technical debt that spirals out of control.
"Big O is the difference between a system that works for 1,000 users and one that works for 10 million. It’s not about being clever—it’s about being responsible."
—Martin Odersky, Scala Language Designer
Major Advantages
- Predictability: Big O provides a language to discuss scalability without relying on hardware benchmarks. A O(log n) algorithm will consistently outperform O(n) as input size grows, regardless of the machine.
- Design Clarity: It forces developers to question assumptions. For example, why use a bubble sort (O(n²)) when insertion sort (O(n²)) is often faster in practice due to fewer swaps?
- Cost Estimation: Cloud providers like AWS charge based on computational complexity. Understanding Big O helps avoid surprise bills from inefficient algorithms.
- Debugging Efficiency: Slow functions often reveal themselves through Big O analysis. A sudden spike in latency might trace back to an O(n²) operation triggered by a data growth event.
- Algorithm Selection: It guides choices between trade-offs. For instance, a hash table (O(1) average) might be preferable to a balanced tree (O(log n)) for caching, despite the tree’s worst-case guarantees.

Comparative Analysis
| Complexity Class | Real-World Example |
|---|---|
| O(1) – Constant Time | Array indexing (arr[5]), hash table lookups (with good hashing). Ideal for high-frequency operations like leaderboards or session storage. |
| O(log n) – Logarithmic Time | Binary search, balanced tree traversals (e.g., AVL trees). Used in databases for index lookups and divide-and-conquer algorithms. |
| O(n) – Linear Time | Single-loop traversals (e.g., finding a max in an unsorted list), linear search. Acceptable for small n but becomes problematic as datasets grow. |
| O(n²) – Quadratic Time | Nested loops (e.g., bubble sort, matrix multiplication), brute-force string matching. Often a red flag in production systems handling large inputs. |
Future Trends and Innovations
As data volumes explode and edge computing becomes ubiquitous, Big O analysis is evolving to address new challenges. Quantum algorithms, for example, introduce complexity classes like O(2^(n/2)) that defy classical notation, forcing researchers to rethink efficiency metrics. Meanwhile, the rise of approximate computing—where O(ε) (error-tolerant) algorithms trade precision for speed—is blurring the lines between theoretical and practical optimization. Tools like Google’s TensorFlow and Apple’s Core ML already leverage these trade-offs, hinting at a future where Big O isn’t just about minimizing operations but optimizing for real-world constraints like energy use or latency.Another trend is the integration of Big O into DevOps pipelines. Companies are now using static analysis tools to flag inefficient code before deployment, treating complexity as a non-functional requirement alongside reliability. Frameworks like Apache Spark optimize for O(n) distributed processing by design, while serverless architectures implicitly rely on Big O to manage cold starts. The next decade may see Big O embedded in IDEs, where warnings like "This loop could become O(n²) with input size >10⁵" appear in real time, democratizing performance awareness across engineering teams.
Conclusion
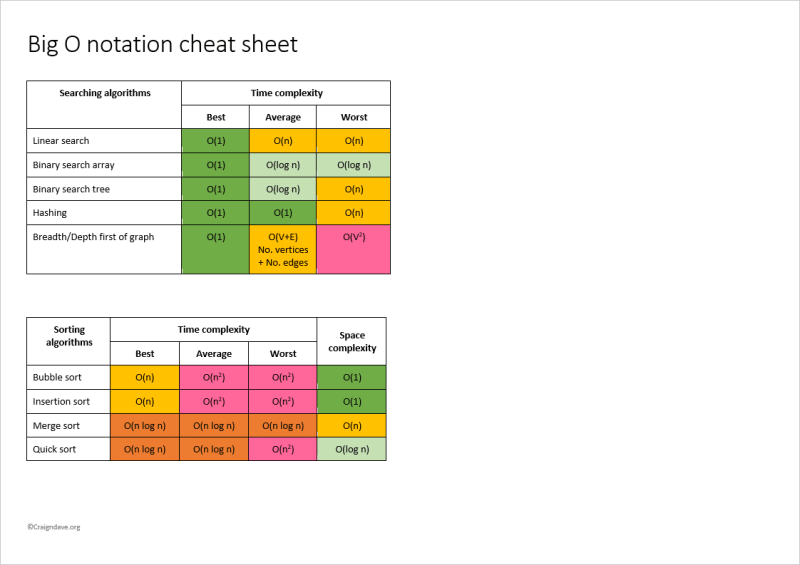
Big O isn’t a static concept—it’s a dynamic lens that reframes how we approach problems. The big O cheat sheet you’ve just reviewed isn’t just a reference; it’s a mindset shift. It teaches you to ask: What happens when the input doubles? or How will this scale in three years? These questions don’t have one-size-fits-all answers, but they force you to consider the long-term implications of your code. Whether you’re optimizing a legacy system or designing a new feature, Big O gives you the vocabulary to make informed trade-offs.The most critical takeaway is this: Big O isn’t about perfection—it’s about awareness. No algorithm is universally optimal, and the best engineers know when to bend the rules. A O(n²) solution might be acceptable for a small dataset, while an O(n log n) algorithm could be overkill for a one-time operation. The goal isn’t to chase the lowest complexity at all costs, but to align your choices with the problem’s constraints. Mastering Big O means you’re no longer at the mercy of performance surprises—you’re in control.
Comprehensive FAQs
Q: Can Big O be used to compare algorithms with different constants?
No, Big O ignores constants because it focuses on asymptotic behavior. For example, O(2n) and O(1000n) are both O(n), even though the latter might be slower for small inputs. To compare such cases, use Big Θ (tight bounds) or empirical benchmarks.
Q: Why does recursion often lead to exponential complexity?
Recursive algorithms can become O(2ⁿ) or worse when each call branches into multiple subproblems (e.g., naive Fibonacci). This happens because the recursion tree grows exponentially with input size. Memoization or dynamic programming can reduce this to O(n) by storing intermediate results.
Q: How does Big O relate to real-world performance?
Big O predicts scalability but not absolute speed. A O(n) algorithm with a high constant factor might outperform a O(log n) algorithm for small n, but the opposite becomes true as n grows. Always test with realistic datasets, as cache effects and hardware optimizations can distort expectations.
Q: Are there cases where higher complexity is preferable?
Yes. For example, a O(n²) algorithm might be simpler to implement and faster for small n than a O(n log n) alternative. Trade-offs depend on context: development time, code maintainability, and expected input sizes all play a role.
Q: How can I estimate an algorithm’s Big O without analyzing code?
Count the number of basic operations (e.g., comparisons, assignments) in the worst case. For loops, multiply their complexities (e.g., two nested loops → O(n) × O(n) = O(n²)). Recursion requires drawing a recursion tree to sum the work across all levels.
Q: What’s the difference between Big O and little o notation?
Big O (O(f(n))) describes an upper bound, while little o (o(f(n))) describes a strict upper bound that isn’t tight. For example, O(n²) includes n² + 100, but o(n²) excludes any function that grows as fast as n² (e.g., n²/2). Little o is rarely used in practice but appears in advanced algorithm analysis.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.