json to csv: The Hidden Bridge Between Data Formats
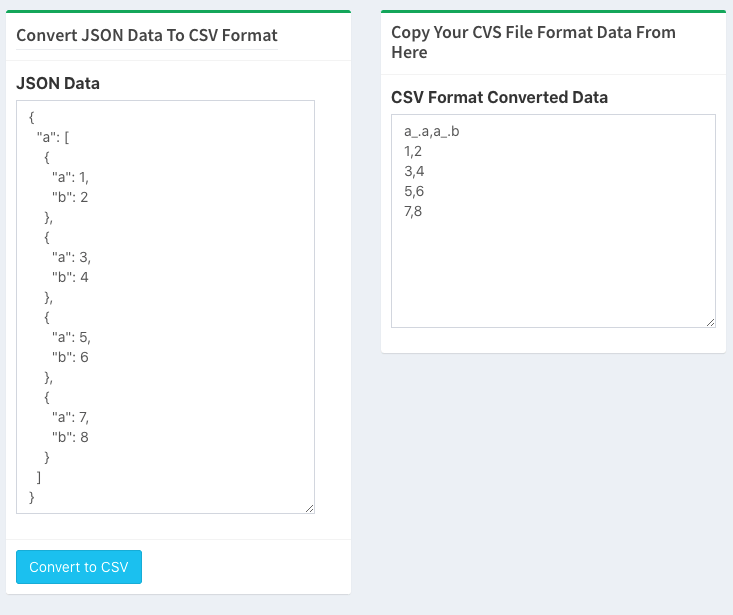
JSON’s nested structures and CSV’s tabular simplicity often clash in real-world workflows. Yet, the ability to transform JSON data into CSV—whether for analytics, reporting, or legacy system compatibility—remains one of the most practical skills in data engineering. The process isn’t just about syntax; it’s about preserving relationships, handling edge cases, and optimizing for performance. Many developers still underestimate how critical this conversion is, assuming it’s a trivial task that can be delegated to generic tools. But the truth is far more nuanced: JSON’s hierarchical nature demands careful flattening, while CSV’s rigid columns require deliberate structuring to avoid data loss.
The demand for JSON to CSV conversions has surged alongside the rise of APIs and microservices. RESTful endpoints often return data in JSON, but traditional tools—like spreadsheets or SQL databases—expect CSV. This mismatch forces engineers to either rewrite queries or manually export data, creating bottlenecks. The solution lies in understanding the underlying mechanics: how JSON’s key-value pairs map to CSV’s row-column model, and how to handle arrays, nested objects, or mixed data types without corruption. Without this knowledge, even simple conversions can fail silently, leading to misaligned datasets or lost information.
Most tutorials oversimplify the process, treating JSON to CSV as a one-size-fits-all operation. But real-world datasets rarely conform to textbook examples. They contain irregular schemas, multi-level nesting, or dynamic fields that break naive conversion scripts. The difference between a functional export and a fragmented one often hinges on preprocessing steps—normalizing structures, resolving circular references, or deciding how to represent JSON arrays in CSV’s flat format. Mastering these techniques isn’t just about writing code; it’s about designing a pipeline that anticipates failure modes before they occur.
The Complete Overview of JSON to CSV
The conversion from JSON to CSV is fundamentally about translating a hierarchical, flexible data format into a tabular, rigid one. JSON’s strength lies in its ability to represent complex relationships—arrays of objects, nested properties, or polymorphic data—whereas CSV thrives in simplicity, with each row representing a single record and columns defining attributes. This tension explains why direct conversions often require intermediate steps: flattening nested structures, resolving ambiguities in field names, or deciding how to handle missing values. The process isn’t just technical; it’s architectural. A poorly designed conversion can turn a clean dataset into a jumbled mess, while a well-architected one ensures reproducibility and scalability.At its core, JSON to CSV is a two-phase operation: parsing and transformation. The parsing phase involves reading the JSON input, whether from a file, API response, or in-memory object, and validating its structure. This step is critical because JSON’s schema-less nature means data can vary wildly—some records might have extra fields, others might omit critical ones. The transformation phase then maps this data into CSV’s grid format, where each column must correspond to a consistent attribute across all rows. Tools like `pandas` in Python or `jq` in the command line handle this automatically, but understanding the mechanics behind these tools reveals why they sometimes fail. For instance, a JSON array like `{"tags": ["data", "engineering"]}` must be either split into multiple columns (e.g., `tags_1`, `tags_2`) or serialized into a single column with delimiters, neither of which is ideal for analysis.
Historical Background and Evolution
The need to convert between JSON and CSV emerged alongside the web’s shift from static HTML to dynamic APIs. In the early 2000s, XML dominated as a data interchange format, but its verbosity and complexity led to JSON’s adoption by 2005–2010, thanks to its lightweight syntax and native support in JavaScript. Meanwhile, CSV remained the de facto standard for spreadsheets and databases, offering a human-readable, delimiter-separated alternative. The first JSON to CSV tools appeared as ad-hoc scripts in Perl or Python, often repurposed from XML-to-CSV converters. These early solutions were fragile, relying on string manipulation rather than structured parsing, and struggled with edge cases like escaped quotes or multi-line values.By the mid-2010s, libraries like `csvkit` (Python) and `jq` (command-line) standardized the process, introducing robust handling of nested data. `csvkit`’s `in2csv` command, for example, could flatten JSON arrays into columns or preserve them as comma-separated strings, while `jq` allowed fine-grained filtering before conversion. This period also saw the rise of NoSQL databases (MongoDB, CouchDB), which stored data in JSON-like BSON, further increasing demand for CSV exports. Today, the conversion is handled by dedicated tools, programming languages, and even cloud services (AWS Glue, Google BigQuery), but the underlying principles remain rooted in the early challenges of bridging structured and semi-structured data.
Core Mechanisms: How It Works
The conversion process begins with parsing the JSON input into a traversable data structure. Most languages provide built-in JSON parsers (e.g., `JSON.parse()` in JavaScript, `json.loads()` in Python), which convert strings into objects or dictionaries. These objects are then processed recursively: for each key-value pair, the algorithm checks whether the value is a primitive (string, number) or a complex type (object, array). Primitives are straightforward—they map directly to CSV columns. Complex types, however, require decisions: should an array be exploded into multiple columns, or should it be serialized as a JSON string? Should nested objects be flattened with dot notation (e.g., `user.address.city`) or preserved as separate rows?Table of Contents
- The Complete Overview of JSON to CSV
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can I convert JSON to CSV without writing code?
- Q: How do I handle arrays in JSON when converting to CSV?
- Q: Why does my CSV have extra columns after converting JSON?
- Q: Can I convert JSON with circular references to CSV?
- Q: How do I ensure my JSON-to-CSV conversion is reversible?
- Q: What’s the fastest way to convert large JSON files to CSV?
- Q: How do I handle special characters (e.g., commas, quotes) in JSON strings when converting to CSV?
- Upload to S3
The second phase involves generating the CSV output. This requires defining a schema—either implicitly (by extracting unique keys from the JSON) or explicitly (by specifying column names). Tools like `pandas` infer schemas dynamically, while custom scripts may enforce strict column orders. The writer then iterates over each record, ensuring that missing fields are represented consistently (e.g., as empty strings or `NULL`). Delimiters, quoting rules, and line endings are configured to match the target system’s expectations, as even minor deviations (e.g., using tabs instead of commas) can corrupt the output. The final step is validation: checking for malformed rows, escaped characters, or truncated data, which often reveals flaws in the original JSON or the conversion logic.
Key Benefits and Crucial Impact
The ability to convert JSON to CSV isn’t just a technical convenience; it’s a bridge between modern data workflows and legacy systems. APIs, web scrapers, and IoT devices increasingly generate JSON, but many downstream tools—ERP systems, BI dashboards, or regulatory reports—still rely on CSV for compatibility. Without this conversion, organizations would face a fragmented data ecosystem, where siloed formats create bottlenecks in analysis, sharing, or compliance. The impact extends beyond IT: finance teams use CSV exports for audits, marketers rely on them for campaign tracking, and researchers depend on them for reproducible datasets. The cost of manual conversion—whether through copy-pasting or error-prone scripts—far outweighs the effort of automating JSON to CSV pipelines.At its best, this conversion enables data democratization. A JSON API response can be transformed into a CSV in seconds, making raw data accessible to non-technical stakeholders who work in Excel or Google Sheets. It also future-proofs workflows: as APIs evolve to return more complex JSON (e.g., GraphQL responses with nested queries), the ability to flatten and structure this data ensures that analytical tools remain relevant. The trade-off—losing some of JSON’s flexibility—is justified by the gains in usability, interoperability, and scalability. Without it, the promise of modern data formats would remain confined to technical teams, while the rest of the organization grapples with outdated tools.
"Data conversion isn’t just about changing formats; it’s about preserving meaning in a way that tools can understand—and people can trust." — Hadley Wickham, Creator of `tidyverse` and `readr`
Major Advantages
- Interoperability: CSV is universally supported by databases, spreadsheets, and statistical tools, making JSON to CSV conversions essential for cross-platform workflows.
- Simplified Analysis: Flat CSV files integrate seamlessly with tools like R, Python (`pandas`), or SQL, where nested JSON would require complex parsing.
- Regulatory Compliance: Many industries (finance, healthcare) mandate CSV exports for audits, and JSON’s dynamic schema can complicate compliance.
- Performance Optimization: Large JSON datasets can be processed more efficiently in CSV format, especially when using columnar storage (e.g., Parquet via `pandas`).
- Human Readability: CSV files are easier to inspect, debug, or share manually compared to minified JSON, reducing onboarding friction for non-technical users.
Comparative Analysis
| JSON | CSV |
|---|---|
|
|
| Conversion Challenge: Flattening nested data without losing relationships. | Conversion Challenge: Handling missing fields or multi-value arrays. |
| Tools: `jq`, `Python (json)`, `Node.js` | Tools: `csvkit`, `pandas`, `OpenRefine` |
Future Trends and Innovations
The next evolution of JSON to CSV will likely focus on automation and intelligence. Today’s tools require manual configuration for complex schemas, but emerging libraries (e.g., `polars` in Rust) are adding automatic schema inference and type handling. Machine learning could further optimize conversions by predicting the best way to flatten nested structures based on usage patterns. For example, a system might detect that `user.tags` is often queried as a list and auto-expand it into columns, while preserving `user.address` as a nested JSON string if it’s rarely accessed.Cloud platforms will also play a larger role, offering serverless functions to trigger JSON to CSV conversions on demand. AWS Lambda or Google Cloud Functions could process API responses in real-time, converting them to CSV for downstream analytics without manual intervention. Additionally, the rise of WebAssembly (WASM) may enable high-performance conversion tools to run in browsers, reducing the need for backend processing. As data volumes grow, these innovations will shift the focus from how to convert to when and why—making the process invisible to end users while ensuring robustness.

Conclusion
The conversion from JSON to CSV is more than a technical step; it’s a critical link in the data pipeline that enables collaboration, analysis, and compliance. While the process has matured with dedicated tools and libraries, its challenges—flattening hierarchies, handling dynamic schemas, and ensuring consistency—remain non-trivial. The key to success lies in understanding the trade-offs: JSON’s flexibility versus CSV’s rigidity, and choosing the right approach based on the use case. Whether you’re exporting API data for a dashboard or migrating a legacy system, the principles of JSON to CSV conversion apply universally.As data ecosystems grow more complex, the ability to bridge these formats will only become more valuable. Investing time in mastering the mechanics—from parsing to schema design—will pay dividends in efficiency, accuracy, and scalability. The tools may evolve, but the core problem remains: how to translate one representation of data into another without losing its essence. For now, the solution lies in careful planning, robust validation, and a deep understanding of both formats’ strengths and limitations.
Comprehensive FAQs
Q: Can I convert JSON to CSV without writing code?
A: Yes. Tools like JSON-CSV.com, ConvertCSV, or browser extensions (e.g., JSON to CSV Converter) offer no-code solutions. However, these may struggle with complex nested data or large files. For production use, a script (Python, JavaScript) is more reliable.
Q: How do I handle arrays in JSON when converting to CSV?
A: Arrays can be converted in three ways:
- Explode into columns: If an array has a fixed length (e.g., `["red", "green"]`), create columns like `color_1`, `color_2`. Use libraries like `pandas` with `json_normalize()`.
- Serialize as JSON strings: Store the entire array in a single column (e.g., `{"tags": ["data", "engineering"]}`). Useful for preserving structure.
- Normalize into rows: Convert each array element into a separate row (one-to-many relationship). Requires denormalization logic.
Q: Why does my CSV have extra columns after converting JSON?
A: This typically happens when:
- The JSON contains inconsistent fields (some records have `user.id`, others don’t). Tools like `pandas` may infer all possible keys as columns, leaving empty cells.
- Nested objects are flattened with dot notation (e.g., `user.address.city`), creating multiple columns for a single logical field.
- The conversion tool doesn’t enforce a schema, leading to dynamic column generation.
Q: Can I convert JSON with circular references to CSV?
A: No, not directly. Circular references (e.g., `{"parent": {"child": {...}, "parent": {...}}}`) cause infinite loops during parsing. Solutions:
- Use a library that detects cycles (e.g., Python’s `json` module with custom recursion limits).
- Preprocess the JSON to break cycles (e.g., replace circular references with IDs).
- Convert only the acyclic portion of the data, excluding circular references from the CSV.
Q: How do I ensure my JSON-to-CSV conversion is reversible?
A: Reversibility requires preserving metadata and structure. Strategies:
- Store nested JSON as a single column (e.g., `metadata: {"key": "value"}`) and use a delimiter (e.g., `|`) to separate fields.
- Encode array indices or nested paths in column names (e.g., `user[0].name`, `user[1].name`).
- Include a schema row in the CSV header to document the original JSON structure.
- Use a hybrid format like TSV with embedded JSON for complex fields.
Q: What’s the fastest way to convert large JSON files to CSV?
A: For files >1GB, optimize with these techniques:
- Streaming: Use tools like `jq` (command-line) or Python’s `ijson` to parse JSON incrementally without loading the entire file into memory.
- Parallel Processing: Split the JSON into chunks, convert each in parallel (e.g., using `multiprocessing` in Python), then merge CSVs.
- Columnar Formats: Convert JSON to Parquet first (using `pandas` or `pyarrow`), then to CSV. Parquet is more efficient for large datasets.
- Hardware Acceleration: Use GPU-optimized libraries like RAPIDS cuDF for faster processing.
Q: How do I handle special characters (e.g., commas, quotes) in JSON strings when converting to CSV?
A: CSV requires escaping delimiters and quotes. Solutions:
- Use a robust library (e.g., Python’s `csv` module or `pandas`) that handles escaping automatically.
- Preprocess JSON strings to replace problematic characters:
- Commas: Escape as `\,` or replace with `|`.
- Quotes: Escape as `\"` or use a different delimiter (e.g., `;`).
- Newlines: Replace with `\n` or use a pipe (`|`) as a delimiter.
- Configure the CSV writer to use a non-standard delimiter (e.g., `;` instead of `,`) if the data contains commas.
Q: Can I convert JSON to CSV in a serverless environment (e.g., AWS Lambda)?h3>
A: Yes. Example workflow:
- Trigger Lambda on an API response or S3 upload (via EventBridge).
- Use Python’s `json` and `csv` modules or `pandas` to convert the JSON to CSV in memory.
- Store the CSV in S3, send it to a queue (SQS), or stream it to a database.
- Optimize for cold starts by keeping dependencies small (e.g., use `pandas` with `--no-deps` or a lightweight alternative like `polars`).
```python
import json
import csv
import boto3
def lambda_handler(event, context):
json_data = json.loads(event['body'])
csv_bytes = []
writer = csv.writer(csv_bytes)
writer.writerow(json_data[0].keys()) # Header
for record in json_data:
writer.writerow(record.values())
Upload to S3
s3 = boto3.client('s3')s3.put_object(Bucket='your-bucket', Key='output.csv', Body=''.join(csv_bytes))
return {'statusCode': 200}
```
For large files, use S3 streams or chunked processing.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.