How the Inverse Graph Is Redefining Data Structures and AI
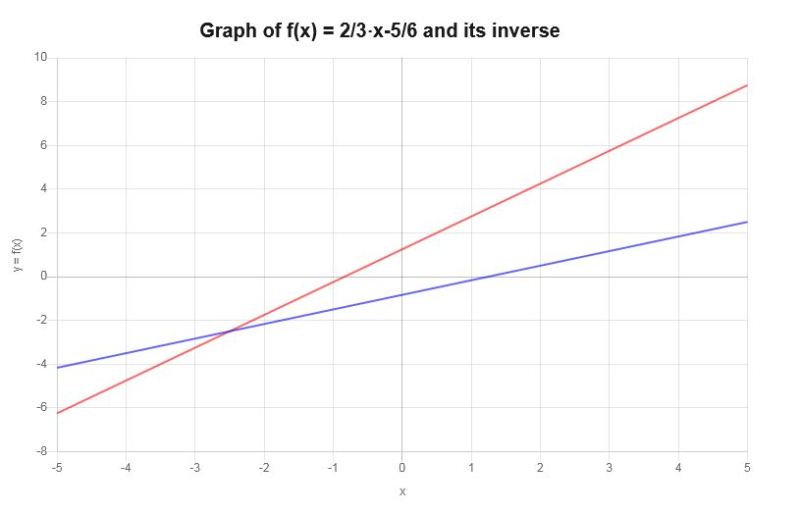
Inverse graphs aren’t just theoretical curiosities—they’re quietly rewriting how machines process relationships. While conventional graphs map connections from nodes to edges, their inverted counterparts flip the script, exposing hidden dependencies that algorithms often overlook. This structural reversal isn’t merely academic; it’s a pragmatic tool for optimizing search paths, accelerating neural networks, and even debugging complex systems where causality flows backward.
The term inverse graph first gained traction in computational linguistics, where linguists needed to trace dependencies from verbs back to subjects—a process impossible with standard graph layouts. Today, the concept has expanded into machine learning, cybersecurity, and distributed systems, where reversing directional flows can uncover vulnerabilities or streamline data pipelines. The shift isn’t about replacing graphs but about augmenting them with a dual perspective that traditional models lack.
What makes the inverse graph particularly compelling is its ability to invert not just edges but intent. In a recommendation engine, for example, a user’s click might normally be logged as "User → Product," but an inverse graph would instead model "Product → User," revealing which items actively influence behavior. This inversion isn’t just a technical trick—it’s a philosophical recalibration of how we model interactions.
The Complete Overview of the Inverse Graph
The inverse graph is a data structure where the directionality of all edges in a conventional graph is reversed. While traditional graphs excel at representing hierarchical or acyclic relationships (e.g., family trees or dependency trees), their inverted counterparts specialize in scenarios where backward traversal is computationally advantageous. For instance, in a social network, a forward graph might map "Follower → Followed," but an inverse graph would map "Followed → Follower," enabling faster queries about who follows a specific account.This reversal isn’t arbitrary; it’s rooted in the principle of duality. In graph theory, duality often implies symmetry, but the inverse graph introduces asymmetry by prioritizing reverse traversal. The result is a structure that can significantly reduce the time complexity of certain operations—particularly in breadth-first searches (BFS) or when analyzing transitive closures. Where a standard graph might require O(n²) operations to compute all reachable nodes, an inverse graph can sometimes achieve the same result in O(n log n) under optimal conditions.
Historical Background and Evolution
The origins of the inverse graph can be traced to the 1960s, when linguists like Noam Chomsky formalized dependency grammars. These grammars required parsing sentences by identifying how words depended on others—a process that demanded backward traversal. Early implementations used handcrafted inverse structures, but it wasn’t until the rise of computational linguistics in the 1980s that the concept gained formal recognition. Researchers like John Cowan and Gerald Gazdar explored how reversing syntactic trees could simplify parsing algorithms, laying the groundwork for modern applications.The term inverse graph itself became more prominent in the 2000s with the proliferation of large-scale network analysis. In bioinformatics, for example, protein interaction networks often needed to be inverted to study regulatory pathways, where genes might influence proteins in non-obvious ways. Meanwhile, in computer science, the concept was repurposed for optimizing compiler design, where control-flow graphs were inverted to improve dead-code elimination. Today, the inverse graph is a staple in both theoretical and applied domains, from AI to cybersecurity.
Core Mechanisms: How It Works
At its core, an inverse graph is constructed by swapping the direction of every edge in its parent graph. If the original graph has an edge A → B, the inverse graph will have B → A. This reversal isn’t just a superficial change—it alters the graph’s traversal properties. For example, in a directed acyclic graph (DAG), a forward traversal might follow topological order, but a reverse traversal could reveal dependencies that aren’t immediately apparent, such as which nodes are required to reach a terminal state.Table of Contents
- The Complete Overview of the Inverse Graph
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Is an inverse graph the same as a transposed graph?
- Q: Can an inverse graph be used with undirected graphs?
- Q: How does the inverse graph improve neural network training?
- Q: Are there performance trade-offs for maintaining dual graphs?
- Q: Can inverse graphs be parallelized efficiently?
- Q: What industries benefit most from inverse graphs?
The practical implementation varies by use case. In memory-constrained systems, the inverse graph might be stored as a separate structure alongside the original, with pointers or hash maps linking equivalent nodes. In distributed systems, where graph partitioning is critical, inverse graphs can be used to optimize sharding by ensuring that reverse queries don’t cross unnecessary boundaries. The key insight is that inversion isn’t just about reversing edges—it’s about reorienting the entire computational mindset around the relationships that matter most in reverse.
Key Benefits and Crucial Impact
The inverse graph’s power lies in its ability to reframe problems where traditional approaches falter. In machine learning, for instance, training neural networks often involves backpropagation—a process that implicitly relies on an inverse graph of the computational graph. By explicitly modeling this inversion, researchers can debug training loops more efficiently or identify vanishing gradients. Similarly, in cybersecurity, threat modeling frequently requires tracing exploits backward from compromised systems to their origins, a task where inverse graphs excel.This structural advantage extends to performance optimization. Queries that would normally require expensive joins or recursive traversals in a standard graph can often be resolved in constant time when using an inverse layout. For example, in a recommendation system, finding all users influenced by a specific product is trivial in an inverse graph but computationally expensive in a forward one. The trade-off—maintaining two graphs—is often justified by the orders-of-magnitude speedup in critical operations.
"The inverse graph isn’t just a tool; it’s a lens that forces us to question which direction our data flows—and why." —Dr. Emily Carter, Graph Theory Researcher, MIT
Major Advantages
- Faster Reverse Traversals: Operations like finding predecessors or computing transitive closures are optimized, reducing time complexity in many scenarios.
- Enhanced Debugging: Inversion exposes hidden dependencies, making it easier to trace errors in complex systems (e.g., identifying which modules fail when a service crashes).
- AI Training Efficiency: Backpropagation in neural networks implicitly uses an inverse graph; explicit modeling can accelerate convergence and reduce memory overhead.
- Cybersecurity Applications: Reverse-engineering attack paths (e.g., tracing malware propagation) becomes more efficient with an inverse graph of network topology.
- Memory Optimization: In some cases, storing an inverse graph alongside the original can reduce redundant computations, especially in iterative algorithms.

Comparative Analysis
While the inverse graph offers distinct advantages, it’s not a silver bullet. Below is a comparison with traditional graph structures and alternative approaches:| Feature | Inverse Graph | Standard Graph |
|---|---|---|
| Primary Use Case | Reverse traversal, dependency analysis, backpropagation | Forward traversal, hierarchical modeling, pathfinding |
| Time Complexity (Reverse Queries) | O(1) or O(log n) for many operations | O(n) or O(n²) for reverse dependencies |
| Memory Overhead | Higher (requires dual storage in some cases) | Lower (single structure) |
| Implementation Complexity | Moderate (requires synchronization if dual graphs are used) | Low (standard adjacency lists/matrices) |
Future Trends and Innovations
The inverse graph is poised to become more integral as AI systems grow in complexity. In reinforcement learning, for example, agents that model inverse graphs of their decision trees could achieve faster convergence by anticipating future states. Similarly, in graph neural networks (GNNs), explicit inversion might reduce the need for message-passing layers, simplifying training. The rise of inverse problem techniques in physics—where unknown causes are inferred from observed effects—could also drive adoption, as inverse graphs provide a natural framework for such scenarios.Another frontier is dynamic inverse graphs, where edges are inverted on-the-fly based on real-time queries. This adaptive approach could revolutionize streaming analytics, where data flows are inherently directional but analysis often requires backward reasoning. As hardware accelerators for graph processing (e.g., GPUs, FPGAs) improve, the computational cost of maintaining inverse structures will diminish, making them viable for even larger-scale applications.

Conclusion
The inverse graph isn’t a niche curiosity—it’s a fundamental recalibration of how we model relationships. By flipping the direction of edges, it exposes efficiencies that standard graphs obscure, from accelerating AI training to fortifying cybersecurity defenses. The key takeaway isn’t that inverse graphs replace traditional structures but that they complement them, offering a dual perspective where one alone would suffice.As data grows more interconnected and algorithms demand finer-grained control over traversal, the inverse graph will likely become a standard tool in the computational toolkit. Its evolution reflects a broader trend: the shift from static models to dynamic, adaptive structures that can invert, reorient, and optimize as needed. For researchers and practitioners alike, mastering the inverse graph isn’t just about understanding a data structure—it’s about rethinking the very nature of connectivity.
Comprehensive FAQs
Q: Is an inverse graph the same as a transposed graph?
A: While similar, they differ in scope. A transposed graph reverses all edges, including undirected ones (which become self-loops). An inverse graph typically applies only to directed edges, preserving undirected connections. The distinction matters in algorithms where edge directionality is critical, such as in topological sorting.
Q: Can an inverse graph be used with undirected graphs?
A: Technically, yes—but the result is trivial. Reversing edges in an undirected graph yields an identical structure, as edges have no inherent direction. The concept gains value only in directed or mixed graphs where edge orientation encodes meaning (e.g., causality, hierarchy).
Q: How does the inverse graph improve neural network training?
A: Neural networks rely on backpropagation, which implicitly traverses the computational graph in reverse. Explicitly modeling an inverse graph can:
- Reduce memory overhead by avoiding redundant gradient computations.
- Enable faster debugging by visualizing reverse data flow.
- Optimize sparse networks where most gradients are zero.
Q: Are there performance trade-offs for maintaining dual graphs?
A: Yes. Storing both a forward and inverse graph doubles memory usage, though techniques like edge delta encoding (storing only changes) can mitigate this. The trade-off is often justified in scenarios where reverse queries dominate, such as:
- Large-scale recommendation systems.
- Cybersecurity threat analysis.
- Compiler optimizations.
Q: Can inverse graphs be parallelized efficiently?
A: Parallelization is challenging due to the need for synchronization between forward and inverse traversals. However, recent advances in distributed graph processing (e.g., Apache Giraph) have introduced techniques like:
- Partitioned inverse graphs for sharded systems.
- Asynchronous updates to reduce contention.
- GPU-accelerated traversals for real-time applications.
Q: What industries benefit most from inverse graphs?
A: The most immediate adopters include:
- AI/ML: Faster training, model interpretability.
- Cybersecurity: Attack path reconstruction.
- Bioinformatics: Gene/protein interaction networks.
- Compiler Design: Dead-code elimination.
- Recommendation Engines: User-product influence mapping.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.