Mastering Python Write to File: A Deep Dive into File Operations
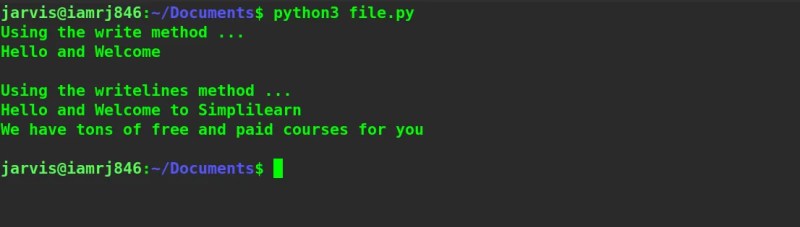
Python’s ability to interact with files is foundational for data persistence, logging, and configuration management. Whether you’re storing user-generated content, processing large datasets, or maintaining application state, understanding how to write data to files in Python is non-negotiable. The language’s built-in file handling capabilities are both powerful and flexible, yet their subtleties—such as encoding pitfalls, permission handling, and atomicity—often lead to inefficiencies or errors if overlooked.
The process of writing to a file in Python isn’t just about executing a single command; it’s a workflow that involves mode selection, context management, and error resilience. Developers frequently encounter scenarios where naive implementations fail under edge cases—such as concurrent access, large file sizes, or non-ASCII text. These challenges underscore the need for a systematic approach to file operations, one that balances simplicity with robustness.
At its core, writing to a file in Python is a bridge between memory and storage, but the implementation details dictate performance, reliability, and maintainability. From the low-level `open()` function to higher-level abstractions like `pathlib`, the ecosystem offers multiple pathways—each with trade-offs in readability, control, and efficiency.
The Complete Overview of Python Write to File
Python’s file writing capabilities are built on a combination of simplicity and sophistication. The language provides multiple methods to write data to files, ranging from the traditional `open()` function with explicit modes to modern alternatives like `pathlib` and `with` statements for resource management. These tools are designed to handle everything from small text logs to massive binary datasets, but their effective use requires an understanding of underlying mechanisms—such as buffering, file descriptors, and system-level permissions.The most common approach involves the `open()` function, which accepts a file path, a mode string (e.g., `'w'`, `'a'`, `'x'`), and optional parameters like encoding or buffering. While this method is straightforward, it demands careful handling of exceptions and context management to prevent resource leaks. Modern Python (3.4+) encourages the use of `with` statements, which automatically close files upon exiting the block, mitigating one of the most common pitfalls in file operations.
Historical Background and Evolution
File handling in Python has evolved alongside the language itself. Early versions of Python (pre-2.0) relied on a more cumbersome API, where file objects lacked many of the conveniences we take for granted today. The introduction of context managers (`with` statements) in Python 2.5 marked a turning point, enabling cleaner and safer file operations. This change was particularly impactful for developers working with large files or network resources, where manual resource cleanup was error-prone.The transition to Python 3 further refined file handling, with stricter type handling (e.g., `bytes` vs. `str` for binary/text modes) and improved Unicode support. The `pathlib` module, introduced in Python 3.4, provided an object-oriented interface to filesystem paths, abstracting away much of the low-level complexity. These advancements reflect Python’s commitment to balancing backward compatibility with modern best practices, ensuring that file operations remain both intuitive and powerful.
Core Mechanisms: How It Works
Under the hood, writing to a file in Python involves several layers of abstraction. When you call `open()`, Python interacts with the operating system’s file descriptor, which manages the actual data transfer. The mode string (e.g., `'w+'`) determines whether the file is created, truncated, or appended to, while buffering controls how data is flushed to disk. For example, line buffering (`line_buffering=True`) is efficient for text files but may introduce latency for binary data.Table of Contents
- The Complete Overview of Python Write to File
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: What’s the difference between `'w'` and `'a'` modes in Python file writing?
- Q: How do I handle encoding issues when writing non-ASCII text to a file?
- Q: Why should I use `with` statements for file operations?
- Q: Can I write binary data using Python’s file writing methods?
- Q: What’s the best way to write large files efficiently in Python?
- Q: How do I handle file permission errors when writing to a directory?
- Q: Are there performance differences between `write()` and `writelines()`?
- Q: Can I write to a file asynchronously in Python?
The `with` statement leverages Python’s context management protocol to ensure files are properly closed, even if an exception occurs. This is critical for performance and system stability, as unclosed files can lead to resource exhaustion. Additionally, Python’s file objects support methods like `write()`, `writelines()`, and `seek()`, offering granular control over file positioning and data injection.
Key Benefits and Crucial Impact
The ability to write to files in Python is a cornerstone of data-driven applications. Whether you’re logging application events, serializing objects for storage, or generating reports, file operations enable persistence and interoperability. This functionality is particularly valuable in scenarios where in-memory data must be preserved across sessions or shared between processes. Without file writing, many modern applications—from web servers to data pipelines—would struggle to maintain state or recover from failures.Beyond persistence, file writing in Python facilitates cross-platform compatibility. By adhering to standard file formats (CSV, JSON, XML), developers can ensure their applications interact seamlessly with other systems. The language’s built-in support for encoding (UTF-8, ASCII, etc.) further reduces friction in internationalized environments, where character sets vary widely.
"File operations are the unsung heroes of programming—they’re the silent force that turns ephemeral data into lasting assets."
— Guido van Rossum (Python Creator)
Major Advantages
- Simplicity and Readability: Python’s syntax for file writing is concise, reducing cognitive overhead for developers. A single line (`with open('file.txt', 'w') as f: f.write('data')`) encapsulates the entire workflow.
- Automatic Resource Management: The `with` statement ensures files are closed promptly, preventing memory leaks and system instability.
- Flexible Data Handling: Support for both text and binary modes allows Python to process everything from plaintext logs to complex binary formats like images or executables.
- Cross-Platform Compatibility: Python’s file operations abstract OS-specific details, ensuring consistent behavior across Windows, Linux, and macOS.
- Performance Optimizations: Buffering and chunked writing techniques minimize disk I/O, improving efficiency for large files.
Comparative Analysis
| Method | Use Case |
|---|---|
| `open()` with `with` | Best for most scenarios—clean, safe, and explicit. Ideal for text and binary files with automatic resource cleanup. |
| `pathlib.Path.write_text()` | Modern alternative for text files; offers a more intuitive object-oriented interface. |
| Manual file handling (without `with`) | Avoid unless necessary; prone to resource leaks and requires explicit `.close()` calls. |
| Third-party libraries (e.g., `pandas` for CSV) | Specialized for structured data (e.g., DataFrames to CSV/Excel); adds abstraction but may introduce dependencies. |
Future Trends and Innovations
The future of file writing in Python is likely to focus on two fronts: performance and integration. As data volumes grow, libraries like `aiofiles` (asynchronous file I/O) will become more prevalent, enabling non-blocking operations in concurrent applications. Additionally, Python’s continued emphasis on type hints and static analysis may lead to more robust file handling APIs, reducing runtime errors through early validation.Another emerging trend is the convergence of file operations with cloud storage systems. Frameworks like `boto3` (AWS) and `google-cloud-storage` are already bridging the gap between local and remote file systems, but future iterations may offer more seamless abstractions. For instance, a unified API for writing to local files, S3 buckets, or distributed storage like HDFS could become standard, further abstracting infrastructure concerns.

Conclusion
Python’s file writing capabilities are a testament to the language’s design philosophy: powerful yet accessible. Whether you’re a beginner writing logs or an experienced developer optimizing data pipelines, understanding the nuances of `python write to file` operations is essential. The key lies in balancing simplicity with best practices—using context managers, handling exceptions, and choosing the right tools for the job.As Python continues to evolve, so too will its file handling ecosystem. Staying informed about emerging trends—such as async I/O and cloud-native storage—will ensure your applications remain efficient and future-proof. For now, mastering the fundamentals of file writing in Python provides a solid foundation for nearly any data-driven task.
Comprehensive FAQs
Q: What’s the difference between `'w'` and `'a'` modes in Python file writing?
The `'w'` mode opens a file for writing, truncating it to zero length if it already exists. In contrast, `'a'` mode appends data to the end of the file without overwriting existing content. Use `'w'` for new files or when you want to overwrite, and `'a'` for logging or incremental updates.
Q: How do I handle encoding issues when writing non-ASCII text to a file?
Always specify the encoding parameter in `open()`, e.g., `open('file.txt', 'w', encoding='utf-8')`. UTF-8 is the most widely supported encoding for international text. If you omit encoding, Python defaults to platform-specific behavior, which can cause errors or garbled text.
Q: Why should I use `with` statements for file operations?
The `with` statement ensures the file is automatically closed when the block exits, even if an exception occurs. This prevents resource leaks and is considered a best practice for all file operations in Python.
Q: Can I write binary data using Python’s file writing methods?
Yes. Use `'wb'` mode for binary writing (e.g., `open('image.png', 'wb')`). This bypasses text encoding and allows direct manipulation of bytes, making it ideal for images, executables, or serialized objects.
Q: What’s the best way to write large files efficiently in Python?
For large files, use chunked writing to avoid memory overload. Instead of writing all data at once, loop through chunks and call `write()` incrementally. Alternatively, leverage buffered I/O by adjusting the `buffering` parameter in `open()`.
Q: How do I handle file permission errors when writing to a directory?
Check write permissions for the target directory using `os.access(path, os.W_OK)`. If permissions are insufficient, either modify them with `os.chmod()` or ensure your application has the necessary privileges (e.g., running as an admin on Windows).
Q: Are there performance differences between `write()` and `writelines()`?
`write()` is generally faster for single operations, as it processes data in one call. `writelines()` is better for iterating over sequences (e.g., lists of strings), but it may introduce overhead if not used efficiently. For large datasets, consider buffering or async methods.
Q: Can I write to a file asynchronously in Python?
Yes, using libraries like `aiofiles`. This allows non-blocking file operations in async contexts (e.g., asyncio). Example:
```python
import aiofiles
async with aiofiles.open('file.txt', 'w') as f:
await f.write('async data')
```
Q: How do I ensure atomic writes in Python (no partial data on failure)?h3>
For atomicity, use temporary files with `os.replace()`. Write to a temp file first, then rename it to the target path. This ensures either full success or no change if an error occurs.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.