How Python Logging Transforms Debugging and Application Lifecycle Management

Python’s built-in logging module is often overlooked in favor of flashier frameworks, yet it remains the backbone of observability in Python applications. Unlike ad-hoc print statements scattered across codebases, python logging provides a standardized, configurable system for tracking runtime behavior, errors, and system health. Its flexibility—from simple console output to enterprise-grade log aggregation—makes it indispensable for developers, DevOps engineers, and security teams alike.
The module’s design anticipates real-world needs: hierarchical loggers, customizable formatters, and handlers that route logs to files, databases, or external services. This isn’t just about debugging; it’s about building systems that self-document their operations, a critical feature as applications scale. Even Python’s standard library relies on it—modules like `requests`, `Django`, and `FastAPI` integrate python logging to surface internal states without forcing developers to reinvent the wheel.
The Complete Overview of Python Logging
At its core, python logging is a framework for recording events that occur when software runs. Unlike print statements, which are static and context-free, logging is dynamic: it adapts to the severity of messages (debug, info, warning, error, critical), filters irrelevant data, and persists records for later analysis. The module’s architecture is modular—loggers generate messages, handlers direct them to destinations, and formatters standardize their structure.What sets python logging apart is its granularity. You can configure separate log levels for different components of an application (e.g., high verbosity for development, minimal output in production) without rewriting code. This adaptability extends to logging handlers: while the default `StreamHandler` sends logs to `stderr`, custom handlers can forward messages to cloud services like AWS CloudWatch or Elasticsearch, enabling centralized monitoring.
Historical Background and Evolution
The origins of python logging trace back to Python 2.3 (released in 2003), where it was introduced as a replacement for the older `logging` module from the `logging` package. The redesign addressed key limitations: the new module supported hierarchical loggers (allowing parent-child relationships to propagate messages), configurable propagation rules, and thread-safe operations—a necessity as Python’s concurrency models matured.Early adopters recognized its potential beyond debugging. For instance, the Python Software Foundation used python logging to track issues in CPython’s development cycle, while web frameworks like Django adopted it to standardize error reporting. Over time, the module evolved to include features like `QueueHandler` (for async logging) and `QueueListener` (to process logs in separate threads), reflecting growing demands for scalability in distributed systems.
Core Mechanisms: How It Works
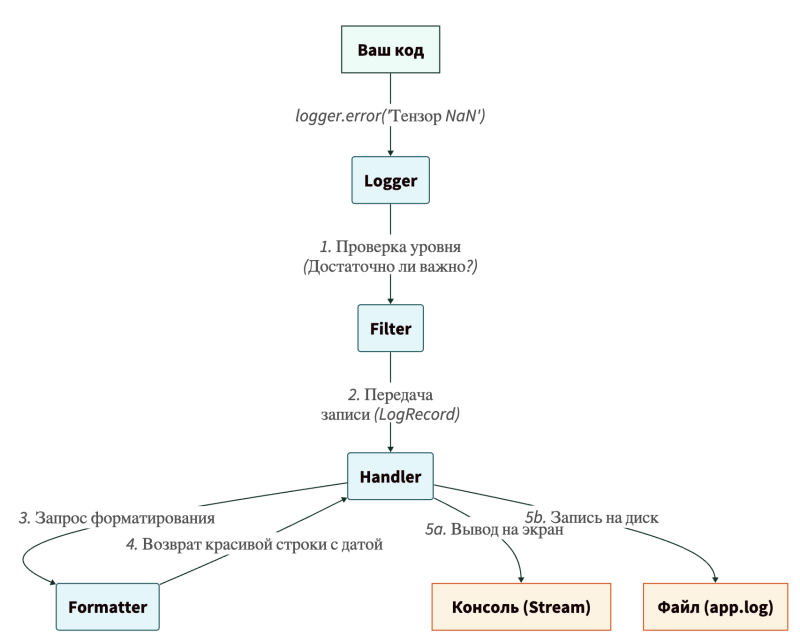
The python logging module operates on three primary components:1. Loggers: The entry point for logging messages. Each logger has a name (typically a dot-separated path like `app.module`) and a severity level (e.g., `WARNING`). Loggers can inherit settings from parent loggers (e.g., `app.module` inherits from `app`).
2. Handlers: Direct messages to specific destinations. Common handlers include `FileHandler` (writes to files), `NullHandler` (discards messages), and `SysLogHandler` (sends logs to a Unix syslog daemon).
3. Formatters: Define the structure of log messages. A basic formatter might output timestamps, log levels, and messages, while advanced setups include JSON for machine parsing or structured fields for observability tools.
The flow is linear: a logger emits a message, handlers attached to it process it, and formatters shape its output. For example, a `DEBUG` message from `app.database` might bypass a `FileHandler` configured for `WARNING` level or higher, thanks to the logger’s threshold settings.
Key Benefits and Crucial Impact
Python logging isn’t just a utility—it’s a force multiplier for software reliability. In development, it reduces the time spent diagnosing issues by providing contextual traces of execution. In production, it becomes a lifeline during outages, offering forensic data to pinpoint root causes. The module’s integration with Python’s ecosystem (e.g., `structlog` for structured logging, `Sentry` for error tracking) further extends its utility.Table of Contents
- The Complete Overview of Python Logging
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How do I configure Python logging to write to both a file and the console?
- Q: Can Python logging be used for security auditing?
- Q: Why does my logger not appear to be working?
- Q: How do I log exceptions with context in Python?
- Q: What’s the difference between `logging` and `print()`?
- print() (static, no control)
The real value lies in standardization. Without python logging, teams would rely on inconsistent `print()` calls or third-party libraries with proprietary formats. This fragmentation complicates debugging and monitoring. By contrast, a unified logging system ensures that every engineer, from juniors to architects, works with the same toolset.
"Logging isn’t just for debugging—it’s for telling the story of your application’s lifecycle. Without it, you’re flying blind in production."
— Guido van Rossum (Python Creator)
Major Advantages
- Hierarchical Organization: Loggers inherit settings from ancestors, reducing boilerplate. For example, `app.api` can override `app`’s default level without reconfiguring all handlers.
- Performance Optimization: Disabled loggers (via `propagate=False`) prevent unnecessary message processing, critical for high-throughput systems.
- Extensibility: Custom handlers (e.g., `HTTPHandler` for remote logging) or formatters (e.g., JSON for ELK stacks) adapt to any infrastructure.
- Thread Safety: The module’s design ensures thread-local loggers, avoiding race conditions in concurrent applications.
- Security Compliance: Structured logging (e.g., with `structlog`) meets audit requirements by embedding metadata like user IDs or timestamps in machine-readable formats.

Comparative Analysis
While python logging is robust, alternatives exist for specific needs. Below is a comparison of key logging systems:| Feature | Python Logging | Log4j (Java) | Winston (Node.js) |
|---|---|---|---|
| Hierarchical Loggers | Yes (dot-separated names) | Yes (logger hierarchy) | No (flat loggers) |
| Async Logging | Yes (`QueueHandler`) | Yes (async loggers) | Yes (stream-based) |
| Structured Output | Requires `structlog` | Native JSON layout | Native JSON support |
| Integration with Observability | Extensible (e.g., `elasticapm`) | Built-in appenders | Third-party transports |
Future Trends and Innovations
The next frontier for python logging lies in observability integration. Tools like OpenTelemetry are blurring the lines between logging, metrics, and tracing, and Python’s logging module is evolving to support this. Projects like `opentelemetry-python` now allow logs to be exported as traces, enabling correlated debugging across microservices.Another trend is serverless logging, where handlers route messages to AWS Lambda or Google Cloud Functions for real-time processing. As Python dominates cloud-native development (e.g., via FastAPI and serverless frameworks), python logging will need to adapt to ephemeral, event-driven architectures—likely through standardized formats like OpenTelemetry’s semantic conventions.
Conclusion
Python logging is more than a debugging tool—it’s a cornerstone of maintainable, observable software. Its balance of simplicity and power makes it a default choice for Python projects, from scripts to large-scale systems. By leveraging its hierarchical design, handlers, and formatters, teams can future-proof their applications against complexity.The key takeaway? Treat logging as an investment, not an afterthought. Configure it early, standardize formats, and integrate it with your observability pipeline. The result is software that not only runs but also tells its story—clearly, reliably, and at scale.
Comprehensive FAQs
Q: How do I configure Python logging to write to both a file and the console?
Use multiple handlers attached to the same logger. For example:
```python
import logging
logger = logging.getLogger(__name__)
logger.setLevel(logging.DEBUG)
# Console handler
console_handler = logging.StreamHandler()
console_handler.setLevel(logging.INFO)
# File handler
file_handler = logging.FileHandler('app.log')
file_handler.setLevel(logging.DEBUG)
# Common formatter
formatter = logging.Formatter('%(asctime)s - %(name)s - %(levelname)s - %(message)s')
console_handler.setFormatter(formatter)
file_handler.setFormatter(formatter)
logger.addHandler(console_handler)
logger.addHandler(file_handler)
```
This setup logs `DEBUG` messages to the file and `INFO+` to the console.
Q: Can Python logging be used for security auditing?
Yes, but with precautions. Structured logging (e.g., with `structlog`) is ideal for auditing, as it embeds metadata like user actions, timestamps, and IP addresses in JSON. Avoid logging sensitive data (passwords, tokens) directly; use hashing or masking. For compliance, pair logging with tools like `AWS CloudTrail` or `Splunk` to archive and analyze logs centrally.
Q: Why does my logger not appear to be working?
Common issues include:
Q: How do I log exceptions with context in Python?
Use `logging.exception()` for stack traces or `logging.error()` with `exc_info=True`:
```python
try:
risky_operation()
except ValueError as e:
logger.error("Failed to process data: %s", e, exc_info=True)
```
For custom context, include it in the message:
```python
logger.error("User %s failed to %s: %s", user_id, action, e, exc_info=True)
```
Q: What’s the difference between `logging` and `print()`?
`print()` is synchronous, context-free, and lacks features like levels, handlers, or filtering. Python logging is asynchronous-capable, supports hierarchical organization, and integrates with monitoring systems. For example:
```python
print() (static, no control)
print("Error: Invalid input")# logging (dynamic, configurable)
logger.error("Invalid input received from %s", request.ip)
```
Logging scales; `print()` does not.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.