Python’s `mean()` Explained: What Does It Mean in Python and How to Use It
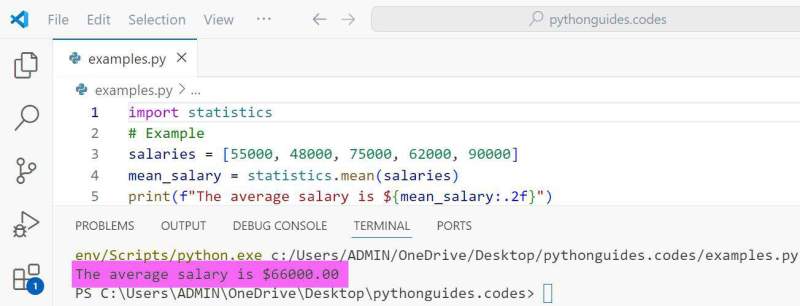
Python’s `mean()` function is more than just a simple arithmetic operation—it’s a statistical workhorse embedded in libraries like NumPy and Pandas. When developers ask, "What does mean in Python really do?", they’re often probing deeper than the surface-level average calculation. The function’s behavior varies subtly depending on the library, data type, and underlying algorithms, making it a critical yet underappreciated tool for analysts, engineers, and scientists.
At its core, `mean()` computes the arithmetic mean, but its implementation details—such as handling missing values, floating-point precision, or axis-wise operations—can drastically alter results. For example, a Pandas `mean()` on a DataFrame column ignores `NaN` by default, while NumPy’s version raises an error unless explicitly configured. These distinctions matter when scaling from small datasets to large-scale machine learning pipelines.
The ambiguity around "what does mean in Python" extends beyond syntax. Developers must also consider edge cases: How does `mean()` behave with empty arrays? What about non-numeric data? The answers lie in understanding Python’s ecosystem of numerical computing tools, where `mean()` is just one facet of a broader statistical toolkit.
The Complete Overview of Python’s Mean Function
Python’s `mean()` function is a specialized method for calculating the arithmetic mean of numerical data, but its functionality is distributed across libraries. NumPy’s `np.mean()` and Pandas’ `Series.mean()` or `DataFrame.mean()` are the most widely used, each with distinct behaviors. While all compute the average, their handling of data structures, missing values, and performance optimizations differ significantly. For instance, Pandas’ `mean()` is designed for labeled data with optional axis alignment, whereas NumPy prioritizes raw array operations with strict type consistency.The function’s versatility stems from its adaptability to different contexts. In data cleaning, it might flag outliers; in machine learning, it could normalize features. Yet, its simplicity masks complexity—such as how floating-point arithmetic affects precision or how axis parameters reshape multi-dimensional calculations. Understanding these nuances is essential for avoiding subtle bugs in production systems.
Historical Background and Evolution
The concept of the arithmetic mean dates back to ancient mathematics, but its implementation in Python evolved with the rise of scientific computing. Early Python lacked native statistical functions, so developers relied on third-party libraries like SciPy or manual loops. The turning point came with NumPy’s introduction in 2006, which standardized vectorized operations, including `mean()`. This shift democratized data analysis by eliminating the need for low-level C loops.Pandas, launched in 2010, further refined `mean()` for tabular data, adding features like axis selection and `skipna` parameters. These innovations addressed real-world gaps: NumPy’s `mean()` couldn’t handle mixed data types, while Pandas’ version could aggregate columns while ignoring `NaN` values. Today, the function’s evolution reflects Python’s role as the lingua franca of data science, balancing performance with usability.
Core Mechanisms: How It Works
Under the hood, `mean()` leverages optimized C/Fortran libraries (via NumPy) to compute the sum of elements divided by their count. For a 1D array, this is straightforward:```python
import numpy as np
data = np.array([1, 2, 3])
print(np.mean(data)) # Output: 2.0
```
However, multi-dimensional arrays introduce complexity. The `axis` parameter specifies which dimensions to reduce, enabling operations like row-wise or column-wise averages. For example:
```python
matrix = np.array([[1, 2], [3, 4]])
print(np.mean(matrix, axis=0)) # Column means: [2.0, 3.0]
```
Pandas extends this with labeled data, where `axis=0` computes column means and `axis=1` computes row means, while `skipna=True` (default) excludes `NaN` values during aggregation.
Key Benefits and Crucial Impact
The `mean()` function’s impact spans industries, from finance (calculating portfolio returns) to healthcare (analyzing patient metrics). Its efficiency—thanks to vectorized operations—reduces computation time from hours to milliseconds for large datasets. Moreover, its integration with Pandas enables seamless workflows in exploratory data analysis (EDA), where summarizing statistics like mean, median, and standard deviation are routine.Table of Contents
- The Complete Overview of Python’s Mean Function
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How does `np.mean()` handle complex numbers?
- Q: Why does Pandas’ `mean()` return a float even for integer columns?
- Q: Can I compute a weighted mean in Python without SciPy?
- Q: What’s the difference between `mean()` and `median()` in skewed distributions?
- Q: How do I mean-center data (subtract the mean) in Python?
Yet, its power comes with responsibility. Misapplying `mean()`—such as ignoring skewed distributions or treating ordinal data as interval—can lead to misleading insights. The function’s simplicity belies the need for statistical literacy, reinforcing Python’s role as both a tool and a pedagogical platform.
"The mean is the most misunderstood statistic in data science. It’s not just an average—it’s a lens through which we interpret variability, central tendency, and even bias in datasets." — Hadley Wickham, Chief Scientist at RStudio (adapted for Python context)
Major Advantages
- Performance Optimization: NumPy’s `mean()` uses BLAS/LAPACK libraries for near-instantaneous calculations on large arrays, outperforming manual Python loops by orders of magnitude.
- Data Integrity: Pandas’ `skipna` parameter ensures robustness against missing values, a critical feature for real-world datasets where `NaN` is ubiquitous.
- Flexibility: The `axis` parameter supports multi-dimensional operations, from time-series aggregation to image processing (e.g., averaging pixel values across channels).
- Ecosystem Integration: Compatibility with libraries like SciPy (for weighted means) and scikit-learn (for feature scaling) makes `mean()` a cornerstone of the Python data stack.
- Readability: Semantic naming (`mean()` vs. manual summation) improves code clarity, reducing cognitive load for collaborative projects.

Comparative Analysis
| Feature | NumPy `np.mean()` | Pandas `Series.mean()` |
|---|---|---|
| Handling of `NaN` | Raises `ValueError` unless `nan` parameter is set. | Ignores `NaN` by default (`skipna=True`). |
| Multi-Dimensional Support | Requires explicit `axis` parameter (e.g., `axis=0` for columns). | Automatically aligns with DataFrame axes (e.g., `axis=0` for columns). |
| Weighted Averages | Supported via `weights` parameter (SciPy extension). | Not natively supported; requires manual weighting. |
| Performance | Optimized for raw arrays (microsecond latency for 1M elements). | Slower for large DataFrames due to label alignment overhead. |
Future Trends and Innovations
As Python’s data ecosystem matures, `mean()` will likely see enhancements in two areas: hardware acceleration and automated statistical validation. Libraries like CuPy (GPU-accelerated NumPy) are already enabling `mean()` computations on NVIDIA GPUs, reducing latency for massive datasets. Meanwhile, tools like Polars or DuckDB may introduce optimized `mean()` variants for query-based analytics, blending SQL-like syntax with Python’s flexibility.Another frontier is context-aware means, where functions adapt to data type (e.g., geometric mean for multiplicative processes) or domain (e.g., trimmed mean for robust statistics). As Python solidifies its dominance in AI/ML, `mean()` may evolve into a meta-function that auto-selects the most appropriate aggregation method based on input data characteristics.

Conclusion
Python’s `mean()` function exemplifies the language’s ability to balance simplicity with sophistication. Whether you’re calculating descriptive statistics, preprocessing data, or validating models, understanding its mechanics—from NumPy’s low-level optimizations to Pandas’ high-level abstractions—is non-negotiable. The function’s evolution mirrors Python’s broader trajectory: a tool that grows more powerful yet remains accessible to practitioners across disciplines.For those asking, "What does mean in Python?", the answer is no longer just about arithmetic. It’s about leveraging a function that bridges mathematics, engineering, and domain expertise—all while adhering to Python’s philosophy of readability and pragmatism.
Comprehensive FAQs
Q: How does `np.mean()` handle complex numbers?
NumPy’s `mean()` treats complex numbers as two separate arrays (real and imaginary parts) and computes the mean of each. For example, `np.mean([1+2j, 3+4j])` returns `(2+3j)`, the element-wise average. This behavior differs from mathematical conventions where complex means are less common.
Q: Why does Pandas’ `mean()` return a float even for integer columns?
Pandas prioritizes consistency over precision. Since division in floating-point arithmetic can produce non-integer results (e.g., `[1, 2, 3]` → `2.0`), the function defaults to `float64` to avoid truncation. To force integer output, use `astype(int)` post-calculation or Pandas’ `mean().round()`.
Q: Can I compute a weighted mean in Python without SciPy?
Yes. Use NumPy’s `np.average()` with the `weights` parameter:
```python
data = [10, 20, 30]
weights = [0.2, 0.3, 0.5]
print(np.average(data, weights=weights)) # Output: 23.0
```
For Pandas, multiply values by weights before calling `mean()`:
```python
df['weighted'] = df['values'] df['weights']
print(df['weighted'].mean())
```
Q: What’s the difference between `mean()` and `median()` in skewed distributions?
The `mean()` is sensitive to outliers, pulling the average toward extreme values in skewed data (e.g., income distributions). The `median()` (50th percentile) is robust to skew. For example, in `[1, 2, 3, 100]`, `mean()` = 27.75 while `median()` = 2.5. Use `median()` for skewed data; `mean()` only when data is symmetric.
Q: How do I mean-center data (subtract the mean) in Python?
Subtract the mean from each value to center data around zero:
```python
data = np.array([1, 2, 3])
centered = data - np.mean(data) # Result: [-1, 0, 1]
```
In Pandas:
```python
df_centered = df - df.mean()
```
This is a common preprocessing step for algorithms like PCA or linear regression.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.