Mastering Python Replace: The Definitive Guide to String Manipulation

Python’s string replacement capabilities are the unsung backbone of text processing in data science, automation, and web development. Whether you’re sanitizing user input, generating dynamic content, or parsing logs, the ability to replace substrings with precision is non-negotiable. Unlike lower-level languages where string operations require manual memory management, Python abstracts complexity into elegant methods—str.replace(), regex substitutions, and even dictionary-based replacements—each serving distinct use cases with varying trade-offs.
The challenge lies not in the existence of these tools, but in their strategic deployment. A poorly optimized Python replace operation can cripple performance in large-scale applications, while overcomplicating simple tasks with regex when a straightforward method suffices. The line between efficiency and over-engineering is thin, and mastering it demands both theoretical knowledge and practical experimentation.
Consider this: a financial analyst processing 10,000 CSV rows might use replace() to standardize currency symbols, while a cybersecurity engineer could leverage regex to scrub malicious payloads from logs. The same core mechanism—replacing text in Python—serves wildly different domains, yet the principles governing its application remain consistent. This guide dissects those principles, from foundational syntax to edge-case optimizations, ensuring you wield Python’s replacement tools with authority.
The Complete Overview of Python Replace
At its core, Python replace refers to the suite of techniques for modifying strings by substituting target substrings with new values. Python provides three primary avenues for this: the built-in str.replace() method, regex-based substitutions via re.sub(), and more specialized approaches like dictionary translations. Each method excels in specific scenarios—replace() for simplicity, regex for pattern matching, and dictionaries for bulk transformations.
The choice between these methods hinges on three factors: performance requirements, complexity tolerance, and the nature of the data. For instance, replace() is ideal for literal string swaps (e.g., replacing "USD" with "$"), while regex shines when dealing with variable-length patterns (e.g., extracting all email addresses). Ignoring these distinctions can lead to maintainability nightmares or performance bottlenecks, particularly in production environments where string operations occur at scale.
Historical Background and Evolution
The concept of string replacement predates Python itself, emerging in early programming languages like BASIC and C. However, Python’s approach—emphasizing readability and built-in functionality—set it apart. Guido van Rossum’s design philosophy prioritized developer experience, leading to the inclusion of str.replace() in Python 1.0 (1991) as a straightforward, non-destructive operation. This method mirrored the simplicity of Unix tools like sed, but with Python’s object-oriented elegance.
Table of Contents
- The Complete Overview of Python Replace
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can str.replace() handle overlapping matches?
- Q: How does str.translate() compare to regex for bulk replacements?
- Q: Why does replace() return a new string instead of modifying in-place?
- Q: Can I use regex to replace only the first occurrence?
- Q: What’s the most efficient way to replace multiple substrings?
- Q: How do I replace Unicode characters in Python?
Regex support arrived later with the re module (Python 1.5, 1995), borrowing heavily from Perl’s powerful pattern-matching syntax. This integration was revolutionary, allowing developers to perform complex substitutions (e.g., replacing all occurrences of a date format) without reinventing the wheel. The evolution didn’t stop there: Python 3.8 introduced the str.translate() method, enabling dictionary-based replacements with O(1) lookup efficiency—a boon for internationalization and data cleaning tasks.
Core Mechanisms: How It Works
The str.replace() method operates by scanning the input string for all non-overlapping occurrences of a substring (the first argument) and replacing them with a second substring. It returns a new string, leaving the original unchanged—a hallmark of Python’s immutable strings. Under the hood, this involves iterating through the string’s Unicode code points, comparing sequences, and constructing a result buffer. The time complexity is O(nm), where n is the string length and m* is the substring length, making it inefficient for large or repetitive patterns.
Regex substitutions, via re.sub(pattern, repl, string), extend this concept by interpreting the first argument as a regular expression. The engine compiles the pattern into a finite automaton, then processes the string in a single pass, replacing matches as it goes. This approach is far more flexible—supporting wildcards, quantifiers, and lookarounds—but trades predictability for power. For example, re.sub(r'\d{3}-\d{2}-\d{4}', 'XXX-XX-XXXX', 'SSN: 123-45-6789') would mask a social security number, whereas str.replace() could only handle exact matches.
Key Benefits and Crucial Impact
Python’s string replacement capabilities are a double-edged sword: they simplify tasks that would otherwise require hundreds of lines of code, yet their misuse can introduce subtle bugs or performance drags. The impact spans industries—from automating report generation in finance to cleaning messy datasets in healthcare. For example, a Python script replacing placeholders in a template with real-time data can reduce manual errors by 90%, while a poorly optimized regex might choke under high load.
The real value lies in understanding when to leverage each method. str.replace() is the Swiss Army knife for 80% of use cases, regex handles the remaining 15%, and advanced techniques like str.translate() address niche scenarios. The cost of misjudgment? Debugging sessions that spiral into hours of trial-and-error, or production outages caused by untested substitutions.
"The art of programming is the art of organizing complexity, of mastering multitude and mastering simplicity." —Edsger Dijkstra
This adage encapsulates the philosophy behind Python’s replacement tools: simplicity for common tasks, power for edge cases.
Major Advantages
- Readability:
str.replace()requires no additional imports and is self-documenting. For example,text.replace('old', 'new')is instantly understandable, whereas regex demands familiarity with metacharacters. - Performance for Simple Cases: For exact substring replacements,
replace()outperforms regex due to lower overhead. Benchmarks show it can be 2-3x faster for non-patterned data. - Safety: Immutability ensures the original string remains unaltered, preventing side effects in concurrent or functional programming contexts.
- Flexibility with Regex: Patterns like
re.sub(r'\s+', ' ', text)collapse multiple whitespace characters into a single space—a task impossible withreplace()alone. - Scalability: Methods like
str.translate()enable bulk replacements (e.g., converting all ASCII punctuation to Unicode) with O(n) efficiency, critical for large datasets.
Comparative Analysis
| Method | Use Case |
|---|---|
str.replace(old, new) |
Exact substring replacements (e.g., "foo" → "bar"). Ideal for simple, predictable text. |
re.sub(pattern, repl, string) |
Pattern-based replacements (e.g., emails, dates, or complex formats). Essential for parsing unstructured data. |
str.translate(table) |
Bulk character mappings (e.g., case conversion, punctuation normalization). Optimized for O(1) lookups. |
| Dictionary Comprehension | Conditional replacements (e.g., replacing words based on a lookup table). Useful for NLP or data validation. |
Future Trends and Innovations
The future of Python replace operations lies in two directions: performance optimizations and AI-assisted text manipulation. As Python continues to adopt JIT compilation (via PyPy or GraalPython), even regex-heavy operations may see dramatic speedups. Meanwhile, libraries like fuzzywuzzy are blurring the line between exact and approximate string matching, enabling "smart" replacements that account for typos or dialectal variations.
Another frontier is the integration of machine learning. Tools like Hugging Face’s transformers could soon allow developers to replace text not just by pattern, but by semantic intent—imagine a system that automatically corrects jargon in technical documents or localizes slang in global applications. While these advances are nascent, they underscore a broader trend: Python’s replacement tools are evolving from syntactic utilities to cognitive assistants.

Conclusion
Python’s string replacement ecosystem is a testament to the language’s balance of simplicity and sophistication. Whether you’re a beginner replacing placeholders in a script or a data scientist cleaning gigabytes of text, the right tool exists—if you know where to look. The key takeaway? Default to str.replace() for clarity, escalate to regex for patterns, and reserve advanced methods for performance-critical scenarios. The cost of premature optimization is high, but so is the cost of ignoring Python’s built-in power.
As you refine your approach to replacing text in Python, remember: the goal isn’t just to write code that works, but code that works efficiently, scalably, and maintainably. The tools are at your fingertips—now it’s time to wield them with precision.
Comprehensive FAQs
Q: Can str.replace() handle overlapping matches?
A: No. The method replaces non-overlapping occurrences only. For overlapping matches (e.g., replacing "aa" in "aaa"), use regex with lookaheads: re.sub('(?=aa)', 'X', 'aaa').
Q: How does str.translate() compare to regex for bulk replacements?
A: translate() is faster for large-scale character mappings (e.g., converting all digits to asterisks) because it uses a precomputed translation table. Regex, while flexible, compiles patterns on each call, adding overhead.
Q: Why does replace() return a new string instead of modifying in-place?
A: Python strings are immutable for thread safety and predictability. Modifying them in-place would risk race conditions in multi-threaded environments. Instead, methods return new objects.
Q: Can I use regex to replace only the first occurrence?
A: Yes. Pass a function to re.sub() with a counter: re.sub(r'pattern', lambda m: 'replacement', text, count=1).
Q: What’s the most efficient way to replace multiple substrings?
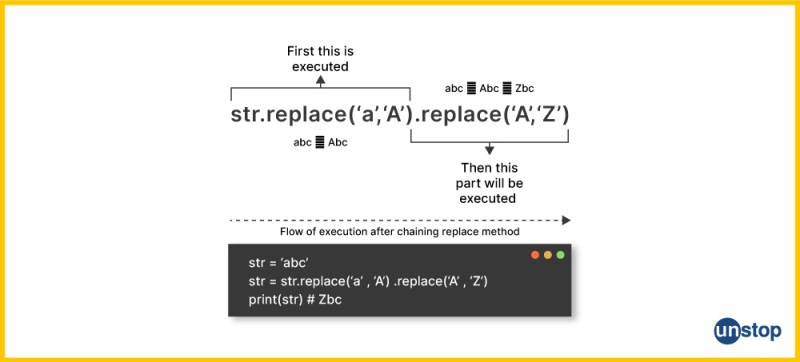
A: For static replacements, chain replace() calls. For dynamic ones, use a dictionary with str.translate() or a regex with alternations: re.sub(r'old1|old2|old3', 'new', text).
Q: How do I replace Unicode characters in Python?
A: Use str.replace() with Unicode escape sequences (e.g., text.replace('\u2018', "'")) or translate() with a Unicode normalization form (e.g., unicodedata.normalize('NFKC', text)).
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.