How Python’s xrange Revolutionized Iteration—And Why It Still Matters
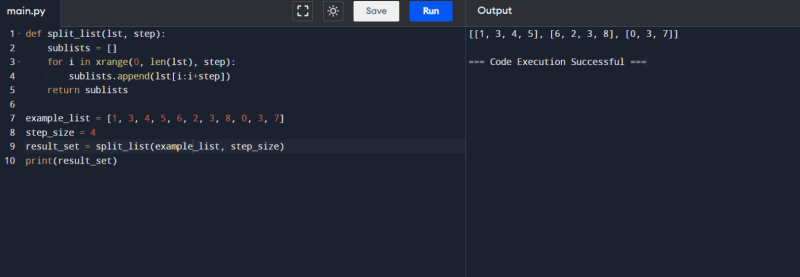
Python’s `xrange` was never just another function—it was a paradigm shift in how sequences were generated and consumed. Before its introduction, iterating over large datasets in Python required brute-force approaches, often leading to memory bloat and sluggish execution. The `xrange` object, with its lazy evaluation model, redefined efficiency by generating values on demand rather than precomputing them. This wasn’t merely an optimization; it was a philosophical departure from the imperative mindset of earlier Python versions, where sequences were treated as static, fully materialized entities. Developers who mastered `xrange` gained not just performance but a deeper intuition for how Python’s iteration protocols could be leveraged without sacrificing readability.
The irony of `xrange` lies in its obscurity today. In Python 3, it was absorbed into the `range` function, rendering it a relic for many. Yet its legacy persists in the design of generators, iterators, and even modern data pipelines where lazy loading is non-negotiable. To dismiss `xrange` as outdated is to overlook the foundational principles it embedded into Python’s DNA—principles that now underpin everything from NumPy’s memory-mapped arrays to asynchronous data streams. Understanding its mechanics isn’t just nostalgia; it’s a lens through which to critique and optimize contemporary Python code.
What follows is an exhaustive breakdown of `xrange`: its technical underpinnings, the problems it solved, and why its disappearance in Python 3 doesn’t diminish its relevance. Whether you’re debugging legacy systems, teaching iteration concepts, or simply curious about Python’s evolution, this analysis will equip you with the context to wield `xrange`-inspired techniques effectively.
The Complete Overview of Python’s xrange
Python’s `xrange` emerged as a direct response to the limitations of traditional sequence iteration in Python 2.x. At its core, it was an immutable sequence type that generated values dynamically during iteration, rather than storing them in memory as a list would. This distinction was critical for performance-critical applications where sequences spanned millions of elements—imagine iterating over a range of 100 million integers. A list-based approach would consume prohibitive memory, whereas `xrange` would yield each value only when requested, reducing memory overhead by orders of magnitude. Its design was rooted in the principle of lazy evaluation, a concept borrowed from functional programming that Python later adopted more broadly with generators and iterators.The `xrange` object wasn’t just a performance hack; it was a deliberate architectural choice. It implemented the iterator protocol, meaning it could be used in `for` loops, `map()`, and other iteration contexts without requiring explicit conversion to a list. This seamless integration with Python’s iteration ecosystem made it a cornerstone for writing concise, efficient code. Developers could write `for i in xrange(1000000):` without worrying about memory constraints, knowing that each `i` would be computed on the fly. The trade-off was minimal: `xrange` objects were immutable and couldn’t be indexed directly (e.g., `xrange(10)[5]` would raise a `TypeError`), but this restriction was a small price for the gains in scalability.
Historical Background and Evolution
The origins of `xrange` can be traced to Python’s early days, when memory efficiency was a secondary concern to syntactic simplicity. In Python 2.x, the built-in `range()` function created a list of integers, which was convenient but impractical for large ranges. The `xrange` function was introduced in Python 2.4 (2004) as a stopgap solution, offering the same interface as `range()` but returning an `xrange` object instead. This duality—where `range()` and `xrange()` could be used interchangeably in most contexts—created confusion but also allowed for gradual migration to the more memory-efficient approach.The decision to phase out `xrange` in Python 3 was driven by two key factors: unification and modernization. By Python 3.0 (2008), the `range()` function was redefined to behave like `xrange`—returning a range object that implemented the iterator protocol and didn’t store all values in memory. This change wasn’t just about cleaning up the language; it reflected a broader trend toward making Python’s iteration model more consistent and easier to understand. The `xrange` name was dropped to avoid cognitive dissonance, but the underlying mechanics lived on. Today, when you use `range()` in Python 3, you’re indirectly invoking the same lazy-evaluation logic that once defined `xrange`.
Core Mechanisms: How It Works
Under the hood, `xrange` was a thin wrapper around a stateful iterator that tracked the current position, stop value, and step size. When iteration began, the object didn’t compute the entire sequence; instead, it maintained a counter (`start`, `stop`, `step`) and yielded values one at a time. For example, `xrange(10, 20, 2)` would produce values 10, 12, 14, 16, 18 by incrementing the counter by 2 each time, without ever storing the full sequence. This approach minimized memory usage while preserving the ability to iterate indefinitely (within hardware limits) without precomputing results.Table of Contents
- The Complete Overview of Python’s xrange
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Why was `xrange` removed in Python 3?
- Q: Can I still use `xrange` in Python 3?
- Q: What’s the memory difference between `xrange` and `range()` in Python 2?
- Q: Does `range()` in Python 3 support indexing like `range()` in Python 2?
- Q: Are there modern alternatives to `xrange` for custom sequences?
- Q: How does `xrange` compare to NumPy’s `arange`?
- Q: Can `xrange` be used in parallel or multithreaded code?
The true elegance of `xrange` lay in its adherence to Python’s iterator protocol. It implemented `__iter__()` to return itself and `__next__()` (or `__next__` in Python 2) to generate the next value in the sequence. This design allowed `xrange` objects to be used in any context expecting an iterator, from `for` loops to `zip()` operations. The lack of a `__getitem__` method was a deliberate choice—it enforced the lazy-evaluation model and prevented accidental materialization of the entire sequence. Developers had to embrace iteration rather than indexing, a pattern that later became a best practice in Python’s data pipelines.
Key Benefits and Crucial Impact
The adoption of `xrange` marked a turning point in Python’s performance profile, particularly for algorithms with large or infinite sequences. Before its introduction, developers often resorted to workarounds like nested loops or external libraries to avoid memory exhaustion. With `xrange`, these problems became trivial to solve: iterating over a billion elements was no longer a gamble on system stability. The impact extended beyond raw performance; it encouraged a shift toward functional-style programming in Python, where operations were expressed in terms of transformations over iterators rather than mutable data structures.The `xrange` model also influenced the design of Python’s standard library. Functions like `map()`, `filter()`, and `zip()` were optimized to work efficiently with iterators, knowing that their inputs might not be fully materialized. This interoperability made `xrange` a linchpin for writing scalable code, especially in domains like numerical computing, where datasets often dwarf available memory. Even today, libraries like NumPy and Pandas leverage similar lazy-evaluation principles to handle large arrays without loading them entirely into RAM.
"xrange wasn’t just an optimization—it was a cultural shift. It taught Python developers that sequences don’t have to be materialized to be useful, and that’s a lesson that applies far beyond iteration."
— Guido van Rossum (Python’s BDFL, in a 2009 mailing list discussion)
Major Advantages
- Memory Efficiency: `xrange` avoided storing the entire sequence in memory, making it feasible to iterate over ranges with billions of elements. For example, `xrange(108)` would consume negligible memory compared to `range(108)`, which would require ~800MB of RAM.
- Performance for Large Ranges: Since values were generated on demand, iteration speed was consistent regardless of range size. No upfront computation meant faster startup times for loops.
- Compatibility with Iteration Protocols: `xrange` objects could be used anywhere an iterator was expected, including `for` loops, list comprehensions, and higher-order functions like `map()` and `filter()`.
- Encouraged Functional Patterns: By making lazy evaluation the default for ranges, `xrange` subtly pushed developers toward writing code that focused on transformations (e.g., `map(lambda x: x*2, xrange(1000))`) rather than mutable state.
- Thread Safety: Because `xrange` objects were immutable and stateless during iteration (only the counter was modified), they were inherently safe to use in multithreaded contexts without additional synchronization.

Comparative Analysis
While `xrange` was a game-changer in Python 2, its relationship with `range()` evolved significantly across versions. Below is a comparison of `xrange` (Python 2), `range()` (Python 2), and `range()` (Python 3):| Feature | Python 2: xrange() | Python 2: range() | Python 3: range() |
|---|---|---|---|
| Memory Usage | Lazy (generates values on demand) | Eager (stores all values in a list) | Lazy (behaves like xrange) |
| Return Type | xrange object (iterator) | list | range object (iterator) |
| Indexing Support | ❌ Not supported (raises TypeError) | ✅ Supported (e.g., range(10)[5] = 5) | ❌ Not supported (raises TypeError) |
| Use Case | Large iterations, memory efficiency | Small ranges, indexing needed | All iterations (default in Python 3) |
Future Trends and Innovations
The principles underlying `xrange`—lazy evaluation, iterator protocols, and memory efficiency—are more relevant than ever in modern Python. Today’s data science and machine learning workflows often involve datasets that dwarf available RAM, making lazy loading a necessity rather than an optimization. Libraries like Dask and Vaex build on these ideas, offering out-of-core computation that processes data in chunks rather than all at once. Similarly, Python’s `asyncio` framework relies on iterators and generators to handle I/O-bound tasks efficiently, echoing the same design philosophy that made `xrange` indispensable.Looking ahead, the trend toward lazy data structures is likely to accelerate. As Python continues to integrate with systems like Apache Arrow and Parquet (for columnar storage), the ability to iterate over data without full materialization will become a standard expectation. Even in traditional imperative code, patterns like `itertools`’s `count()` or `cycle()` functions—both of which emulate `xrange`-like behavior—are becoming more prevalent. The lesson of `xrange` isn’t that it was perfect, but that it forced Python to confront a fundamental question: How can we write code that scales without sacrificing clarity?

Conclusion
Python’s `xrange` was more than a temporary fix for memory constraints; it was a catalyst for a broader shift in how Python handles sequences. By embracing lazy evaluation, it set the stage for modern iteration patterns that now underpin everything from data pipelines to asynchronous programming. While its direct implementation is gone, its DNA lives on in `range()`, generators, and the iterator protocol itself. For developers working with legacy codebases or teaching iteration concepts, understanding `xrange` isn’t just about nostalgia—it’s about grasping the "why" behind Python’s design choices.The story of `xrange` also serves as a cautionary tale about language evolution. When Python 3 unified `range()` and `xrange`, it prioritized simplicity over historical fidelity, a decision that reflects the language’s commitment to pragmatism. Yet, the trade-offs—like the loss of explicit `xrange` for backward compatibility—highlight the challenges of balancing innovation with stability. As Python continues to evolve, the principles that made `xrange` successful will remain critical, ensuring that its legacy endures beyond its formal deprecation.
Comprehensive FAQs
Q: Why was `xrange` removed in Python 3?
The removal of `xrange` in Python 3 was part of a broader effort to simplify the language by unifying `range()` and `xrange()` into a single function. The new `range()` behaves like `xrange` (lazy evaluation) by default, eliminating redundancy while maintaining performance benefits. The change also reduced confusion for new developers, as the duality of `range()` and `xrange()` in Python 2 often led to subtle bugs when one was used instead of the other.
Q: Can I still use `xrange` in Python 3?
No, `xrange` is not available in Python 3. However, you can replicate its behavior using `range()` directly, as the two are functionally identical in Python 3. For example, `xrange(10)` in Python 2 is equivalent to `range(10)` in Python 3. If you’re maintaining Python 2 code, you can use the `six` library or `future` utilities to ensure compatibility across versions.
Q: What’s the memory difference between `xrange` and `range()` in Python 2?
In Python 2, `xrange(n)` uses constant memory (O(1)) because it generates values on demand, while `range(n)` uses linear memory (O(n)) because it stores all integers in a list. For `n = 1,000,000`, `xrange` would consume ~28 bytes (for the object overhead), whereas `range` would require ~8MB. This difference becomes critical for large `n` (e.g., `n > 10^6`), where `range` can crash programs due to memory exhaustion.
Q: Does `range()` in Python 3 support indexing like `range()` in Python 2?
No. Python 3’s `range()` does not support indexing (e.g., `range(10)[5]` raises `TypeError`), just like `xrange` in Python 2. This is intentional: the design prioritizes memory efficiency and iterator compatibility over indexing convenience. If you need indexed access, convert the `range` object to a list first (e.g., `list(range(10))[5]`).
Q: Are there modern alternatives to `xrange` for custom sequences?
Yes. For custom sequences, Python provides several tools:
- Generators: Use `yield` in a function to create lazy sequences (e.g., `def count_up_to(n): yield from range(n)`).
- Itertools: Functions like `itertools.count()`, `itertools.cycle()`, and `itertools.islice()` offer advanced lazy sequence generation.
- NumPy’s `arange`: For numerical ranges, `np.arange()` provides `xrange`-like behavior with additional features like floating-point steps.
- Custom Iterators: Implement `__iter__()` and `__next__()` in a class to create reusable lazy sequences.
Q: How does `xrange` compare to NumPy’s `arange`?
While both `xrange` and NumPy’s `arange` generate sequences lazily, they serve different purposes:
- `xrange` is a lightweight, built-in Python object for integer sequences with fixed step sizes.
- `arange` is part of NumPy and supports floating-point numbers, non-uniform steps, and additional mathematical operations (e.g., `np.arange(0, 1, 0.1)`).
- `arange` returns a NumPy array-like object (though not fully materialized), which integrates with NumPy’s ecosystem for vectorized operations.
Q: Can `xrange` be used in parallel or multithreaded code?
Yes, `xrange` objects are thread-safe because they are immutable and their state (the current counter) is modified only during iteration. However, if the same `xrange` object is shared across threads and iterated simultaneously, race conditions may occur. To avoid this, either:
- Create a new `xrange` object per thread.
- Use thread-safe synchronization (e.g., `threading.Lock`) if iterating over the same object.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.