How Python Lists Shape Modern Data Handling

Python lists are the unsung backbone of efficient data manipulation, serving as the default container for ordered, mutable collections. Their flexibility—supporting heterogeneous elements, dynamic resizing, and built-in methods—makes them indispensable in everything from scripting to large-scale systems. Yet beneath their simplicity lies a sophisticated implementation that balances performance with usability, a tradeoff that has cemented their dominance in Python’s ecosystem.
The distinction between Python lists and other sequence types (like tuples) isn’t just semantic; it’s foundational. Lists allow modifications in-place, enabling operations like appending, slicing, or sorting without creating new objects—a critical feature for memory efficiency. This mutability, however, introduces tradeoffs in thread safety and performance compared to immutable alternatives, forcing developers to weigh convenience against constraints.
While lists are often introduced as basic tools, their role extends far beyond simple storage. They underpin algorithms (e.g., dynamic programming), facilitate data pipelines, and even serve as the foundation for higher-level abstractions like NumPy arrays or Pandas DataFrames. Understanding their mechanics—from memory allocation to method optimization—reveals why they remain Python’s most versatile data structure.
The Complete Overview of Python Lists
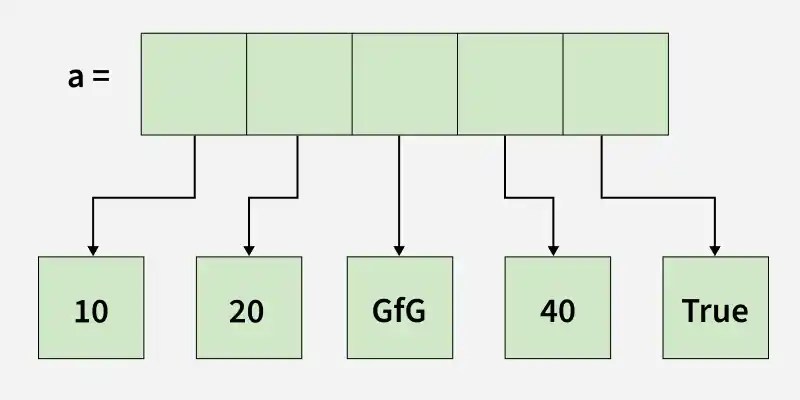
Python lists are dynamic arrays that combine the intuitiveness of native language constructs with the power of optimized C-level operations. Their design prioritizes readability and adaptability, allowing developers to perform complex manipulations with minimal syntactic overhead. For instance, a single line like `my_list.extend([1, 2, 3])` can merge multiple elements, whereas equivalent operations in lower-level languages might require explicit loops or memory management.Under the hood, Python lists are implemented as arrays of pointers to objects, not the objects themselves. This indirection enables flexibility—lists can hold any mix of data types (strings, integers, even other lists)—but it also introduces overhead when accessing elements, as each pointer must be dereferenced. The tradeoff between this flexibility and performance is a defining characteristic of Python’s philosophy: prioritize developer experience over raw speed.
Historical Background and Evolution
The concept of lists in Python traces back to the language’s early days, influenced by ABC’s sequence types and Lisp’s dynamic arrays. Guido van Rossum’s original implementation in 1991 focused on simplicity, embedding lists as the primary mutable sequence type. Early Python versions (pre-2.0) used a simple array structure with quadratic-time resizing, which became a bottleneck for large datasets.The transition to Python 2.0 in 2000 introduced significant optimizations, including over-allocation during resizing (amortizing costs to O(1) per append) and type specialization for homogeneous lists. Later, Python 3.x further refined memory management, reducing fragmentation and improving cache locality. These evolutions reflect a broader trend: Python lists have grown from a basic tool to a finely tuned structure capable of handling modern workloads, from machine learning datasets to real-time analytics.
Core Mechanisms: How It Works
At their core, Python lists are implemented as variable-length arrays stored in contiguous memory blocks. When a list exceeds its capacity, Python allocates a new block (typically 1.125x larger) and copies existing elements—a process called amortized O(1) append. This strategy minimizes frequent reallocations, though it can lead to temporary memory spikes.Table of Contents
- The Complete Overview of Python Lists
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Are Python lists thread-safe?
- Q: How do I remove duplicates from a list while preserving order?
- Q: Why is `list.append()` O(1) amortized but not strictly O(1)?
- Q: Can I use lists for high-frequency trading or real-time systems?
- Q: How do I efficiently concatenate many small lists?
- Q: Are there performance differences between `list.append(x)` and `list += [x]`?
- Q: How do I check if a list contains another list as a sublist?
- Q: Why does `del list[0]` take longer than `list.pop(0)`?
- Q: Can I use lists as keys in dictionaries?
- Q: How do I reverse a list in-place without extra memory?
- Q: What’s the most memory-efficient way to store large lists of integers?
Methods like `append()`, `pop()`, or `insert()` trigger these low-level operations, while slicing (`list[1:3]`) creates shallow copies of references. The distinction between shallow and deep copies is critical: modifying a nested object in a slice affects the original list unless explicitly cloned. This behavior stems from Python’s object model, where lists store references rather than duplicating data.
Key Benefits and Crucial Impact
Python lists dominate data handling because they solve problems other structures can’t. Their mutability enables in-place transformations, reducing memory overhead for iterative processes. For example, sorting a list in-place with `list.sort()` avoids creating a duplicate, unlike immutable tuples. This efficiency is particularly valuable in algorithms where intermediate states must be retained.The ecosystem’s reliance on lists extends beyond Python itself. Libraries like NumPy build upon list-like operations, while frameworks such as Django and Flask use lists to manage dynamic data (e.g., query results, request parameters). Even in performance-critical domains, lists serve as prototypes before optimization into specialized arrays.
"Python lists are the Swiss Army knife of data structures—not because they’re the fastest, but because they’re the most adaptable. Their simplicity masks a depth that few other tools can match."
— Guido van Rossum (Python’s Creator)
Major Advantages
- Dynamic Resizing: Automatically expands/contracts, eliminating manual memory management.
- Heterogeneous Support: Can mix data types (e.g., `[1, "text", [2, 3]]`), unlike statically typed arrays.
- Rich Method Suite: Built-in functions (`append`, `remove`, `reverse`) reduce boilerplate code.
- Interoperability: Seamlessly integrates with generators, comprehensions, and other iterables.
- Readability: Syntax like `list1 + list2` is intuitive compared to low-level alternatives.

Comparative Analysis
| Feature | Python Lists vs. Alternatives |
|---|---|
| Mutability | Mutable (in-place changes) vs. Tuples (immutable) or NumPy Arrays (fixed-type). |
| Performance | Slower than C arrays but faster than linked lists for random access. |
| Memory Usage | Higher overhead per element due to object references vs. packed arrays. |
| Use Case | General-purpose vs. specialized (e.g., tuples for constants, arrays for math). |
Future Trends and Innovations
As Python evolves, lists may see optimizations for parallel processing, leveraging multithreading to handle resizing without GIL contention. Projects like PyPy’s JIT compilation could further reduce overhead, making lists competitive with C++ vectors in niche scenarios. Additionally, the rise of typed lists (via `typing.List`) may bridge the gap between dynamic flexibility and static analysis tools.Long-term, Python lists might integrate more tightly with hardware acceleration, offloading operations to GPUs or TPUs for large-scale data. While immutable alternatives (like Rust’s `Vec`) gain traction, Python’s lists will likely retain their dominance in scripting and prototyping, where adaptability outweighs raw performance.
Conclusion
Python lists are more than a feature—they’re a cornerstone of the language’s philosophy. Their balance of simplicity and power enables developers to focus on logic rather than implementation details. While newer tools (e.g., arrays, dictionaries) address specific needs, lists remain the default choice for ordered, mutable data.The key to mastering Python lists lies in understanding their tradeoffs: when to use them for flexibility versus when to optimize with alternatives. As Python continues to evolve, lists will adapt, ensuring their relevance in both educational and production environments.
Comprehensive FAQs
Q: Are Python lists thread-safe?
A: No. Lists are not thread-safe by default; concurrent modifications (e.g., `append()` in multiple threads) can corrupt data. Use locks (`threading.Lock`) or thread-safe alternatives like `queue.Queue` for shared access.
Q: How do I remove duplicates from a list while preserving order?
A: Use a dictionary (Python 3.7+) or `collections.OrderedDict`:
```python
unique_list = list(dict.fromkeys(original_list))
```
This leverages hashability and insertion order to deduplicate efficiently.
Q: Why is `list.append()` O(1) amortized but not strictly O(1)?
A: While most appends are O(1), occasional resizing (when capacity is exceeded) triggers O(n) copying. The "amortized" guarantee means the average cost per operation remains constant over many appends.
Q: Can I use lists for high-frequency trading or real-time systems?
A: Generally no. Lists’ dynamic resizing and GIL contention make them unsuitable for ultra-low-latency applications. Instead, use fixed-size arrays (e.g., `array.array`) or C extensions like `numpy.ndarray` for performance-critical code.
Q: How do I efficiently concatenate many small lists?
A: Avoid repeated `list1 + list2` (O(n²) time). Instead, use:
```python
from itertools import chain
result = list(chain(*list_of_lists))
```
Or pre-allocate a large list and extend it in bulk.
Q: Are there performance differences between `list.append(x)` and `list += [x]`?
A: No. Both are equivalent in behavior and performance, as `+=` delegates to `extend()` for single-element cases. The choice is purely stylistic.
Q: How do I check if a list contains another list as a sublist?
A: Use `any(sublist in lst[i:i+len(sublist)] for i in range(len(lst)-len(sublist)+1))` for naive checks. For large lists, consider optimized libraries like `more_itertools` or `numpy.where`.
Q: Why does `del list[0]` take longer than `list.pop(0)`?
A: `del` shifts all remaining elements left (O(n)), while `pop(0)` uses a deque-like optimization in CPython (O(1) for small lists). For frequent removals, `collections.deque` is superior.
Q: Can I use lists as keys in dictionaries?
A: No. Lists are mutable and unhashable, so they cannot be dictionary keys. Use tuples (immutable) or frozen sets instead.
Q: How do I reverse a list in-place without extra memory?
A: Use `list.reverse()` (O(n) time, O(1) space). Alternatives like slicing (`list[::-1]`) create a new list.
Q: What’s the most memory-efficient way to store large lists of integers?
A: Use `array.array('i')` (for signed integers) or `numpy.array` (for numerical operations). Both reduce memory overhead compared to Python lists.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.