Python Null: The Hidden Power of Absence in Data Handling
Python’s treatment of null values is far more nuanced than a simple "empty placeholder." At its core, the concept of python null—whether as `None`, `NaN`, or missing data—serves as both a foundational building block and a frequent source of frustration. Developers often underestimate its implications: a misplaced `None` can silently corrupt a data pipeline, while an unchecked `NaN` might derail a machine learning model. The language’s design choices here reflect deeper philosophical trade-offs between strictness and flexibility, between explicitness and convenience.
Yet, the ambiguity doesn’t end with syntax. Python’s dynamic typing means null values behave differently across contexts: in lists, they’re just another object; in numerical operations, they trigger exceptions unless handled; in pandas DataFrames, they’re a first-class citizen with dedicated methods. This duality forces developers to confront a critical question: Is null a bug, a feature, or an unavoidable artifact of real-world data? The answer lies in understanding how Python’s null mechanisms interact with type systems, memory management, and even concurrency—topics rarely discussed in introductory tutorials.
The stakes are higher than ever. As Python dominates data science, web frameworks, and scripting, the way null values are managed directly impacts performance, security, and maintainability. A single overlooked `None` in a REST API response can cascade into a production outage. Meanwhile, libraries like NumPy and pandas have redefined null handling with `NaN` and `None`-aware operations, creating a fragmented ecosystem where best practices vary by domain. To navigate this landscape, one must grasp not just the syntax, but the semantics—why Python chose `None` over `null`, how `NaN` differs from `None`, and when to use `Optional` types to enforce null safety.
The Complete Overview of Python Null
Python’s approach to null values is a study in pragmatism. Unlike languages with a single `null` concept (e.g., JavaScript’s `null`/`undefined`), Python offers three primary representations: `None`, `NaN` (from `math.nan` or `numpy.nan`), and missing data in containers (e.g., empty lists or dictionaries). This multiplicity stems from Python’s design philosophy—balancing simplicity for general-purpose use with specialized tooling for domains like numerical computing. The result is a system where null values are both a liability (silent errors) and an asset (explicit state representation).The ambiguity extends to type checking. Python’s `None` is a singleton object of type `NoneType`, distinct from `False`, `0`, or empty strings—yet its behavior in comparisons (`None == False` raises `TypeError`) and boolean contexts (`if None:` evaluates to `False`) can trip up developers. Meanwhile, `NaN` (Not a Number) is a floating-point value that violates standard arithmetic rules: it’s never equal to itself (`NaN == NaN` is `False`), forcing developers to use `math.isnan()` for checks. This duality reflects Python’s role as a glue language—equally at home in scripting, where `None` dominates, and scientific computing, where `NaN` reigns.
Historical Background and Evolution
The roots of python null trace back to Guido van Rossum’s early design choices. In Python 1.0 (1991), `None` was introduced as a placeholder for "no value" or "not applicable," borrowing from Lisp’s `nil`. Its simplicity—just one object in memory—made it ideal for a language prioritizing readability. However, as Python evolved, so did its use cases. The rise of numerical computing in the 2000s demanded a null value that could integrate with IEEE 754 floating-point standards, leading to `NaN`’s prominence in libraries like NumPy (2006).The distinction between `None` and `NaN` became critical with the adoption of static typing tools like `mypy`. While `None` is a type-safe way to represent absence, `NaN` is inherently untyped—a floating-point value that can propagate undetected through calculations. This dichotomy highlights Python’s tension between dynamic flexibility and type safety. Even today, debates rage over whether `None` should be a subtype of all types (as in Rust’s `Option`) or remain distinct, with proponents of each side citing trade-offs in expressiveness versus safety.
Core Mechanisms: How It Works
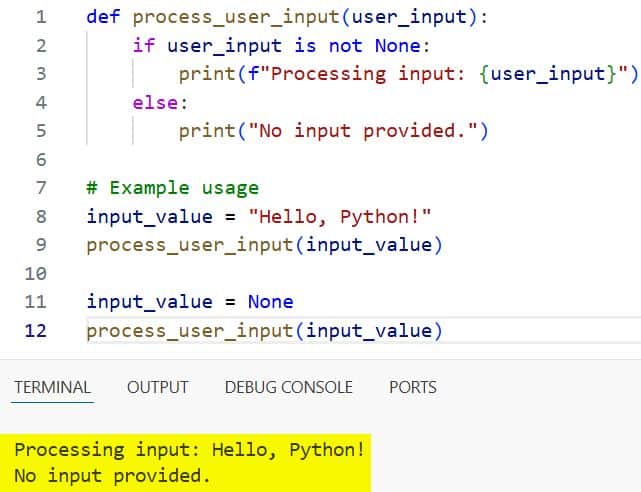
Under the hood, Python’s null values operate at multiple layers. `None` is a singleton instance of `NoneType`, stored in the interpreter’s memory once. Its behavior is defined by the language spec: it’s falsy in boolean contexts, hashable (unlike `NaN`), and can be checked with `is` or `is not` (e.g., `x is None`). This design ensures consistency but requires explicit handling—unlike JavaScript’s coercive `==` operator, Python’s `==` raises `TypeError` when comparing `None` to non-`NoneType` values.Table of Contents
- The Complete Overview of Python Null
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How do I check if a variable is `None` in Python?
- Q: Why does `NaN != NaN` evaluate to `True` in Python?
- Q: Can I use `None` as a default argument in a function?
- Q: How does pandas handle `None` vs. `NaN`?
- Q: What’s the difference between `Optional[T]` and `Union[T, None]`?
- Q: Why does `[] is None` raise `TypeError`?
- Q: How can I enforce null safety in Python?
- Q: What’s the best way to initialize a list with `None` values?
- Q: Can `NaN` be serialized with `json.dumps()`?
- Q: How does Python’s `None` compare to Rust’s `Option`?
`NaN`, by contrast, is a floating-point quirk. Represented as `0x7ff8000000000001` in IEEE 754 double-precision format, it propagates through arithmetic operations unless explicitly checked. Libraries like NumPy extend this with `numpy.nan`, which behaves identically but integrates with array operations. The key difference lies in their use cases: `None` signals intentional absence (e.g., missing API responses), while `NaN` indicates computational errors (e.g., division by zero). This semantic gap forces developers to choose tools deliberately—pandas, for instance, uses `None` for object dtypes and `NaN` for numerical dtypes, creating a hybrid system.
Key Benefits and Crucial Impact
Python’s null handling is both a strength and a vulnerability. On one hand, its explicitness reduces accidental bugs: unlike JavaScript’s `null`/`undefined` ambiguity, Python’s `None` is unambiguous. On the other, this explicitness demands discipline—developers must anticipate null values in function signatures, data pipelines, and error handling. The impact is particularly stark in data-heavy fields, where null values can skew analyses or halt algorithms. For example, a `NaN` in a pandas DataFrame column will propagate through aggregations unless masked with `.dropna()` or `.fillna()`.The trade-off is evident in Python’s ecosystem. Frameworks like FastAPI use `None` to denote optional fields, while TensorFlow relies on `NaN` to flag training errors. This fragmentation means developers must master context-specific null semantics. Yet, the benefits—flexibility in scripting, robustness in numerical work—outweigh the costs for those who treat null values as first-class design considerations.
"Null values are the silent assassins of software quality. They lurk in the corners of your code, waiting to turn a seemingly stable system into a house of cards." — David Beazley, Python Core Developer
Major Advantages
- Explicit State Representation: `None` forces developers to handle absence explicitly, reducing subtle bugs compared to languages where nulls are implicit (e.g., Java’s `null` in collections).
- Memory Efficiency: `None` is a singleton, requiring no additional memory allocation per instance, unlike boxed `null` objects in other languages.
- Domain-Specific Nulls: `NaN` integrates seamlessly with numerical computing, while `None` works in object-oriented contexts, allowing tailored null handling.
- Tooling Support: Libraries like pandas and NumPy provide null-aware methods (e.g., `.isna()`, `.fillna()`), reducing boilerplate for data cleaning.
- Type Safety (with Annotations): Python 3.5+ supports `Optional[T]` and `Union[T, None]`, enabling static type checkers to catch null-related errors early.
Comparative Analysis
| Aspect | Python (None/NaN) | JavaScript (null/undefined) | Java (null) |
|---|---|---|---|
| Representation | `None` (singleton), `NaN` (floating-point) | `null` (object reference), `undefined` (uninitialized) | `null` (explicit absence), `NullPointerException` (runtime error) |
| Type System | Dynamic (but type-annotatable with `Optional`) | Dynamic (coercive `==`) | Static (checked at compile time) |
| Memory Handling | Singleton `None`; `NaN` is a float value | Both are objects (boxed) | Reference type (no memory for `null` itself) |
| Common Pitfalls | Silent `NaN` propagation, `None` in boolean contexts | Accidental `==` comparisons, `undefined` vs. `null` confusion | `NullPointerException` in production |
Future Trends and Innovations
The evolution of python null will likely focus on three fronts: stricter type systems, better tooling, and domain-specific null handling. Python’s gradual adoption of type hints (via `typing` and `PEP 646`) suggests `None` will play a larger role in static analysis, with tools like `mypy` catching null-related errors earlier. Meanwhile, libraries may standardize null representations—imagine a future where `NaN` and `None` converge under a unified `Missing` type for mixed data.In data science, null handling will become more automated. AutoML tools might auto-detect and impute nulls, while frameworks like PyTorch could integrate null-aware tensors. For web development, FastAPI and similar tools may enforce null safety by default, reducing the "null reference" anti-pattern. The key trend? Null values will shift from a debugging nuisance to a first-class feature—explicitly designed into APIs, data structures, and algorithms.

Conclusion
Python’s null values are a microcosm of its design philosophy: pragmatic, flexible, and occasionally frustrating. Whether grappling with `None` in a REST API or `NaN` in a machine learning pipeline, developers must treat nulls as intentional design choices, not afterthoughts. The language’s strength lies in its adaptability—`None` for object absence, `NaN` for numerical errors—but this flexibility demands vigilance. As Python’s role in data and systems grows, so too will the importance of mastering null semantics.The lesson is clear: python null is not a bug to work around, but a feature to harness. By understanding its mechanics, historical context, and domain-specific quirks, developers can write code that’s not just functional, but resilient—ready to handle the inevitable absences in real-world data.
Comprehensive FAQs
Q: How do I check if a variable is `None` in Python?
Use the `is` operator for identity checks: `if x is None:`. Avoid `==` because it raises `TypeError` when comparing `None` to non-`NoneType` values. For `NaN`, use `math.isnan(x)` or `numpy.isnan(x)`.
Q: Why does `NaN != NaN` evaluate to `True` in Python?
This is a quirk of IEEE 754 floating-point standards. `NaN` represents an undefined mathematical result (e.g., `0/0`), so it’s designed to be unequal to itself. Always use `math.isnan()` or `numpy.isnan()` to check for `NaN`.
Q: Can I use `None` as a default argument in a function?
Yes, but be cautious. Default arguments are evaluated once at function definition time. If you use `None` as a default for a mutable object (e.g., `def foo(x=None): x = []`), all calls will share the same mutable default. Use `None` to indicate "no value provided," then initialize inside the function.
Q: How does pandas handle `None` vs. `NaN`?
Pandas uses `None` for object dtypes (e.g., strings) and `NaN` for numerical dtypes (e.g., `float64`). To check for nulls, use `.isna()` (catches both) or `.isnull()`. Imputation methods like `.fillna()` work uniformly across both types.
Q: What’s the difference between `Optional[T]` and `Union[T, None]`?
Both are type hints meaning "T or `None`." `Optional[T]` is syntactic sugar for `Union[T, None]` (introduced in Python 3.10). Use `Optional` for readability; `Union` is more explicit when mixing multiple types (e.g., `Union[int, str, None]`).
Q: Why does `[] is None` raise `TypeError`?
Because `None` is a singleton of type `NoneType`, while `[]` is a list (type `list`). Python’s `is` checks identity, not type equality. To compare types, use `isinstance(x, type(None))` or `type(x) is type(None)`.
Q: How can I enforce null safety in Python?
Use type hints (`Optional[T]`), static analyzers (`mypy`), and runtime checks (e.g., `assert x is not None`). Libraries like `pydantic` enforce null safety in data models by raising exceptions for missing required fields.
Q: What’s the best way to initialize a list with `None` values?
Use `[None] n` for immutable objects (like `None`), but avoid it for mutable objects (e.g., `[[]] 3` creates 3 references to the same list). For mutable defaults, use a loop: `[None for _ in range(n)]`.
Q: Can `NaN` be serialized with `json.dumps()`?
No. `NaN` is a float value, and `json.dumps()` only serializes JSON-compatible types (e.g., `None` becomes `null`). Convert `NaN` to `None` first: `json.dumps([float('nan')], default=lambda x: None)`.
Q: How does Python’s `None` compare to Rust’s `Option`?
Rust’s `Option
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.