How Regression Testing Saves Software from Silent Collapse

Software updates are supposed to improve systems, yet history shows that even minor changes can trigger cascading failures. In 2018, a routine patch in Amazon’s S3 storage service caused a three-hour outage, costing millions. The culprit? A regression—an unintended side effect that slipped through testing. Such incidents highlight why regression testing isn’t just a QA checkbox but a critical safeguard against systemic collapse. It’s the difference between a seamless user experience and a public relations disaster.
The term itself is deceptively simple. At its core, regression testing refers to systematically revalidating software after modifications—whether new features, bug fixes, or infrastructure updates—to confirm that existing functionality remains intact. Yet its execution varies wildly: from manual retesting of critical paths to AI-driven predictive analysis. The stakes are clear: neglect it, and you risk exposing vulnerabilities; over-engineer it, and you slow down development. Striking the balance requires understanding its evolution, mechanics, and strategic advantages.
Modern development cycles demand speed, but speed without rigor is a recipe for technical debt. Regression testing bridges this gap by automating validation where possible while preserving human oversight for edge cases. It’s not just about catching bugs—it’s about maintaining trust in a product’s reliability, especially as systems grow in complexity. Below, we dissect its origins, inner workings, and why it remains indispensable in an era of continuous deployment.
The Complete Overview of Regression Testing
Regression testing is the unsung hero of software stability, operating silently in the background while developers focus on innovation. Its primary goal is to detect regressions—defects introduced during changes—before they reach production. Unlike initial validation, which tests new features, regression testing verifies that nothing has been broken in the process. This distinction is critical: while unit tests validate individual components, regression tests ensure the entire system behaves as expected after alterations.The scope of regression testing extends beyond functional requirements. It encompasses performance metrics, security patches, and even user interface consistency. For instance, a performance regression might not manifest as a crash but as a 20% slowdown in API response times—equally damaging to user experience. Tools like Selenium, JUnit, and Appium automate these checks, but their effectiveness hinges on a well-defined test suite. Without it, regression testing becomes a gamble, relying on luck rather than methodology.
Historical Background and Evolution
The concept of regression testing emerged in the 1970s alongside structured programming, as developers sought ways to manage the growing complexity of software systems. Early approaches were ad-hoc, relying on manual retesting of affected modules—a labor-intensive process prone to human error. The 1990s brought a turning point with the rise of automated regression testing, enabled by frameworks like Rational Robot (later IBM Rational Functional Tester) and Mercury Interactive’s WinRunner. These tools allowed QA teams to script repetitive test cases, reducing cycle times and improving coverage.Today, regression testing is deeply integrated into CI/CD pipelines, where every commit triggers automated validation. Cloud-based platforms like Sauce Labs and BrowserStack further democratize testing by providing parallel execution across global infrastructures. The evolution reflects a broader shift: from reactive bug fixing to proactive risk mitigation. Yet, despite advancements, many organizations still treat regression testing as an afterthought, prioritizing speed over thoroughness—a mistake that becomes apparent only when failures occur.
Core Mechanisms: How It Works
At its core, regression testing operates on three pillars: test selection, execution, and analysis. Test selection determines which existing tests to rerun, typically focusing on areas impacted by changes. For example, modifying a payment gateway’s authentication logic would trigger retests of all related workflows. Execution can be manual, automated, or hybrid, with automation dominating in Agile environments due to its scalability. Analysis involves comparing current results against baselines to identify deviations, whether functional (e.g., a button no longer submits data) or non-functional (e.g., increased latency).Table of Contents
- The Complete Overview of Regression Testing
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: What’s the difference between regression testing and retesting?
- Q: Can regression testing be fully automated?
- Q: How often should regression testing be performed?
- Q: What are common pitfalls in regression testing?
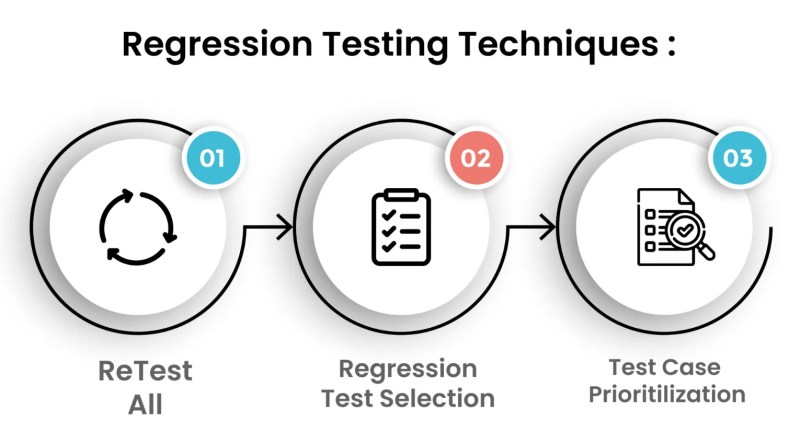
- Q: How do I prioritize regression test cases?
- Q: Is regression testing only for software?
The effectiveness of regression testing depends on the test suite’s granularity. A granular suite catches subtle regressions, such as a single pixel shift in a dashboard, while a high-level suite might miss them. Tools like Postman for APIs or Cypress for frontend applications enable fine-grained control, but maintaining such suites requires discipline. Without it, regression testing degenerates into a superficial check—leaving critical gaps in coverage.
Key Benefits and Crucial Impact
The value of regression testing lies in its ability to prevent silent failures—defects that evade initial testing but surface in production. These failures often escalate into costly downtime, as seen when a 2012 Knight Capital trading algorithm bug led to $460 million in losses within 45 minutes. Regression testing mitigates such risks by validating changes incrementally, ensuring that each update aligns with the system’s intended behavior. It’s not just about catching bugs; it’s about preserving the software’s integrity over time.Beyond risk reduction, regression testing accelerates development by reducing the time spent on post-release firefighting. Automated regression suites run in minutes, freeing QA teams to focus on exploratory testing and innovation. This efficiency is particularly critical in industries like healthcare or finance, where compliance and reliability are non-negotiable. As systems scale, the cost of undetected regressions grows exponentially—making regression testing a strategic investment rather than a cost center.
“Regression testing is the canary in the coal mine of software development. It doesn’t prevent all failures, but it gives you the earliest warning possible.”
— James Bach, Software Testing Pioneer
Major Advantages
- Defect Prevention: Catches regressions early, before they affect end-users, reducing mean time to resolution (MTTR).
- Cost Efficiency: Automated regression suites cut manual testing efforts by 70–80%, lowering long-term QA costs.
- Compliance Assurance: Ensures adherence to industry standards (e.g., HIPAA, PCI-DSS) by validating security patches and updates.
- Performance Stability: Monitors metrics like response times and memory usage, preventing performance regressions.
- User Trust: Maintains consistency in functionality, reducing customer churn due to unexpected bugs.
Comparative Analysis
Regression testing often overlaps with other QA practices, but its focus differs. Below is a comparison of key testing types:| Regression Testing | Other Testing Types |
|---|---|
| Validates existing functionality after changes. | Unit Testing: Tests individual components in isolation. |
| Primarily automated; runs frequently in CI/CD. | Integration Testing: Verifies interactions between modules (e.g., API + database). |
| Detects regressions introduced by new code. | System Testing: Evaluates the complete system against requirements. |
| Requires a maintained test suite; coverage depends on scope. | Exploratory Testing: Unscripted testing to find edge cases (complements regression). |
Future Trends and Innovations
The future of regression testing lies in AI and predictive analytics, where machine learning models analyze code changes to prioritize high-risk test cases. Tools like Diffblue and Testim use AI to generate test cases dynamically, reducing the manual effort required to maintain suites. Another trend is shift-left testing, where regression checks are integrated earlier in the development cycle, catching issues before they propagate. Cloud-native testing platforms are also evolving, offering serverless regression suites that scale with demand.However, challenges remain. As systems grow more complex—with microservices, edge computing, and IoT integrations—traditional regression testing struggles to keep pace. The solution may lie in hybrid approaches, combining automated regression with human-led exploratory testing to cover unscripted scenarios. The goal is clear: make regression testing smarter, faster, and more adaptive to the pace of modern development.
Conclusion
Regression testing is not a luxury but a necessity in software development. Its ability to prevent regressions—whether functional, performance-related, or security-critical—directly impacts a product’s success. While automation has significantly reduced the overhead, the discipline of maintaining a robust test suite remains critical. Organizations that treat regression testing as an afterthought risk exposing their users to avoidable failures, while those that embed it into their culture gain a competitive edge in reliability and trust.The evolution of regression testing reflects broader trends in software engineering: the shift from reactive to proactive, from manual to automated, and from siloed to integrated. As development cycles accelerate, the role of regression testing will only grow in importance. The question is no longer whether to implement it, but how to do so effectively—balancing speed, coverage, and precision in an era where software failures are no longer tolerable.
Comprehensive FAQs
Q: What’s the difference between regression testing and retesting?
A: Retesting focuses on re-running failed test cases after fixes, while regression testing validates all affected functionality to ensure no new defects were introduced. Retesting is a subset of regression testing, typically performed after bug fixes.
Q: Can regression testing be fully automated?
A: While many regression test cases can be automated (e.g., API validations, UI workflows), some scenarios—like exploratory testing of edge cases—require human judgment. A hybrid approach is ideal for comprehensive coverage.
Q: How often should regression testing be performed?
A: In Agile environments, regression testing runs with every sprint or build. In Waterfall, it occurs after major milestones (e.g., after integration phases). The frequency depends on the project’s risk tolerance and change velocity.
Q: What are common pitfalls in regression testing?
A:
- Incomplete test suites (missing critical paths).
- Over-reliance on automation without human oversight.
- Neglecting non-functional aspects (e.g., performance, security).
- Failing to update test cases when requirements change.
Q: How do I prioritize regression test cases?
A: Prioritize based on:
- Impact: High-risk modules (e.g., payment processing).
- Frequency: Often-used features.
- Change Scope: Areas directly modified.
- Business Criticality: Functions tied to revenue or compliance.
Q: Is regression testing only for software?
A: While most common in software, regression testing applies to any system where changes could introduce unintended side effects—such as embedded systems, firmware, or even mechanical designs (e.g., validating a revised car part doesn’t affect safety systems).
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.