The Hidden Power of SQL INSERT: How It Shapes Modern Data Architecture

The first time a developer executes an `sql insert` command, they’re not just adding a row—they’re participating in a decades-old ritual of database engineering. This operation, deceptively simple in its syntax, serves as the backbone of data persistence across industries, from financial transaction logs to real-time analytics pipelines. Behind every `INSERT INTO` statement lies a carefully orchestrated sequence of memory allocation, index updates, and transaction validation, all executed in milliseconds. Yet, despite its ubiquity, the nuances of `sql insert`—how it interacts with triggers, locks, or batch processing—remain underappreciated by even seasoned engineers.
What separates a well-optimized `sql insert` from one that triggers cascading latency? The answer lies in understanding the hidden layers: the role of buffer pools in reducing disk I/O, the trade-offs between bulk inserts and row-by-row operations, or how modern databases like PostgreSQL and MySQL handle concurrent writes. These details aren’t just technical trivia—they directly impact scalability, data consistency, and even security. For example, a poorly designed `sql insert` can inadvertently expose SQL injection vulnerabilities or create hotspots that throttle database performance during peak loads.
The evolution of `sql insert` mirrors the broader trajectory of database technology. Early relational systems treated inserts as atomic, isolated operations, while today’s distributed databases distribute them across shards or replicate them across regions—all while maintaining ACID compliance. This shift reflects a deeper truth: `sql insert` isn’t just a command; it’s a contract between application logic and data storage, one that must adapt as systems grow in complexity.
The Complete Overview of SQL INSERT Operations
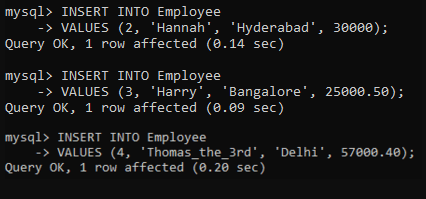
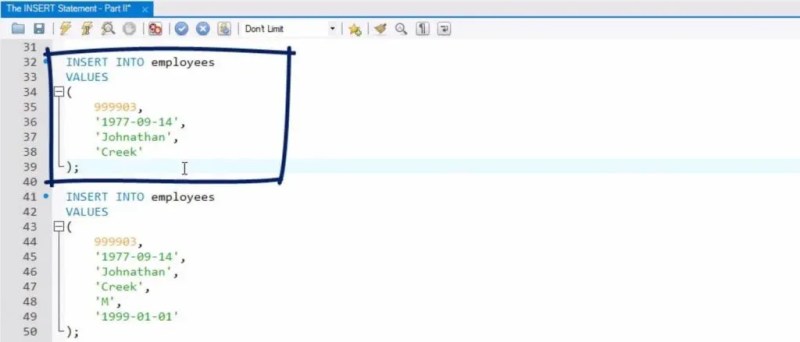
At its core, `sql insert` is the most fundamental operation in relational database management, responsible for populating tables with structured data. Unlike `UPDATE` or `DELETE`, which modify existing records, `sql insert` introduces new entries, triggering a cascade of internal processes: memory allocation for the new row, index maintenance, and—if transactions are involved—write-ahead logging to ensure durability. The simplicity of the syntax (`INSERT INTO table (columns) VALUES (values);`) belies the sophistication required to execute it efficiently, especially in high-throughput environments where millions of rows may be inserted daily.Modern databases optimize `sql insert` through techniques like batch processing, where multiple rows are grouped into a single operation to minimize network round trips, or deferred constraint checks, which delay validation until the transaction commits. These optimizations are critical for applications like e-commerce platforms, where every product view or purchase must be logged without delay. Yet, the choice of strategy depends on context: a single-row `sql insert` might be ideal for low-volume systems, while bulk operations are essential for data warehouses ingesting terabytes of log data nightly.
Historical Background and Evolution
The concept of `sql insert` emerged alongside the relational model in the 1970s, when Edgar F. Codd’s seminal papers laid the groundwork for Structured Query Language (SQL). Early implementations in systems like IBM’s System R treated inserts as straightforward append operations, with little consideration for performance at scale. As databases grew in size, the need for transactional integrity became apparent, leading to the introduction of `BEGIN TRANSACTION` and `COMMIT` statements in the 1980s. This evolution allowed `sql insert` operations to participate in atomic units of work, ensuring that partial failures wouldn’t corrupt data.The 1990s brought another paradigm shift with the rise of client-server architectures. Developers began using `sql insert` in application code, often through ORMs (Object-Relational Mappers) that abstracted the underlying SQL. However, this abstraction sometimes obscured performance pitfalls—such as the N+1 query problem—where inefficient `sql insert` calls generated excessive database round trips. The response was a renewed focus on raw SQL optimization, particularly in high-performance applications like real-time bidding systems or fraud detection engines, where every millisecond matters.
Core Mechanisms: How It Works
Under the hood, an `sql insert` operation follows a multi-stage pipeline. First, the database engine parses the statement to validate syntax and identify the target table and columns. Next, it allocates memory for the new row, often in a buffer pool to avoid immediate disk writes. If the table has indexes, the engine updates them concurrently, though this can introduce lock contention in high-concurrency scenarios. Finally, the row is written to disk, with the transaction log ensuring recovery in case of a crash.Table of Contents
- The Complete Overview of SQL INSERT Operations
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: What’s the difference between `INSERT` and `INSERT ... SELECT`?
- Q: How do I handle duplicates during an `sql insert`?
- Q: Can `sql insert` operations be rolled back?
- Q: What’s the impact of indexes on `sql insert` performance?
- Q: How do I log all `sql insert` operations for auditing?
- Q: What’s the best way to insert millions of rows efficiently?
The efficiency of this pipeline varies by database system. For instance, MySQL’s InnoDB engine uses a technique called "insert buffer" to defer index updates until the table is read, reducing I/O overhead for secondary indexes. PostgreSQL, meanwhile, employs a "write-ahead log" (WAL) to batch inserts into larger transactions, improving throughput. These differences highlight why benchmarking `sql insert` performance across databases is essential for architecture decisions.
Key Benefits and Crucial Impact
The strategic use of `sql insert` operations underpins data-driven decision-making, enabling everything from personalized recommendations to regulatory compliance reporting. By ensuring data integrity through constraints (e.g., `NOT NULL`, `UNIQUE`), `sql insert` prevents anomalies that could skew analytics or violate business rules. For example, an e-commerce platform relying on `sql insert` to log inventory changes can instantly trigger alerts when stock levels hit thresholds, automating supply chain responses.Beyond functionality, `sql insert` plays a critical role in system resilience. Transactional inserts guarantee that data modifications persist even after application failures, while features like `ON CONFLICT` in PostgreSQL allow for upsert operations—inserting new records or updating existing ones in a single statement. This dual capability reduces the complexity of application logic, as developers no longer need to handle duplicate-key errors manually.
"An `sql insert` is not just a command; it’s the first step in a data lifecycle that spans storage, processing, and analysis. Mastering it means mastering the flow of information itself." — Martin Fowler, Database Refactoring
Major Advantages
- Data Integrity: Constraints like `FOREIGN KEY` and `CHECK` ensure inserted data adheres to schema rules, reducing errors in downstream processes.
- Performance Optimization: Batch inserts (e.g., `INSERT ... SELECT`) minimize network latency by reducing the number of round trips between application and database.
- Scalability: Techniques like bulk loading (`LOAD DATA INFILE`) enable high-speed ingestion of large datasets, critical for data warehousing.
- Concurrency Control: Transactional inserts with `ROW_LOCK` or `FOR UPDATE` prevent race conditions in multi-user environments.
- Auditability: Timestamps and triggers on `sql insert` operations create immutable logs for compliance and debugging.
Comparative Analysis
| Feature | MySQL (InnoDB) | PostgreSQL | SQL Server |
|---|---|---|---|
| Bulk Insert Performance | Optimized via `LOAD DATA INFILE`; uses insert buffer for secondary indexes. | Supports `COPY` command; WAL buffering improves throughput. | Uses `BCP` utility; table locking reduces contention. |
| Concurrent Writes | Row-level locking; MVCC (Multi-Version Concurrency Control) minimizes blocking. | MVCC with snapshot isolation; `ON CONFLICT` for upserts. | Optimistic concurrency with `SNAPSHOT` isolation. |
| Error Handling | Returns affected rows; requires manual handling of duplicates. | `ON CONFLICT DO UPDATE` handles duplicates natively. | `MERGE` statement for upsert logic. |
| Advanced Features | Generated columns, JSON support in modern versions. | CTEs, window functions, and `RETURNING` clause for inserted data. | Change Data Capture (CDC) for real-time inserts. |
Future Trends and Innovations
The next frontier for `sql insert` lies in distributed and polyglot persistence architectures. As applications migrate to microservices, databases must support cross-shard inserts while maintaining consistency. Projects like Google Spanner and CockroachDB are pioneering globally distributed `sql insert` operations with strong consistency guarantees, using techniques like Paxos consensus. Meanwhile, the rise of NewSQL systems—blending SQL’s declarative power with NoSQL’s scalability—will redefine how inserts are optimized for low-latency, high-throughput workloads.Another emerging trend is the integration of machine learning with `sql insert` operations. Databases like Snowflake and BigQuery now use AI to predict optimal insertion strategies, dynamically adjusting batch sizes or index maintenance based on workload patterns. As data volumes explode, these adaptive approaches will become indispensable, turning `sql insert` from a manual task into an autonomous, self-optimizing process.
Conclusion
The `sql insert` operation, though often overlooked in favor of flashier technologies, remains the linchpin of data systems. Its evolution reflects broader trends in database engineering: from centralized monoliths to distributed, event-driven architectures. The key to leveraging it effectively lies in balancing simplicity with sophistication—understanding when to use raw SQL versus ORMs, and how to tune inserts for specific workloads.As databases grow more intelligent, the line between `sql insert` and application logic will blur further. Developers who treat inserts as mere CRUD operations will fall behind those who view them as strategic levers—optimizing for both immediate performance and long-term scalability. The future of data architecture depends on it.
Comprehensive FAQs
Q: What’s the difference between `INSERT` and `INSERT ... SELECT`?
A: A standard `INSERT` adds rows defined in the `VALUES` clause, while `INSERT ... SELECT` populates a table by querying another table or view. The latter is powerful for data migration or derived inserts, but it can be slower if the subquery is complex or returns many rows.
Q: How do I handle duplicates during an `sql insert`?
A: Use `ON CONFLICT` in PostgreSQL or `INSERT IGNORE` in MySQL to skip duplicates. For SQL Server, `MERGE` or `OUTPUT` clauses can identify conflicts. Always test with `UNIQUE` constraints to avoid silent failures.
Q: Can `sql insert` operations be rolled back?
A: Yes, if wrapped in a transaction. Use `BEGIN TRANSACTION` before inserts, then `COMMIT` or `ROLLBACK` to control persistence. Uncommitted inserts are stored in memory and discarded on rollback.
Q: What’s the impact of indexes on `sql insert` performance?
A: Indexes slow down inserts because the database must update them. To mitigate this, use bulk inserts with deferred index maintenance (e.g., MySQL’s `ALTER TABLE ... DISABLE KEYS`) or consider clustered indexes for primary keys.
Q: How do I log all `sql insert` operations for auditing?
A: Use triggers with `AFTER INSERT` to log changes to an audit table. Alternatively, enable database-level logging (e.g., PostgreSQL’s `log_statement = 'all'`) or leverage tools like Debezium for CDC (Change Data Capture).
Q: What’s the best way to insert millions of rows efficiently?
A: Use bulk loading methods like `LOAD DATA INFILE` (MySQL), `COPY` (PostgreSQL), or `BCP` (SQL Server). For in-application inserts, batch rows into transactions (e.g., 1,000 rows per `COMMIT`) to reduce transaction overhead.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.