Decoding the p value formula: The Statistical Tool That Shapes Science

The p value formula is not merely a statistical abstraction; it is the linchpin of modern scientific inquiry, determining whether a discovery merits belief or dismissal. At its core, this mathematical construct quantifies the probability of observing data at least as extreme as what was recorded, assuming the null hypothesis is true. Researchers across disciplines—from medicine to economics—rely on it to distinguish meaningful patterns from random noise, yet its misuse remains rampant, often leading to inflated claims or overlooked truths. The formula itself, though deceptively simple, belies a complex interplay of probability theory, experimental design, and interpretive nuance.
Critics argue that the p value formula has been overhyped, reduced to a binary threshold (p < 0.05) that oversimplifies the richness of statistical evidence. Yet its enduring relevance lies in its ability to standardize rigor across fields, providing a common language for evaluating uncertainty. Misinterpretations, however, abound: researchers frequently conflate statistical significance with practical importance, or ignore effect sizes entirely. The formula’s true power emerges when paired with contextual understanding—where p values are one piece of a larger puzzle, not the sole arbiter of truth.
Understanding the p value formula requires dissecting its components: the test statistic, the sampling distribution, and the critical threshold. It is the intersection of observed data and theoretical expectations, a bridge between raw measurements and inferential conclusions. Whether applied in clinical trials, social sciences, or engineering, its role is to guard against false positives while balancing the risk of false negatives—a delicate equilibrium at the heart of scientific progress.
The Complete Overview of the p value formula
The p value formula serves as the bedrock of null hypothesis significance testing (NHST), a framework that has defined empirical research for over a century. Its primary function is to assess the strength of evidence against a default assumption (the null hypothesis), typically that no effect or relationship exists. The formula itself is derived from the cumulative distribution function (CDF) of the test statistic under the null distribution, yielding a probability that reflects how unlikely the observed data would be if the null were correct. This probability is not, however, the probability that the null is true or false—it is the likelihood of the data given the null, a critical distinction often lost in popular discourse.The p value formula’s versatility stems from its adaptability to different statistical tests (t-tests, chi-square, ANOVA, etc.), each with its own distribution assumptions. For instance, in a two-tailed t-test, the p value is calculated as:
\[ p = 2 \times \min(P(T \geq |t|), P(T \leq -|t|)) \]
where \( T \) follows a t-distribution with \( n-1 \) degrees of freedom. This formula encapsulates the symmetry of the test, accounting for deviations in either direction. Meanwhile, in non-parametric tests like the Wilcoxon signed-rank, the p value is derived from permutation distributions, highlighting how the formula’s implementation varies with the underlying data structure.
Historical Background and Evolution
The origins of the p value formula trace back to early 20th-century statistics, particularly the work of Ronald Fisher and Jerzy Neyman. Fisher, in his 1925 paper Statistical Methods for Research Workers, introduced the concept of "probability of error" as a means to evaluate experimental outcomes. His emphasis on p values as a measure of "surprise" under the null hypothesis laid the groundwork for their adoption in agricultural and biological sciences. Neyman and Pearson later formalized hypothesis testing into a decision-theoretic framework, distinguishing between Type I (false positive) and Type II (false negative) errors, which further cemented the p value’s role in statistical inference.The 1950s and 1960s saw the p value formula become a standard tool in medical research, particularly in clinical trials, where it provided a quantifiable basis for declaring treatment efficacy. However, its uncritical application led to controversies, most notably the "replication crisis" of the 21st century, where many high-profile studies failed to replicate due to overreliance on p < 0.05 as a gold standard. This crisis spurred reforms, including the push for Bayesian alternatives, effect size reporting, and pre-registration of studies—all of which underscore the p value formula’s limitations while acknowledging its foundational importance.
Core Mechanisms: How It Works
The p value formula operates by comparing the observed test statistic to a reference distribution (e.g., normal, t, chi-square) under the null hypothesis. For example, in a z-test for proportions, the formula computes:\[ z = \frac{\hat{p} - p_0}{\sqrt{\frac{p_0(1-p_0)}{n}}} \]
where \( \hat{p} \) is the sample proportion, \( p_0 \) the null proportion, and \( n \) the sample size. The p value is then the area under the standard normal curve beyond \( |z| \). This process assumes that, under the null, the test statistic follows a known distribution, allowing researchers to compute the probability of observing data as extreme as theirs.
Table of Contents
- The Complete Overview of the p value formula
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: What is the fundamental difference between a p value and a confidence interval?
- Q: Why do some researchers argue that p < 0.05 is an arbitrary cutoff?
- Q: Can a p value ever be "too small"?
- Q: How does sample size affect the p value formula?
- Q: Are there alternatives to the p value formula that are gaining traction?
- Q: How should p values be reported in research papers?
A common misconception is that the p value measures the probability that the null hypothesis is true. In reality, it quantifies the compatibility of the data with the null, not the null’s plausibility. This distinction is crucial: a p value of 0.04 does not mean there’s a 4% chance the null is correct; it means there’s a 4% chance of seeing such data (or more extreme) if the null were true. The formula’s output is inherently conditional, a point often obscured in non-technical explanations.
Key Benefits and Crucial Impact
The p value formula’s greatest strength lies in its ability to provide a standardized metric for evaluating evidence across disparate fields. In pharmaceutical trials, it determines whether a drug’s effects surpass placebo levels; in social sciences, it tests hypotheses about behavioral trends. Its universal applicability has democratized rigor, allowing researchers to communicate findings with precision. However, this very universality has led to its overuse, particularly in contexts where effect sizes or confidence intervals would offer richer insights.The formula’s impact extends beyond academia into policy and industry, where decisions often hinge on statistical thresholds. Regulatory bodies, for instance, may approve drugs based on p values, even as critics argue that such binary cutoffs ignore nuance. The tension between utility and misuse highlights the need for contextual interpretation—p values should inform, not dictate, conclusions.
"The p value is not the probability that the null hypothesis is true. It is the probability of observing data at least as extreme as what was recorded, assuming the null is true." — Cosma Shalizi, Statistician and Data Scientist
Major Advantages
- Objectivity: The p value formula provides a reproducible, mathematical basis for evaluating hypotheses, reducing subjective judgment in research.
- Standardization: Its widespread adoption allows cross-disciplinary comparison of results, fostering collaboration and meta-analyses.
- Decision Support: In fields like medicine and engineering, p values help prioritize interventions or designs by quantifying risk.
- Transparency: Reporting p values alongside effect sizes and confidence intervals enhances the transparency of scientific claims.
- Historical Continuity: As a long-standing tool, it bridges modern research with classical statistical traditions, ensuring methodological consistency.

Comparative Analysis
| Aspect | p value formula | Bayesian Methods |
|---|---|---|
| Primary Output | Probability of data under null (p value) | Posterior probability of hypotheses (credible intervals) |
| Interpretation | Conditional on null; does not quantify evidence for alternatives | Directly quantifies belief in hypotheses after observing data |
| Assumptions | Relies on null distribution; sensitive to sample size | Requires prior distributions; incorporates prior knowledge |
| Common Use Cases | Hypothesis testing in NHST; regulatory approvals | Complex models; when prior information is available |
Future Trends and Innovations
The p value formula’s future may lie in its integration with more sophisticated statistical frameworks. Machine learning’s rise has prompted calls for alternatives like false discovery rates (FDR) in high-dimensional data, where traditional p value thresholds become impractical. Simultaneously, Bayesian approaches are gaining traction, offering a more intuitive interpretation of evidence. However, the p value’s persistence suggests its adaptability—new methods may retain its core logic while addressing its limitations, such as through hierarchical models or p value adjustments for multiple testing.Innovations in computational statistics could also redefine how p values are calculated, particularly in non-parametric or semi-parametric contexts. As data volumes grow, so too will the need for scalable, interpretable methods that preserve the p value’s intuitive appeal while mitigating its pitfalls. The challenge will be balancing tradition with progress, ensuring that statistical rigor evolves without losing its foundational principles.
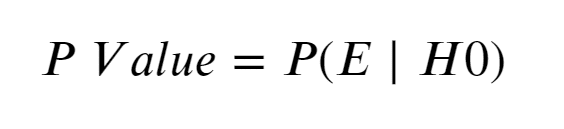
Conclusion
The p value formula remains indispensable in research, yet its limitations demand cautious application. It is a tool, not a truth—one that excels at identifying anomalies but struggles to quantify their importance. The replication crisis has underscored the need for complementary metrics, but abandoning p values entirely would discard a century of methodological refinement. Instead, researchers must embrace them as part of a broader toolkit, pairing them with effect sizes, Bayesian analyses, and replication studies to paint a fuller picture of evidence.Ultimately, the p value formula’s legacy is one of evolution. Its formulaic precision has shaped science, but its future lies in adaptation—refining how we interpret uncertainty in an era of big data and complex hypotheses. For now, it stands as a testament to the power of mathematical rigor in uncovering truth.
Comprehensive FAQs
Q: What is the fundamental difference between a p value and a confidence interval?
A: A p value assesses the compatibility of data with a null hypothesis, providing a single probability threshold (e.g., p < 0.05). A confidence interval, however, estimates the range within which a population parameter likely falls, offering a direct measure of uncertainty around an effect size. While p values are binary in interpretation, confidence intervals provide granularity, making them more informative for decision-making.
Q: Why do some researchers argue that p < 0.05 is an arbitrary cutoff?
A: The 0.05 threshold was popularized by Fisher as a convention, not a fundamental truth. Critics argue it creates a false sense of precision, as p values between 0.04 and 0.06 are treated equivalently despite differing degrees of evidence. Additionally, the cutoff inflates Type I error rates in multiple testing and fails to account for effect sizes or prior probabilities. Many now advocate for reporting exact p values or using Bayesian methods to avoid arbitrary dichotomies.
Q: Can a p value ever be "too small"?
A: Yes. Extremely small p values (e.g., p < 1e-10) may indicate overfitting, data dredging, or excessive sample sizes, leading to statistically significant but trivial effects. They can also signal issues like non-normality or heteroscedasticity if the test assumptions are violated. Context matters: a p value’s meaningfulness depends on the study design, sample size, and practical significance of the observed effect.
Q: How does sample size affect the p value formula?
A: Larger sample sizes increase statistical power, making even minor effects appear significant (low p values). This is because the test statistic’s variance decreases with \( n \), amplifying the numerator’s influence. Conversely, small samples may yield high p values due to high variance, even if the true effect is substantial. This sensitivity to \( n \) is why effect sizes and confidence intervals are critical—p values alone cannot distinguish between meaningful and trivial findings.
Q: Are there alternatives to the p value formula that are gaining traction?
A: Yes. Bayesian methods (e.g., Bayes factors) provide posterior probabilities for hypotheses, offering a more intuitive measure of evidence. Other alternatives include:
- Estimation-based approaches: Reporting effect sizes with confidence intervals.
- False Discovery Rate (FDR): Controlling for multiple comparisons in high-throughput data.
- Likelihood ratios: Comparing the support for null vs. alternative hypotheses.
- Prediction intervals: Estimating future data ranges rather than parameter estimates.
Q: How should p values be reported in research papers?
A: Best practices include:
- Reporting exact p values (not just "p < 0.05") to two or three decimal places.
- Including effect sizes (e.g., Cohen’s d, odds ratios) alongside p values.
- Providing confidence intervals for key parameters.
- Avoiding phrases like "statistically significant" without context; instead, describe the evidence strength.
- Disclosing pre-registration details or sensitivity analyses if applicable.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.