How Exponential Distribution Shapes Data, Risk, and Real-World Decisions

The exponential distribution isn’t just another mathematical abstraction—it’s the silent architect of systems where failure, decay, or randomness governs outcomes. From the lifespan of light bulbs to the timing of earthquakes, this probability model captures the essence of processes where events occur independently at a constant average rate. Its elegance lies in its simplicity: a single parameter defines an entire family of curves, yet it underpins some of the most critical decisions in finance, engineering, and public policy.
What makes the exponential distribution uniquely powerful is its ability to model memoryless phenomena—systems where the probability of an event occurring in the next interval depends only on the current state, not on history. This property, known as the lack of memory, turns it into a Swiss Army knife for predicting failures, optimizing queues, or even estimating how long a patient might wait for an organ transplant. Yet despite its ubiquity, many professionals misunderstand its nuances, mistaking it for its cousin, the normal distribution, or misapplying it in scenarios where it doesn’t belong.
The exponential distribution’s influence extends far beyond academic textbooks. In 2008, its failure to account for correlated risks in financial models contributed to the collapse of major institutions. Today, it remains the backbone of reliability engineering, queueing theory, and survival analysis—fields where the difference between a well-calibrated model and a flawed one can mean millions in losses or lives at stake. Understanding it isn’t just about mastering a formula; it’s about recognizing when and why the world behaves exponentially.
The Complete Overview of Exponential Distribution
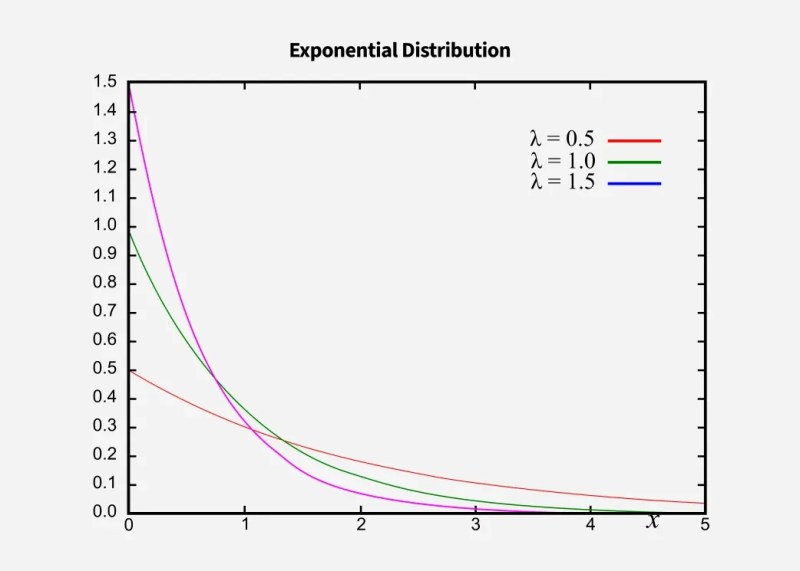
The exponential distribution is a continuous probability distribution that describes the time between events in a Poisson process—a scenario where events occur continuously and independently at a constant average rate. Its probability density function (PDF) is defined as f(x) = λe-λx, where λ (lambda) is the rate parameter, and x represents the variable of interest (often time). The cumulative distribution function (CDF) mirrors this simplicity: F(x) = 1 − e-λx. This minimalist structure belies its versatility, as it can model everything from the interarrival times of customers at a call center to the decay of radioactive particles.
What sets the exponential distribution apart is its memoryless property, a characteristic shared only by a handful of other distributions. This means that the probability of an event occurring in the next interval is independent of how much time has already passed. For example, if a machine has a 10% chance of failing in the next hour, that probability remains unchanged whether the machine is brand new or has been running for 50 hours. This property makes it indispensable in reliability engineering, where systems must operate without historical bias. However, this same trait can lead to misapplication—engineers often assume exponential decay where other processes (like Weibull distributions) better capture real-world aging effects.
Historical Background and Evolution
The exponential distribution’s roots trace back to the 18th century, when mathematicians like Daniel Bernoulli and Pierre-Simon Laplace laid the groundwork for probability theory. However, its formalization as a distinct distribution didn’t occur until the early 20th century, when statisticians like A.K. Erlang and Agnesi began studying telephone traffic patterns. Erlang’s work on queueing theory revealed that call arrival times followed an exponential pattern, a discovery that later became foundational for modern telecommunications and operations research. Meanwhile, in physics, the exponential distribution emerged as a model for radioactive decay, where the probability of decay per unit time is constant—a principle later generalized to other decay processes.
Table of Contents
- The Complete Overview of Exponential Distribution
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How do I determine if an exponential distribution is appropriate for my data?
- Q: Why does the exponential distribution have a long right tail, and what does this imply?
- Q: Can the exponential distribution model correlated events?
- Q: How is the exponential distribution related to the Poisson process?
- Q: What are common pitfalls when using the exponential distribution?
- Q: Are there alternatives to the exponential distribution for modeling decay processes?
By the mid-20th century, the exponential distribution had cemented its place in multiple disciplines. In 1951, W. Weibull introduced his namesake distribution as an alternative to exponential decay, acknowledging that real-world systems often exhibit increasing or decreasing failure rates over time. This refinement highlighted a critical limitation of the exponential model: its assumption of a constant hazard rate. Despite this, the exponential distribution remained dominant in fields where memorylessness was a valid assumption, such as survival analysis (where it models the time until an event like death or equipment failure) and financial modeling (where it approximates the time between rare, independent events like defaults). Today, it remains a cornerstone of stochastic processes, though its applications are increasingly supplemented by more flexible distributions like the gamma or Weibull.
Core Mechanisms: How It Works
The exponential distribution’s mechanics hinge on two fundamental properties: its rate parameter λ and its memoryless nature. The rate parameter λ determines the scale of the distribution—higher values compress the curve toward zero, indicating more frequent events, while lower values stretch it out, reflecting rarer occurrences. For instance, if λ = 0.1, the average time between events is 10 units (the reciprocal of λ), but the actual distribution is skewed right, with most events clustering near the mean and a long tail of outliers. This skewness is why the exponential distribution excels at modeling rare but catastrophic events, such as server crashes or financial market shocks.
The memoryless property is perhaps its most counterintuitive feature. Mathematically, it’s expressed as P(X > s + t | X > s) = P(X > t), meaning the probability of an event occurring in the next interval is unchanged by past history. This property arises because the exponential distribution is the only continuous distribution where the hazard rate (the instantaneous rate of failure) is constant. In practice, this implies that exponential models are ideal for systems where components fail randomly, without wear or degradation. However, this assumption breaks down in scenarios with aging effects—such as human mortality or mechanical wear—where the hazard rate increases over time. Recognizing these limitations is crucial; misapplying the exponential distribution in such contexts can lead to underestimating risks or overestimating system lifespans.
Key Benefits and Crucial Impact
The exponential distribution’s simplicity is deceptive—its impact is profound. In risk management, it allows analysts to quantify the likelihood of rare events without relying on extensive historical data, a critical advantage in fields like actuarial science or cybersecurity. For example, insurance companies use exponential models to estimate claim frequencies, while cybersecurity firms apply them to predict the time until a system breach. Its role in queueing theory is equally transformative: from optimizing hospital emergency rooms to designing efficient call centers, the exponential distribution helps balance resource allocation against demand variability. Even in biology, it models the interspike intervals of neuron firing, offering insights into neurological processes.
Beyond its practical applications, the exponential distribution serves as a theoretical bridge between discrete and continuous probability models. It is the continuous counterpart to the geometric distribution, which governs the number of trials until the first success in a Bernoulli process. This duality underscores its foundational role in probability theory, where it often serves as a building block for more complex distributions, such as the gamma or Weibull. Its ability to simplify calculations while capturing essential dynamics makes it a staple in Monte Carlo simulations, where randomness is introduced to model uncertainty in financial, engineering, or scientific scenarios.
"The exponential distribution is the only distribution where the past has no influence on the future—yet this very property is what makes it so dangerous when misapplied. It’s the difference between a model that predicts and one that misleads."
— Dr. Nassim Nicholas Taleb, Antifragile
Major Advantages
- Memoryless Property: Ideal for modeling systems where past events don’t affect future probabilities (e.g., machine failures, Poisson processes). This makes it computationally efficient for real-time applications like network traffic analysis.
- Parameter Efficiency: Requires only one parameter (λ), simplifying model estimation compared to distributions like the normal or gamma, which need two or more.
- Analytical Tractability: Closed-form solutions exist for its PDF, CDF, and moments, enabling quick calculations without numerical approximations.
- Versatility in Modeling Rare Events: Its long right tail accurately represents scenarios with infrequent but high-impact outcomes, such as stock market crashes or equipment failures.
- Foundation for Advanced Distributions: Serves as the basis for the gamma distribution (sum of exponential random variables) and the Weibull distribution (generalized exponential decay), expanding its applicability.

Comparative Analysis
| Exponential Distribution | Normal Distribution |
|---|---|
|
|
|
|
|
|
Future Trends and Innovations
The exponential distribution’s future lies in its integration with machine learning and big data, where its memoryless property can be leveraged to model dynamic systems in real time. For instance, reinforcement learning algorithms increasingly use exponential decay schedules to balance exploration and exploitation, adjusting parameters dynamically as new data arrives. In finance, the rise of alternative data—such as satellite imagery or credit card transactions—is pushing exponential models into new territories, where they help predict defaults or fraud patterns with greater granularity. However, this expansion also demands caution: as datasets grow, the assumption of independence in exponential models may break down, necessitating hybrid approaches that combine exponential distributions with more flexible alternatives like mixture models.
Another frontier is the intersection of exponential distributions with quantum computing. Quantum algorithms for sampling from exponential distributions could revolutionize fields like cryptography, where the generation of exponentially distributed random numbers is critical for simulating security vulnerabilities. Meanwhile, in healthcare, the exponential distribution is being repurposed for personalized medicine, where the time until disease progression or treatment response is modeled using patient-specific hazard rates. These innovations highlight a broader trend: the exponential distribution is evolving from a static tool to a dynamic framework, capable of adapting to the complexities of modern data-driven decision-making.
Conclusion
The exponential distribution is more than a statistical curiosity—it’s a lens through which we understand the unpredictability of the world. Its ability to model memoryless processes has made it indispensable in fields ranging from engineering to epidemiology, yet its limitations remind us that no single model can capture all realities. The key to harnessing its power lies in recognizing where it applies (independent, constant-rate events) and where it fails (systems with aging or correlation). As data grows more complex, the exponential distribution will continue to evolve, but its core principles—simplicity, efficiency, and elegance—will endure.
For professionals, the takeaway is clear: the exponential distribution is not just a tool but a mindset. It teaches us to question assumptions about independence, to value the long tail of rare events, and to balance mathematical convenience with real-world nuance. In an era where models are increasingly scrutinized for their biases and blind spots, understanding the exponential distribution is a step toward building systems that are not only predictive but also robust.
Comprehensive FAQs
Q: How do I determine if an exponential distribution is appropriate for my data?
A: Use statistical tests like the Kolmogorov-Smirnov test or visual tools such as Q-Q plots to compare your data’s empirical distribution to the exponential model. Additionally, check for the memoryless property: if the hazard rate appears constant over time (e.g., failure rates don’t increase with age), the exponential distribution is likely suitable. For systems with aging effects, consider the Weibull or gamma distributions instead.
Q: Why does the exponential distribution have a long right tail, and what does this imply?
A: The long right tail reflects the distribution’s heavy skewness, meaning rare events (e.g., failures after long periods of operation) occur with higher probability than in symmetric distributions like the normal. This implies that while most events cluster near the mean, extreme outliers are more likely, which is critical for risk management—underestimating tail risk can lead to catastrophic losses (e.g., in finance or reliability engineering).
Q: Can the exponential distribution model correlated events?
A: No. The exponential distribution assumes independence between events, making it unsuitable for scenarios where one event increases or decreases the probability of another (e.g., correlated stock market crashes). In such cases, copula models or Markov processes are more appropriate. The memoryless property explicitly breaks down under dependence.
Q: How is the exponential distribution related to the Poisson process?
A: The exponential distribution describes the time between events in a Poisson process, where events occur continuously and independently at a constant average rate. If arrivals follow a Poisson distribution (counting events in fixed intervals), the interarrival times are exponentially distributed. This duality is why the exponential distribution is central to queueing theory and telecommunications modeling.
Q: What are common pitfalls when using the exponential distribution?
A: The three most critical pitfalls are:
1. Assuming constant hazard rates in systems with aging (e.g., human mortality).
2. Ignoring dependence between events (e.g., financial defaults during crises).
3. Over-reliance on the mean without accounting for the heavy tail, which can lead to underestimating extreme risks.
Always validate the model with domain knowledge and residual analysis.
Q: Are there alternatives to the exponential distribution for modeling decay processes?
A: Yes. The Weibull distribution generalizes the exponential by allowing the hazard rate to increase or decrease over time (useful for aging systems). The gamma distribution models the sum of exponential random variables, useful for modeling waiting times in multi-stage processes. For bounded support (e.g., lifetimes), the log-normal or Pareto distributions may be better suited.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.