How the ARIMA Model Revolutionized Time Series Forecasting

The ARIMA model isn’t just another statistical tool—it’s a cornerstone of modern predictive analytics, quietly powering everything from stock market projections to weather forecasting. Unlike black-box algorithms that demand massive datasets, the ARIMA model thrives on the elegance of mathematical simplicity, distilling complex temporal patterns into three core components: autoregression, differencing, and moving averages. Its ability to handle non-stationary data—where trends and seasonality distort raw observations—has made it indispensable for analysts who need reliable forecasts without the computational overhead of deep learning.
Yet for all its dominance, the ARIMA model remains misunderstood. Critics dismiss it as outdated, unaware that its principles underpin more advanced techniques like SARIMA or even neural network architectures. The truth lies in its adaptability: whether you’re modeling daily website traffic or quarterly GDP growth, the ARIMA model adapts by balancing statistical rigor with practical interpretability. This is why it persists as the default choice for time series forecasting—despite the rise of AI.
The ARIMA model’s journey began not in Silicon Valley but in academic labs, where statisticians grappled with data that refused to behave. Its development was a response to a fundamental problem: how to predict future values when past observations were drifting, oscillating, or both. The solution? A framework that could stabilize erratic data through differencing, then model its residuals with autoregressive and moving average terms. What emerged was a method so robust that it became the bedrock of econometrics, finance, and even public health forecasting.
The Complete Overview of the ARIMA Model
The ARIMA model (Autoregressive Integrated Moving Average) is a class of statistical models designed to analyze and forecast time series data. Its strength lies in its ability to capture three critical aspects of temporal data: autocorrelation (how past values influence future ones), trend (long-term movement), and seasonality (repeating patterns). By combining autoregressive (AR) terms, differencing (I) to achieve stationarity, and moving average (MA) terms, the model transforms non-stationary data into a form amenable to regression analysis. This three-stage process—identification, estimation, and diagnostics—ensures forecasts are both mathematically sound and practically useful.
What sets the ARIMA model apart is its flexibility. The "p, d, q" notation (where p = AR lag order, d = differencing order, q = MA lag order) allows practitioners to tailor the model to the data’s specific characteristics. For instance, a financial time series with strong volatility clusters might require a higher q value, while a slowly trending dataset could benefit from a single differencing step (d=1). This adaptability explains why the ARIMA model remains the first tool many analysts reach for, even in an era of machine learning.
Historical Background and Evolution
The origins of the ARIMA model trace back to the early 20th century, when statisticians like Yule and Slutsky laid the groundwork for autoregressive processes. However, it was George Box and Gwilym Jenkins who, in the 1970s, formalized the ARIMA model as a cohesive framework in their seminal work Time Series Analysis: Forecasting and Control. Their "Box-Jenkins methodology" introduced a systematic approach to model selection, diagnostics, and forecasting, which became the gold standard for decades. The model’s evolution was driven by practical needs: economists needed to forecast economic indicators, engineers required process control, and meteorologists sought to predict weather patterns—all with limited computational power.
Table of Contents
- The Complete Overview of the ARIMA Model
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How do I determine the optimal (p, d, q) parameters for an ARIMA model?
- Q: Can the ARIMA model handle seasonality?
- Q: What are common pitfalls when using the ARIMA model?
- Q: How does ARIMA compare to exponential smoothing?
- Q: Is the ARIMA model suitable for high-frequency data (e.g., tick-by-tick financial data)?
The ARIMA model’s ascent coincided with the digital revolution. As computers became more accessible, the computational burden of estimating AR and MA coefficients diminished, making the model accessible to a broader audience. By the 1990s, extensions like Seasonal ARIMA (SARIMA) and ARIMAX (which incorporates exogenous variables) expanded its applicability. Today, while newer methods like Prophet or LSTM networks have gained popularity, the ARIMA model’s principles remain foundational, often serving as benchmarks against which other techniques are measured.
Core Mechanisms: How It Works
At its core, the ARIMA model operates on the premise that past values and errors in a time series contain useful information for forecasting future values. The process begins with stationarity: raw data is rarely stationary, meaning its statistical properties (mean, variance) change over time. To address this, the model applies differencing (d), subtracting observations from their lagged values to remove trends. For example, if a dataset trends upward, first-order differencing (d=1) can stabilize it. Once stationary, the model fits an autoregressive (AR) component, which models the relationship between an observation and a fixed number of lagged observations (p), and a moving average (MA) component, which models the dependency between an observation and residual errors from prior time steps (q).
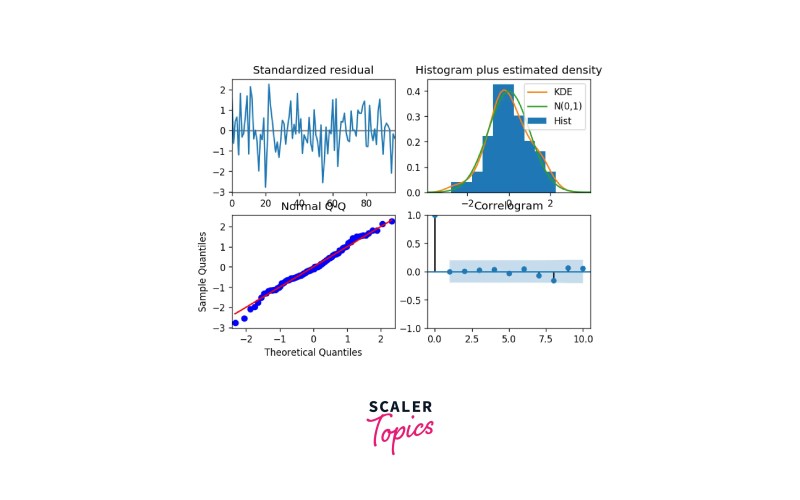
The combination of these components—AR(p), I(d), MA(q)—creates a flexible structure that can model a wide range of temporal patterns. For instance, an AR(1) process assumes the current value depends only on the immediately preceding value, while an MA(1) process assumes the current error depends on the previous error. The model’s parameters are estimated using maximum likelihood or Bayesian methods, ensuring the best fit to the data. Diagnostics like the Ljung-Box test then verify whether residuals exhibit autocorrelation, indicating potential model misspecification. This iterative process—identify, estimate, diagnose—ensures the ARIMA model delivers forecasts that are both statistically valid and actionable.
Key Benefits and Crucial Impact
The ARIMA model’s enduring relevance stems from its ability to deliver high-quality forecasts with minimal data requirements. Unlike machine learning models that demand vast datasets, the ARIMA model can produce meaningful results even with short time series, making it ideal for fields like healthcare (patient monitoring) or small-business analytics. Its interpretability is another major advantage: practitioners can trace forecasts back to specific AR or MA terms, offering transparency that black-box models lack. This clarity is critical in regulated industries, where explainability often outweighs predictive accuracy.
Beyond forecasting, the ARIMA model plays a pivotal role in anomaly detection, demand planning, and risk management. Financial institutions use it to identify market inefficiencies, while retailers leverage it to optimize inventory. Even in public policy, governments rely on ARIMA-based models to predict disease outbreaks or energy consumption. The model’s versatility is matched only by its robustness: it handles missing data gracefully and adapts to changing patterns without requiring retraining.
"The ARIMA model is not just a tool—it’s a philosophy of modeling temporal data with parsimony and precision. Its ability to distill complexity into interpretable parameters is unmatched in the forecasting landscape."
— Dr. Rossman, Stanford University Econometrics
Major Advantages
- Statistical Rigor: The ARIMA model is grounded in probability theory, ensuring forecasts are statistically sound and accompanied by confidence intervals.
- Low Data Dependency: Unlike deep learning models, it performs well with limited data, making it accessible for small-scale applications.
- Interpretability: Each component (AR, I, MA) has a clear interpretation, allowing stakeholders to understand the drivers behind forecasts.
- Computational Efficiency: Estimation and diagnostics are computationally lightweight, enabling real-time applications.
- Adaptability: Extensions like SARIMA or ARIMAX allow it to handle seasonality and exogenous variables, broadening its use cases.

Comparative Analysis
| ARIMA Model | Alternative Methods |
|---|---|
| Best for short-to-medium time series with clear temporal patterns. | Machine learning (e.g., LSTM) excels with large datasets but lacks interpretability. |
| Requires stationarity; differencing is a key step. | Prophet handles seasonality and holidays natively without manual differencing. |
| Parameters (p, d, q) are estimated via statistical methods. | Neural networks use gradient descent, requiring more data and tuning. |
| Works well with missing data if handled properly. | Deep learning models struggle with incomplete or noisy data. |
Future Trends and Innovations
The ARIMA model is far from obsolete; instead, it is evolving in tandem with modern data science. Hybrid approaches, such as combining ARIMA with machine learning, are emerging to leverage the strengths of both paradigms. For example, ARIMA can provide initial forecasts, which are then refined by neural networks for higher accuracy. Additionally, advancements in automated model selection—using techniques like Bayesian optimization—are reducing the manual effort required to tune p, d, and q parameters. These innovations ensure the ARIMA model remains relevant in an era dominated by big data and AI.
Another frontier is the integration of ARIMA model principles into real-time systems. As IoT devices generate continuous streams of data, lightweight ARIMA variants are being developed to process and forecast in near real-time. Furthermore, research into non-linear ARIMA extensions (e.g., threshold ARIMA) is expanding its applicability to complex, non-stationary systems. The future of the ARIMA model lies not in replacement but in refinement—adapting to new challenges while retaining its core strengths.
Conclusion
The ARIMA model stands as a testament to the power of statistical thinking in an age of algorithmic complexity. Its ability to transform noisy, non-stationary data into actionable insights has cemented its place as a foundational tool in forecasting. While newer methods may offer incremental improvements in specific contexts, the ARIMA model’s balance of simplicity, interpretability, and performance ensures its continued relevance. For practitioners, the key takeaway is not whether to use it but how to wield it effectively—combining domain knowledge with statistical rigor to extract maximum value from temporal data.
As data grows more abundant and models grow more sophisticated, the ARIMA model will likely remain a cornerstone of time series analysis. Its principles will continue to inspire innovations, proving that sometimes, the most elegant solutions are those built on decades of mathematical tradition.
Comprehensive FAQs
Q: How do I determine the optimal (p, d, q) parameters for an ARIMA model?
A: The selection of p, d, and q is typically guided by the ARIMA model's identification phase. Start by testing for stationarity (e.g., using the Augmented Dickey-Fuller test) to determine d. Then, use autocorrelation function (ACF) and partial autocorrelation function (PACF) plots to estimate p and q. Tools like the Akaike Information Criterion (AIC) or Bayesian Information Criterion (BIC) can help compare candidate models. Automated libraries (e.g., Python’s `pmdarima`) streamline this process by searching over possible combinations.
Q: Can the ARIMA model handle seasonality?
A: The basic ARIMA model does not account for seasonality, but extensions like Seasonal ARIMA (SARIMA) add seasonal components (P, D, Q) to the model. SARIMA incorporates seasonal differencing and seasonal AR/MA terms, making it suitable for data with repeating patterns (e.g., monthly sales with yearly cycles). For more complex seasonality, hybrid models (e.g., ARIMA + Fourier terms) or Prophet may be preferable.
Q: What are common pitfalls when using the ARIMA model?
A: Overfitting is a frequent issue, especially when p or q are too high. Another pitfall is assuming stationarity without proper differencing, leading to spurious regressions. Ignoring residual diagnostics (e.g., autocorrelation in residuals) can result in unreliable forecasts. Additionally, the ARIMA model struggles with structural breaks (sudden shifts in data-generating processes), which may require interventions or alternative models like structural time series.
Q: How does ARIMA compare to exponential smoothing?
A: Both methods are used for time series forecasting, but they differ in approach. Exponential smoothing (e.g., Holt-Winters) is simpler and works well for data with trend and seasonality but assumes a fixed decay rate for past observations. The ARIMA model, however, is more flexible, handling non-linear patterns and providing statistical inference. For datasets with clear trends and seasonality, exponential smoothing may suffice, while ARIMA is preferred for complex, non-stationary data.
Q: Is the ARIMA model suitable for high-frequency data (e.g., tick-by-tick financial data)?
A: The ARIMA model can be applied to high-frequency data, but its effectiveness depends on the data’s properties. For financial tick data, volatility clustering and non-stationarity often require extensions like GARCH or fractional differencing. Additionally, computational constraints may arise with very high frequencies, making models like LSTM or wavelet-based methods more practical. However, ARIMA remains useful for aggregated (e.g., daily) financial time series.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.