Debugging ValueError: Setting Array Elements with Sequences—A Deep Technical Breakdown
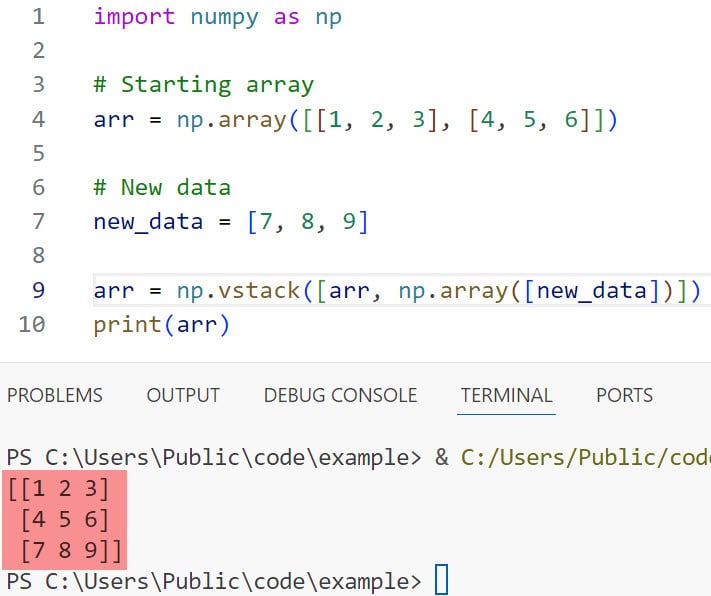
The `ValueError: setting an array element with a sequence` error is one of Python’s most cryptic yet common pitfalls for developers working with arrays—especially in numerical computing. Unlike syntax errors that halt execution immediately, this runtime exception often surfaces during data manipulation, where a sequence (like a list or tuple) is mistakenly assigned to an individual array element. The confusion stems from Python’s strict type system: arrays expect scalar values, not nested structures. Even experienced data scientists and engineers frequently encounter this when transitioning from lists to NumPy arrays or Pandas Series, where indexing semantics diverge sharply.
At its core, the error exposes a fundamental mismatch between Python’s dynamic typing and the rigid structure of array-based operations. For instance, attempting to assign `[1, 2]` to `array[0]` fails because the array expects a single integer, not a sequence. This distinction becomes critical in high-performance computing, where arrays are optimized for homogeneous data. The error’s ambiguity—arising from implicit conversions or misaligned dimensions—often obscures the actual logical flaw in the code, demanding a systematic approach to diagnosis.
The problem escalates in collaborative environments where data pipelines mix Python lists with array libraries (e.g., NumPy, TensorFlow). A developer might pass a list of lists to a function expecting a 2D array, triggering the `ValueError` when the function tries to unpack sequences into scalar positions. Without proper validation, such issues propagate through machine learning workflows, financial modeling, or scientific simulations, where data integrity is paramount.
The Complete Overview of "ValueError: Setting an Array Element with a Sequence"
This error is a direct consequence of Python’s array libraries enforcing type consistency. Unlike lists, which can hold mixed types, arrays (via NumPy or similar) require all elements to conform to a predefined dtype (e.g., `int32`, `float64`). When a sequence is assigned to a single element, the interpreter raises `ValueError` because it cannot determine how to flatten or interpret the sequence as a scalar. The error’s phrasing—"setting an array element with a sequence"—hints at the root cause: the operation violates the array’s dimensionality rules.The issue manifests in three primary scenarios:
1. Direct Assignment: Assigning a list/tuple to an array index (e.g., `arr[0] = [1, 2]`).
2. Implicit Conversion: Passing a sequence to a function expecting a scalar (e.g., `np.where(condition, [1, 2], 0)`).
3. Broadcasting Failures: Attempting to assign a multi-dimensional sequence to a 1D array slot.
Understanding these scenarios is critical, as the error often masks deeper architectural problems, such as incorrect data preprocessing or misaligned tensor operations in deep learning frameworks.
Historical Background and Evolution
The `ValueError` for sequence assignment traces back to Python’s early array modules, notably `Numeric` and `numarray`, which predated NumPy. These libraries introduced strict typing to optimize numerical operations, but their error messages were less descriptive. NumPy (released in 2006) refined the messaging but retained the core issue: arrays are designed for homogeneous, scalar data. The error’s persistence reflects a trade-off between flexibility and performance—NumPy prioritizes speed over dynamic typing, forcing developers to adhere to its structural constraints.Table of Contents
- The Complete Overview of "ValueError: Setting an Array Element with a Sequence"
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Why does `arr[0] = [1, 2]` raise `ValueError` but `arr[0:2] = [1, 2]` work?
- Q: Can I suppress this error to allow sequence assignment?
- Q: How does this error differ from `TypeError` in array assignment?
- Q: What’s the best way to debug this error in a large codebase?
- Q: Does this error occur in other languages (e.g., R, Julia)?
- Q: How can I prevent this error when reading data from CSV?
Over time, the error became a rite of passage for Python data scientists. Early adopters of libraries like SciPy or Pandas encountered it frequently when migrating from R or MATLAB, where array indexing behaves differently. For example, R’s `matrix` allows mixed types in cells, while NumPy arrays do not. This cultural shift—from permissive to strict typing—explains why the error remains a staple in debugging tutorials, despite Python’s evolution.
Core Mechanisms: How It Works
The error occurs when the Python interpreter attempts to assign a sequence to an array element that expects a scalar. Internally, NumPy’s `__setitem__` method checks the assigned value’s shape and dtype against the target array’s structure. If the sequence’s shape is incompatible (e.g., a 2-element list assigned to a 1D array), NumPy raises `ValueError`. The key distinction lies in broadcasting rules: sequences can only be assigned if they can be reshaped to match the target’s dimensionality without ambiguity.For instance:
```python
import numpy as np
arr = np.array([1, 2, 3]) # 1D array
arr[0] = [4, 5] # Raises ValueError: setting an array element with a sequence
```
Here, `[4, 5]` is a 1D sequence of length 2, but `arr[0]` expects a scalar. NumPy cannot infer how to split `[4, 5]` into the array’s existing structure. The solution requires explicit reshaping or scalar extraction (e.g., `arr[0] = 4` or `arr[0:2] = [4, 5]`).
Key Benefits and Crucial Impact
Resolving this error isn’t just about fixing syntax—it’s about aligning code with the underlying computational model. Arrays optimize for performance by enforcing homogeneity, so the `ValueError` serves as a safeguard against inefficient or incorrect operations. For example, a data scientist processing sensor data might accidentally assign a list of readings to a single timestamp slot, corrupting the entire dataset. The error prevents such catastrophes by enforcing explicit, dimension-aware assignments.Moreover, understanding the error’s mechanics improves code maintainability. When developers anticipate where sequences might conflict with scalar expectations, they can implement early validation (e.g., using `np.isscalar()`). This proactive approach reduces debugging time in large-scale projects, where array operations are nested across multiple functions.
"Arrays are not lists. They are a different abstraction entirely—one that demands precision in type and shape. TheValueErroris Python’s way of saying, 'You’re trying to bend the rules of this system.' Ignore it, and you’ll pay the price in performance or correctness."
— Robert Kern, NumPy Core Developer
Major Advantages
- Performance Optimization: Arrays enforce data locality and contiguous memory, which the `ValueError` helps preserve by rejecting inefficient assignments (e.g., storing lists inside arrays).
- Memory Efficiency: Homogeneous arrays reduce overhead compared to Python lists, which store type pointers for each element. The error prevents accidental memory bloat.
- Debugging Clarity: Explicit errors like this one pinpoint logical flaws early, unlike silent failures that manifest later in execution (e.g., incorrect model predictions due to misassigned data).
- Library Compatibility: Many scientific libraries (e.g., TensorFlow, PyTorch) rely on NumPy’s array semantics. Resolving this error ensures interoperability across the Python data ecosystem.
- Scalability: Arrays are the backbone of parallel computing. The `ValueError` ensures operations are dimensionally consistent, which is critical for distributed systems like Dask or Spark.

Comparative Analysis
| Scenario | Python Lists | NumPy Arrays |
|---|---|---|
| Mixed Data Types | Allowed (e.g., `[1, "hello", 3.14]`) | Not allowed (raises `ValueError` or `TypeError`) |
| Sequence Assignment to Element | Allowed (e.g., `lst[0] = [1, 2]`) | Raises `ValueError: setting an array element with a sequence` |
| Broadcasting Rules | N/A (lists are not broadcastable) | Strict (e.g., `arr[0:2] = [1, 2]` works, but `arr[0] = [1, 2]` fails) |
| Performance for Numerical Work | Slow (dynamic typing overhead) | Fast (contiguous memory, SIMD optimizations) |
Future Trends and Innovations
As Python’s data ecosystem evolves, the `ValueError` may become less common due to:1. Improved Type Hints: Libraries like `typing_extensions` and `numpy.typing` are adding static type checking, catching dimension mismatches before runtime.
2. JIT Compilation: Tools like Numba or PyTorch’s TorchScript can optimize array operations while preserving safety checks.
3. Hybrid Data Structures: Frameworks like Apache Arrow or Polars are introducing more flexible array-like structures that balance performance and type safety.
However, the error’s persistence underscores a fundamental tension: performance versus flexibility. For numerical computing, strict arrays remain indispensable, but future languages (e.g., Julia) may offer middle-ground solutions that reduce such errors without sacrificing speed.

Conclusion
The `ValueError: setting an array element with a sequence` is more than a syntax quirk—it’s a reflection of Python’s design philosophy for numerical computing. By enforcing strict type and shape rules, arrays achieve unparalleled performance, but they demand discipline from developers. The error’s frequency in data science pipelines highlights the need for rigorous validation, especially when integrating lists with array operations.Moving forward, developers should adopt defensive programming practices: validate inputs with `np.isscalar()`, use `np.atleast_1d()` for shape consistency, and leverage static type checkers. These habits will not only resolve the error but also future-proof code against evolving library standards.
Comprehensive FAQs
Q: Why does `arr[0] = [1, 2]` raise `ValueError` but `arr[0:2] = [1, 2]` work?
The difference lies in dimensionality. `arr[0]` refers to a single element (0D), which cannot hold a sequence. `arr[0:2]` selects a slice (1D or higher), which can be assigned a sequence of matching length. NumPy’s indexing rules prioritize shape compatibility over scalar assignment.
Q: Can I suppress this error to allow sequence assignment?
No, and you shouldn’t. Suppressing the error (e.g., with `try-except`) masks deeper logical issues. Instead, reshape your data explicitly using `np.reshape()` or `np.broadcast_to()` to ensure compatibility.
Q: How does this error differ from `TypeError` in array assignment?
`ValueError` occurs when the assigned value is a sequence but the target expects a scalar. `TypeError` arises when the value’s type is incompatible (e.g., assigning a string to an integer array). The former is about shape, the latter about dtype.
Q: What’s the best way to debug this error in a large codebase?
Use `np.array()` to inspect shapes and dtypes at each step. For example:
```python
print("Shape:", data.shape, "Dtype:", data.dtype)
```
This reveals where sequences might conflict with scalar expectations. Tools like `pdb` or `icecream` can log intermediate states.
Q: Does this error occur in other languages (e.g., R, Julia)?
Yes, but with different phrasing. R’s `matrix` allows mixed types but raises warnings for non-conformable assignments. Julia’s `Array` is stricter, often throwing `DimensionMismatch` or `MethodError` for similar cases. The core issue—dimensional inconsistency—is universal.
Q: How can I prevent this error when reading data from CSV?
Use `pd.read_csv()` with `dtype` and `convert_dtypes=True` to enforce homogeneity. For NumPy, preprocess with:
```python
data = np.genfromtxt("file.csv", dtype=float, delimiter=",")
```
This ensures all values are scalars before array creation.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.