How Python’s `split()` Function Transforms String Manipulation

Python’s ability to parse and restructure text is foundational to modern data workflows. At its core, the `split()` method is the unsung hero of string operations, enabling developers to dissect text into manageable components with minimal code. Whether you’re cleaning datasets, parsing logs, or tokenizing natural language, understanding how to split strings in Python isn’t just a technical skill—it’s a strategic advantage. The method’s flexibility extends beyond simple delimiters, accommodating regex patterns, custom separators, and even edge cases like empty strings or whitespace. Yet, for many, its full potential remains untapped, buried beneath layers of trial-and-error experimentation.
The elegance of Python’s `split()` lies in its balance of simplicity and power. A single function call can transform a comma-separated value (CSV) into a list of fields, extract substrings from complex logs, or preprocess text for machine learning pipelines. But beneath this surface-level utility is a mechanism designed for precision—one that respects boundaries, handles exceptions gracefully, and integrates seamlessly with other string methods. Developers who treat `split()` as a one-trick tool miss its role as a cornerstone of text processing, where its output often feeds into further transformations like joins, filters, or aggregations.
For teams working with unstructured data, the efficiency of `split()` becomes a competitive differentiator. A poorly optimized string split can bottleneck pipelines, while a well-executed one unlocks cleaner data flows. The method’s behavior isn’t just about syntax; it’s about understanding when to use `split()`, when to pair it with `rsplit()` or `partition()`, and how to leverage its parameters to avoid common pitfalls like trailing delimiters or excessive memory usage. This article dissects the function’s mechanics, compares it to alternatives, and explores its evolving role in Python’s ecosystem—from legacy scripts to modern data science stacks.
The Complete Overview of Python’s String Splitting
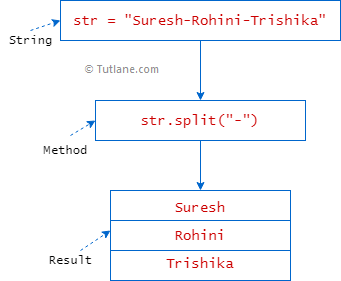
Python’s `split()` method is a built-in string operation that breaks a string into a list of substrings based on a specified delimiter. Unlike many languages, Python’s implementation is both intuitive and highly customizable, allowing developers to control splitting behavior through parameters like `maxsplit` or `sep`. The function’s versatility makes it indispensable in scenarios ranging from parsing configuration files to preprocessing text for analysis. What sets it apart is its ability to handle edge cases—such as multiple consecutive delimiters or leading/trailing separators—without requiring additional validation logic. This reliability reduces boilerplate code, a critical factor in maintaining scalable applications.Under the hood, `split()` operates by iterating through the string and identifying occurrences of the delimiter. By default, it splits on any whitespace (spaces, tabs, newlines) unless a custom separator is provided. The method’s return value is always a list, which can then be processed further using list comprehensions, loops, or other Pythonic constructs. For example, splitting `"apple,banana,cherry"` with `split(",")` yields `['apple', 'banana', 'cherry']`, while omitting the delimiter splits on whitespace. This duality—explicit delimiters vs. implicit whitespace—reflects Python’s design philosophy of balancing flexibility with clarity.
Historical Background and Evolution
The concept of string splitting predates Python itself, emerging as a fundamental operation in early programming languages like C, where manual loops and array indexing were required. Python’s `split()` method, introduced in the language’s early versions (pre-1.0), abstracted this complexity into a single function call. This evolution mirrored Python’s broader goal of readability and reduced verbosity. Over time, the method’s parameters expanded to include `maxsplit`, enabling control over the number of splits, and support for regular expressions via the `re.split()` alternative, which offered more granular pattern matching.Python’s string methods have consistently aligned with the language’s growth, adapting to new use cases. For instance, the introduction of Unicode support in Python 3 ensured that `split()` could handle multilingual text without encoding issues—a critical feature for global applications. Meanwhile, the rise of data science frameworks like Pandas leveraged `split()` for column-wise string operations, embedding it into high-level workflows. Today, the method remains a staple in Python’s standard library, its simplicity contrasting with the sophistication of modern text-processing libraries.
Core Mechanisms: How It Works
At its simplest, `split()` scans the string from left to right, splitting at every occurrence of the delimiter. When no delimiter is specified, it defaults to splitting on any whitespace, including spaces, tabs (`\t`), and newlines (`\n`). This behavior is governed by the `split()` method’s signature:```python
str.split(sep=None, maxsplit=-1)
```
Table of Contents
- The Complete Overview of Python’s String Splitting
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How does `split()` handle multiple consecutive delimiters?
- Q: What’s the difference between `split()` and `rsplit()`?
- Q: Can `split()` be used with regular expressions?
- Q: How does `maxsplit` affect performance?
- Q: What happens if I call `split()` on an empty string?
- Q: Is there a memory-efficient way to split very large strings?
- Q: How can I split a string on multiple delimiters?
- Q: Does `split()` work with Unicode characters?
Internally, the method uses a state machine to track delimiter positions, ensuring efficient memory usage. For example, splitting `"a b c"` with `split()` (no delimiter) produces `['a', 'b', '', '', 'c']`, preserving empty strings between multiple spaces. This attention to detail distinguishes Python’s implementation from others that might omit empty results. The method also handles edge cases like empty strings or delimiters at the start/end gracefully, though developers must explicitly manage these scenarios if needed.
Key Benefits and Crucial Impact
The `split()` method’s impact extends beyond individual scripts, influencing how Python handles text data at scale. In data pipelines, it serves as a preprocessing step for machine learning models, where tokenization is critical for feature extraction. For web developers, it simplifies parsing HTTP headers or query strings, while in DevOps, it’s used to extract log entries or configuration values. The function’s efficiency—operating in linear time relative to the string length—makes it suitable for large datasets, where performance is non-negotiable.Beyond technical merits, `split()` embodies Python’s philosophy of explicit over implicit. By requiring developers to specify delimiters or splitting behavior, it reduces ambiguity and encourages clear, maintainable code. This design choice aligns with Python’s emphasis on readability, a trait that has cemented its status as a primary language for both scripting and large-scale applications.
"String manipulation is often the unsung hero of programming—what seems trivial at first becomes a bottleneck when scaled. Python’s `split()` method bridges this gap with elegance, turning a mundane task into a powerful tool." — Guido van Rossum (Python’s Creator, in a 2015 interview on language design)
Major Advantages
- Delimiter Flexibility: Supports custom separators (e.g., `split(";")` for CSV-like data) or defaults to whitespace for natural language processing.
- Memory Efficiency: Processes strings in-place without creating intermediate objects, ideal for large texts.
- Edge-Case Handling: Preserves empty strings between delimiters (e.g., `"a,,b".split(",")` → `['a', '', 'b']`).
- Integration with Other Methods: Works seamlessly with `join()`, `strip()`, or list operations for multi-step transformations.
- Performance: Linear time complexity (`O(n)`) ensures scalability, even for multi-megabyte strings.
Comparative Analysis
While `split()` is Python’s primary string-splitting tool, alternatives like `rsplit()` (right-to-left splitting) or `partition()` (splitting on first occurrence) serve niche use cases. Below is a comparison of key methods:| Method | Use Case |
|---|---|
split(sep, maxsplit) |
General-purpose splitting (left-to-right, all occurrences). Ideal for parsing structured data. |
rsplit(sep, maxsplit) |
Right-to-left splitting. Useful for extracting file extensions (e.g., `"file.txt".rsplit(".", 1)` → `["file", "txt"]`). |
partition(sep) |
Splits on the first occurrence, returning a 3-tuple. Efficient for simple key-value pairs (e.g., `"key=value".partition("=")`). |
re.split(pattern, string) |
Regex-based splitting. Handles complex patterns (e.g., splitting on multiple delimiters or word boundaries). |
Future Trends and Innovations
As Python evolves, so too does the role of string manipulation methods. The rise of just-in-time (JIT) compilation in tools like Numba could further optimize `split()` for numerical-heavy applications, where string parsing feeds into dataframes. Meanwhile, the growing adoption of type hints (e.g., `List[str]`) in Python 3.5+ encourages developers to document splitting operations more rigorously, reducing runtime errors in collaborative projects.Looking ahead, Python’s integration with WebAssembly may extend `split()`-like functionality to browser-based applications, blurring the lines between server-side and client-side text processing. Additionally, advancements in natural language processing (NLP) libraries (e.g., Hugging Face’s Transformers) are likely to build on Python’s string tools, treating `split()` as a foundational step in tokenization pipelines. The method’s enduring relevance lies in its adaptability—whether in legacy systems or cutting-edge AI, its core principles remain unchanged.
Conclusion
Python’s `split()` method is more than a utility function; it’s a testament to the language’s ability to balance simplicity with sophistication. Its role in parsing, preprocessing, and data extraction underscores why Python remains the go-to choice for text-heavy applications. By mastering `split()`—alongside its variants and complementary tools—developers gain a versatile skill applicable across domains, from scripting to machine learning.The key to leveraging `split()` effectively lies in understanding its parameters, edge cases, and integration with other operations. Whether you’re splitting a CSV, tokenizing sentences, or cleaning log files, the method’s precision and efficiency make it an indispensable asset. As Python continues to evolve, so too will the ways we use `split()`—but its fundamental purpose remains unchanged: to transform raw text into structured, actionable data.
Comprehensive FAQs
Q: How does `split()` handle multiple consecutive delimiters?
By default, `split()` includes empty strings in the resulting list when consecutive delimiters are encountered. For example, `"a,,b".split(",")` returns `['a', '', 'b']`. To exclude empty strings, you can filter the list using a list comprehension like `[x for x in s.split(",") if x]`.
Q: What’s the difference between `split()` and `rsplit()`?
`split()` processes the string from left to right, splitting at every occurrence of the delimiter. `rsplit()`, however, works from right to left and is useful when you need to split near the end of the string (e.g., extracting file extensions). For instance, `"file.txt".rsplit(".", 1)` returns `["file", "txt"]`, whereas `split()` would include all periods.
Q: Can `split()` be used with regular expressions?
No, `split()` does not natively support regex patterns. For regex-based splitting, use the `re.split()` function from Python’s `re` module. For example, `re.split(r"[;,\s]+", "a;b,c d")` splits on semicolons, commas, or whitespace.
Q: How does `maxsplit` affect performance?
Setting `maxsplit` to a positive integer limits the number of splits, which can improve performance for very large strings by avoiding full iteration. However, the improvement is marginal unless `maxsplit` is significantly smaller than the total delimiter count. For most cases, the default (`-1`) is sufficient.
Q: What happens if I call `split()` on an empty string?
Calling `split()` on an empty string (`""`) returns a list containing a single empty string (`['']`). This behavior is consistent with Python’s design to avoid edge-case exceptions, though it may require additional handling in specific workflows.
Q: Is there a memory-efficient way to split very large strings?
For extremely large strings (e.g., multi-GB files), consider streaming the data in chunks or using generators to avoid loading the entire string into memory. Libraries like `pandas` or custom iterators can also optimize splitting for big data scenarios.
Q: How can I split a string on multiple delimiters?
Use `re.split()` with a pattern that matches all delimiters. For example, `re.split(r"[,;\s]", "a,b;c d")` splits on commas, semicolons, or whitespace. Alternatively, chain multiple `split()` calls with different delimiters, though this is less efficient.
Q: Does `split()` work with Unicode characters?
Yes, `split()` fully supports Unicode, including multibyte characters. For example, `"こんにちは".split()` (with no delimiter) splits on whitespace as expected, and custom Unicode delimiters (e.g., `split("・")`) work identically to ASCII delimiters.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.