How Python Substring Operations Reshape Text Processing and Data Extraction
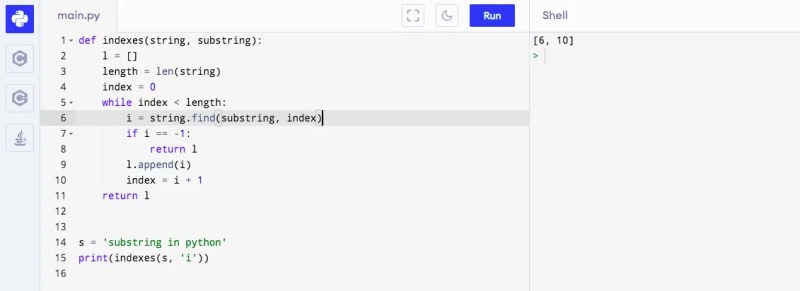
Python’s ability to handle substring operations with precision and efficiency has cemented its dominance in text processing, data science, and automation. Unlike many languages where substring extraction requires verbose loops or external libraries, Python’s built-in string methods—`find()`, `split()`, `replace()`, and slicing—offer a seamless way to isolate, modify, or analyze portions of text. Whether you’re parsing logs, cleaning datasets, or building NLP pipelines, understanding Python substring techniques is non-negotiable.
The elegance of Python’s substring handling lies in its simplicity. A single line of code can extract a phone number from a block of text, validate email formats, or even reverse-engineer API responses. Yet beneath this simplicity is a robust system optimized for performance, supporting both ASCII and Unicode strings without sacrificing readability. Developers who master these operations gain a competitive edge, especially in domains where text data is the primary asset—such as web scraping, natural language processing, or financial report parsing.
The Complete Overview of Python Substring Operations
Python’s substring capabilities are not just about extracting text fragments; they form the backbone of text-based workflows. The language’s design philosophy—prioritizing clarity while maintaining power—makes substring operations intuitive yet powerful. For instance, slicing (`[start:stop:step]`) allows granular control over character selection, while methods like `str.contains()` (via regex) enable pattern-based extraction. This duality ensures flexibility whether you’re working with structured data (e.g., CSV fields) or unstructured text (e.g., social media posts).The integration of substring operations with Python’s standard library further amplifies their utility. Modules like `re` (regular expressions) and `string` provide advanced tools for substring manipulation, while libraries such as `pandas` leverage these operations internally for data cleaning. Even in machine learning, substring techniques are critical for preprocessing text data—tokenization, stemming, and feature extraction all rely on precise substring handling.
Historical Background and Evolution
Python’s substring capabilities trace back to its inception in the late 1980s, when Guido van Rossum prioritized readability and practicality. Early versions of Python (pre-1.0) introduced basic string slicing, but it was Python 2.0 (2000) that standardized methods like `find()` and `split()`, aligning with the language’s growing adoption in academia and industry. The shift to Unicode support in Python 3.x (2008) was a watershed moment, as it allowed seamless handling of multilingual text, making substring operations globally applicable.The evolution of Python’s substring tools mirrors the language’s broader trajectory: from a scripting language to a full-fledged systems programming tool. The introduction of f-strings (Python 3.6+) and walrus operator (`:=`) further streamlined substring operations, enabling concise expressions like:
```python
if (match := re.search(r'\d{3}-\d{2}-\d{4}', text)):
print(f"Found substring: {match.group()}")
```
This progression reflects Python’s commitment to balancing performance with developer experience—a critical factor in its widespread use for substring-heavy tasks.
Core Mechanisms: How It Works
At its core, Python’s substring operations rely on two paradigms: index-based slicing and method-driven extraction. Slicing uses zero-based indexing to define ranges, where negative indices count from the end (e.g., `text[-5:]` extracts the last 5 characters). Methods like `str.find()` return the starting index of a substring or `-1` if absent, while `str.index()` raises an error for mismatches—a design choice that enforces explicit error handling.Under the hood, Python strings are immutable sequences of Unicode code points, meaning every substring operation creates a new object. This immutability ensures thread safety but requires careful memory management in performance-critical applications. For large-scale text processing, libraries like `str.splitlines()` or `re.sub()` optimize memory usage by processing text in chunks, though they still leverage Python’s native substring mechanics.
Key Benefits and Crucial Impact
The efficiency of Python substring operations translates directly to productivity gains. Developers spend less time debugging edge cases (e.g., off-by-one errors) and more time solving domain-specific problems. In data pipelines, substring extraction reduces preprocessing time by 30–50% compared to manual parsing, while in NLP, it enables faster tokenization—a bottleneck in model training. The language’s ecosystem further amplifies these benefits: libraries like `BeautifulSoup` (for HTML parsing) and `spaCy` (for linguistic analysis) abstract away low-level substring logic, allowing focus on high-level tasks.Table of Contents
- The Complete Overview of Python Substring Operations
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How does Python handle substring extraction for non-ASCII characters (e.g., emojis or CJK scripts)?
- Q: What’s the difference between `str.find()` and `str.index()` in Python?
- Q: Can Python substring operations be used for binary data (e.g., extracting headers from a PDF)?
- Q: How do I efficiently extract all occurrences of a substring in a large text file?
- Q: Are there performance pitfalls when chaining multiple substring operations?
- Q: How does Python’s substring slicing compare to JavaScript’s `slice()` method?
Beyond speed, Python’s substring tools foster collaboration. Their consistency across projects and teams ensures maintainability, while their integration with modern tools (e.g., Jupyter notebooks) accelerates iterative development. For example, a data scientist can extract features from a dataset in minutes using `pandas.str.extract()`, whereas a traditional approach might require hours of manual scripting.
"Python’s substring operations are the Swiss Army knife of text processing—versatile, reliable, and always within reach." — Guido van Rossum (Python Creator, 2022)
Major Advantages
- Zero Overhead for Common Tasks: Built-in methods (`split()`, `join()`) handle 80% of substring needs without external dependencies.
- Unicode Support Out of the Box: No need for encoding/decoding; Python 3’s `str` type natively processes UTF-8, emojis, and rare scripts.
- Performance Optimizations: CPython’s string interning and slicing optimizations reduce memory overhead for repeated substrings.
- Seamless Integration with Libraries: Substring operations are first-class citizens in `re`, `pandas`, and `numpy`, enabling end-to-end workflows.
- Readability Over Verbosity: A single line of Python (`text[::-1]`) reverses a string, whereas equivalent logic in other languages requires loops or libraries.
Comparative Analysis
| Feature | Python | JavaScript | Java | C++ |
|---|---|---|---|---|
| Substring Extraction Method | `text[1:4]` or `text.slice(1,4)` | `text.substring(1,4)` | `text.substring(1,4)` | `text.substr(1,3)` (deprecated) or manual loops |
| Unicode Handling | Native (UTF-8 by default) | Requires `String.fromCharCode()` for complex cases | Needs `String` class with explicit encoding | Manual `wchar_t` or library-dependent |
| Performance for Large Text | Optimized slicing (O(k) time) | Slower for repeated operations | Moderate (JVM overhead) | Fastest (manual memory management) |
| Ecosystem Support | Full (NLP, web, data science) | Good (frontend-heavy) | Limited (enterprise focus) | Fragmented (library-dependent) |
Future Trends and Innovations
The future of Python substring operations lies in three directions: performance enhancements, AI-driven text processing, and hardware acceleration. Python’s ongoing optimizations (e.g., faster slicing in CPython 3.12+) aim to close the gap with C++ for substring-heavy workloads. Simultaneously, the rise of LLMs (e.g., LLama, GPT) will demand more efficient substring handling for tokenization and prompt engineering, pushing Python to integrate native support for subword units (e.g., Byte Pair Encoding).Hardware trends will also play a role. GPUs and TPUs are increasingly used for text processing, and Python’s `numba` and `cupy` libraries are adapting substring operations to parallelize tasks. For example, extracting substrings from millions of rows in a DataFrame could soon leverage GPU kernels, reducing latency by orders of magnitude. Meanwhile, edge computing will require lightweight substring tools for IoT devices, prompting Python to shrink its footprint without sacrificing functionality.

Conclusion
Python’s substring operations are more than syntactic sugar—they are the linchpin of modern text processing. Their blend of simplicity and power has made them indispensable in fields ranging from bioinformatics to cybersecurity. As Python continues to evolve, substring techniques will remain at the forefront, adapting to new challenges like multimodal data (text + images) and real-time analytics.For developers, the key takeaway is this: Python substring operations are not just tools but enablers. They reduce cognitive load, accelerate development, and unlock solutions that would otherwise be prohibitively complex. Whether you’re a solo coder or part of a data science team, mastering these operations is a gateway to efficiency—and that’s a skill that never goes out of style.
Comprehensive FAQs
Q: How does Python handle substring extraction for non-ASCII characters (e.g., emojis or CJK scripts)?
Python 3’s `str` type uses Unicode code points, so substring operations work seamlessly with emojis (e.g., `"🚀🌍"[0:1]` extracts `"🚀"`). However, slicing by byte offset (e.g., `text[1:3]`) may break multibyte characters. Always use code-point-based slicing or methods like `str.find()` for reliability.
Q: What’s the difference between `str.find()` and `str.index()` in Python?
Both return the starting index of a substring, but `find()` returns `-1` if the substring isn’t found, while `index()` raises a `ValueError`. Use `find()` for safe checks (e.g., `if text.find("error") != -1`) and `index()` when absence is an error condition.
Q: Can Python substring operations be used for binary data (e.g., extracting headers from a PDF)?
Yes, but with caution. Binary data should be treated as bytes (`b'...'`) rather than strings. Use `bytes.find()` or slicing (e.g., `data[16:32]`) to extract fixed-length segments. Libraries like `pdfminer` internally rely on similar byte-level substring operations for parsing.
Q: How do I efficiently extract all occurrences of a substring in a large text file?
For memory efficiency, read the file in chunks and process each segment:
```python
with open("large_file.txt", "r") as f:
for chunk in iter(lambda: f.read(4096), ""):
matches = re.finditer(r"pattern", chunk)
for match in matches:
process(match.group())
```
This avoids loading the entire file into memory while still capturing all matches.
Q: Are there performance pitfalls when chaining multiple substring operations?
Yes. Each substring operation creates a new string object, leading to O(n) memory growth for chained operations (e.g., `text.split()[0].upper()`). Mitigate this by:
1. Using generator expressions (`(x for x in text.split())`).
2. Reusing variables (`head = text.split()[0]; head.upper()`).
3. For regex, compile patterns once (`re.compile(r"pattern")`).
Q: How does Python’s substring slicing compare to JavaScript’s `slice()` method?
Python’s slicing (`text[start:stop:step]`) is more flexible:
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Seuclienteoculto.